Chain of Thought for Humans(boristhebrave.com)
109 points by ibobev | 54 comments
Blog post describing how narrating one's thoughts aloud, like LLM chain-of-thought or rubber duck debugging, improved the author's puzzle solving in The Witness.
11 stories tagged chain-of-thought, newest first.
109 points by ibobev | 54 comments
Blog post describing how narrating one's thoughts aloud, like LLM chain-of-thought or rubber duck debugging, improved the author's puzzle solving in The Witness.
491 points by ModelForge | 158 comments
Sebastian Raschka's Ahead of AI newsletter post examining OpenAI's GPT-6 Astra, looped transformers with recurrent depth, and hidden chain-of-thought reasoning research.
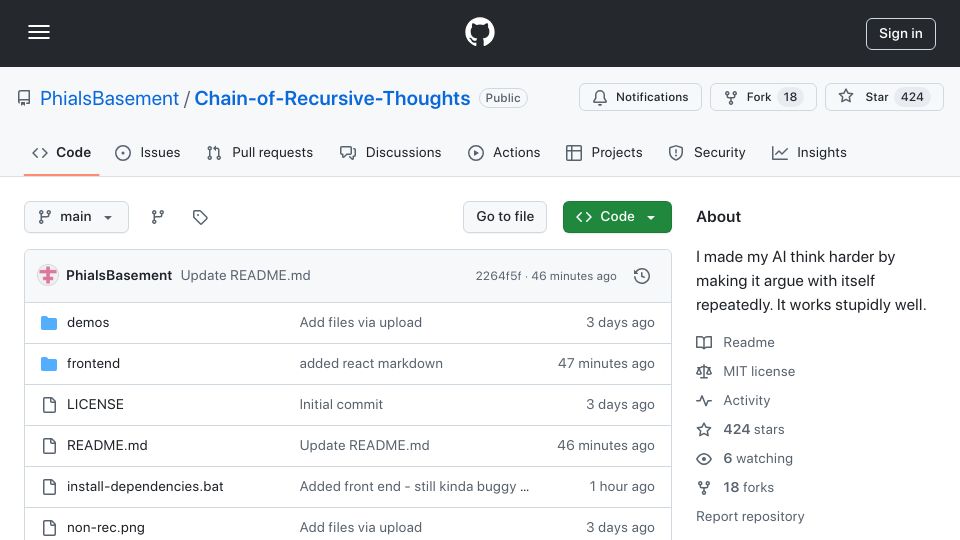
517 points by miles | 226 comments
GitHub repository for Chain-of-Recursive-Thoughts, an MIT-licensed tool that makes an AI model improve answers by repeatedly arguing with itself.
369 points by meetpateltech | 246 comments
Anthropic research post on whether reasoning models' Chain-of-Thought faithfully reflects their actual reasoning, linking to the accompanying paper.
334 points by jasonthorsness | 133 comments
A blog demo page where clicking a button has DeepSeek R1 analyze and comment on the visitor's user agent, browser capabilities, and IP location headers.
334 points by TaurenHunter | 138 comments
An AI Papers Academy article and video explaining Meta AI's Coconut paper on LLM reasoning via chain of continuous thought in latent space.
352 points by benocodes | 229 comments
arXiv paper examining tasks where chain-of-thought prompting reduces LLM performance, drawing on cases where deliberation hurts human performance.
394 points by jsheard | 214 comments
A tweet reporting that OpenAI warned a user it would revoke o1 model access after they asked the model about its hidden chain of thought.
641 points by loganfrederick | 566 comments
Simon Willison's blog post with notes on OpenAI's o1-preview and o1-mini models, covering chain-of-thought training, API details, hidden reasoning tokens and examples.
1573 points by fofoz | 1186 comments
OpenAI research post introducing o1, a large language model trained with reinforcement learning to reason using a long internal chain of thought before answering.
504 points by mpweiher | 244 comments
Martin Fowler's article recounting how Xu Hao uses chain-of-thought and general knowledge prompting with ChatGPT to produce self-tested code.