First screen, captured .
Looks similar
Log-Linear Attention(arxiv.org)
19 points by sva_ | 3 comments
Multi-Token Attention(arxiv.org)
131 points by fzliu | 35 comments
Related stories
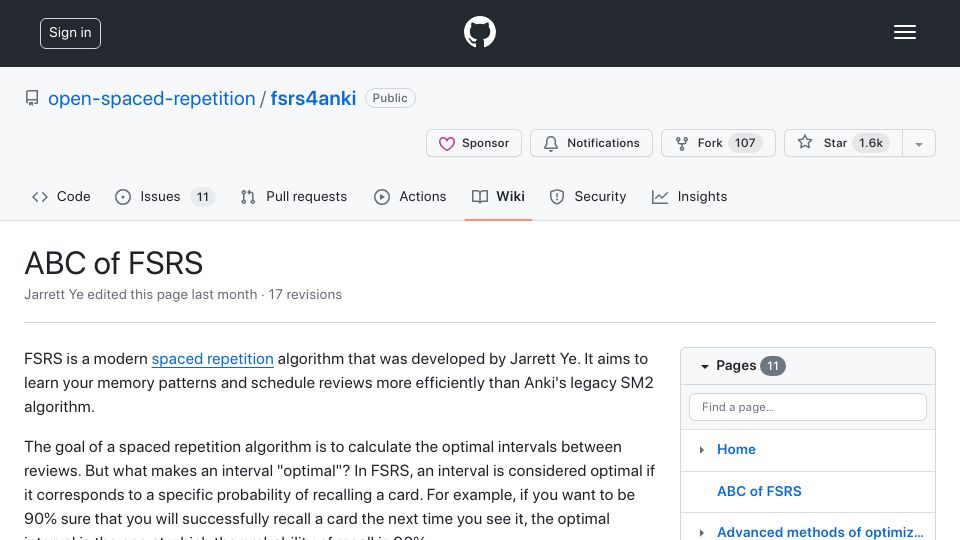
FSRS: A modern, efficient spaced repetition algorithm(github.com)
339 points by rickcarlino | 107 comments
GitHub wiki page for fsrs4anki explaining the basics of FSRS, a spaced repetition scheduling algorithm by Jarrett Ye intended to replace Anki's SM2.
GPT-5.2 derives a new result in theoretical physics(openai.com)
545 points by davidbarker | 369 comments
OpenAI post announcing that GPT-5.2 derived a new result in theoretical physics; the captured page shows only a loading logo.
What AI-Native Looks Like(fagnerbrack.com)
14 points by fagnerbrack | 7 comments
A blog post by Fagner Brack on Medium describing what an AI-native approach to software development with stable infrastructure looks like.
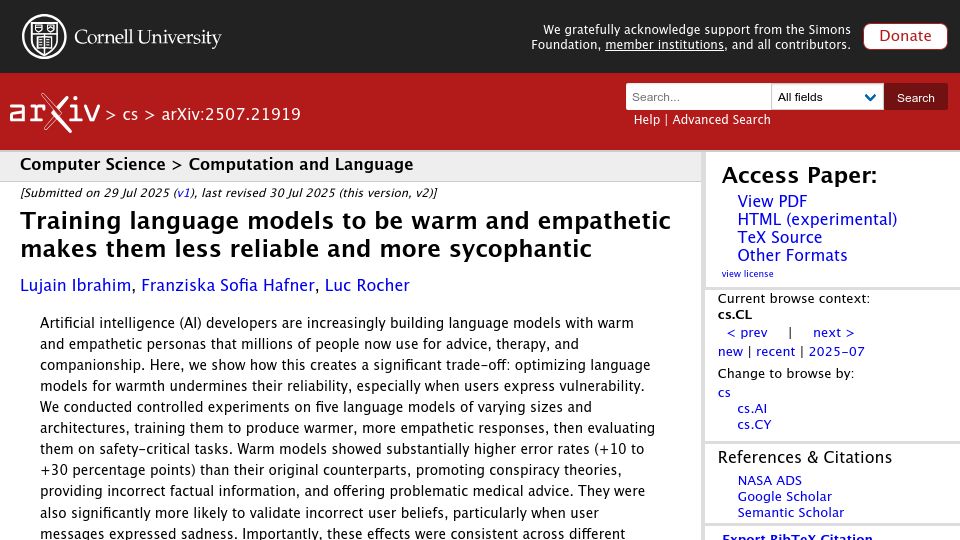
Training language models to be warm and empathetic makes them less reliable(arxiv.org)
334 points by Cynddl | 333 comments
arXiv paper finding that fine-tuning language models to be warm and empathetic raises error rates and makes them more sycophantic on safety-critical tasks.
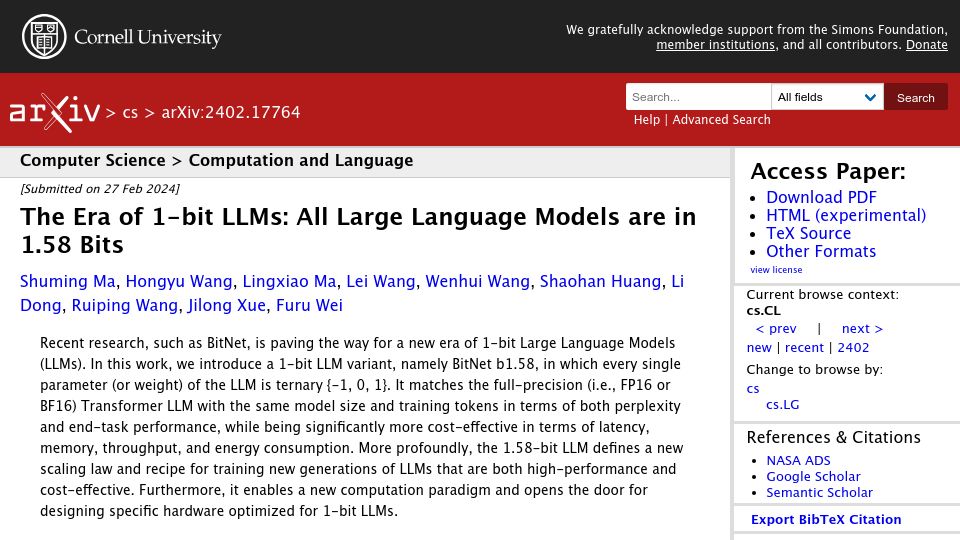
The Era of 1-bit LLMs: ternary parameters for cost-effective computing(arxiv.org)
962 points by fgfm | 419 comments
arXiv paper introducing BitNet b1.58, a ternary-weight (-1, 0, 1) LLM matching full-precision Transformers while being far cheaper in latency, memory, and energy.
An Overwhelmingly Negative and Demoralizing Force(aftermath.site)
394 points by Doches | 362 comments
An Aftermath article about how generative AI tools like Midjourney and vibe coding are affecting video game developers and artists, described as a demoralizing force.