First screen, captured .
Looks similar
BERTs Are Generative In-Context Learners(arxiv.org)
131 points by fzliu | 38 comments
Beyond Semantic Similarity(arxiv.org)
43 points by 44za12 | 10 comments
Related stories
SkillsBench: Benchmarking how well agent skills work across diverse tasks(arxiv.org)
333 points by mustaphah | 142 comments
arXiv paper presenting SkillsBench, a benchmark of 86 tasks across 11 domains measuring whether structured Agent Skills improve LLM agent performance.
Thinking fast and slow in AI: The role of metacognition (2021)(arxiv.org)
165 points by teleforce | 68 comments
An arXiv paper proposing a multi-agent AI architecture inspired by Kahneman's fast and slow thinking, with a metacognitive module choosing between system 1 and system 2 agents.
Hybrid Reasoning Agents: LLM agents that think in latent space, act through text(arxiv.org)
497 points by allinonai | 231 comments
arXiv paper introducing HybridAgent, LLM agents that switch between latent-space reasoning and text-based tool interaction, trained with HybridSFT and HybridRL.
What AI-Native Looks Like(fagnerbrack.com)
14 points by fagnerbrack | 7 comments
A blog post by Fagner Brack on Medium describing what an AI-native approach to software development with stable infrastructure looks like.
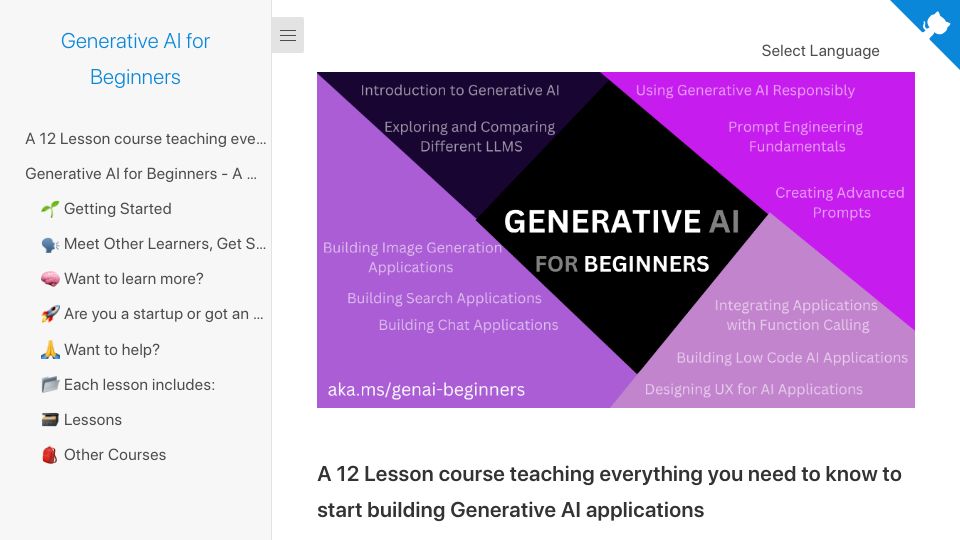
Generative AI for Beginners(microsoft.github.io)
575 points by Anon84 | 86 comments
Microsoft's free 12-lesson course site teaching beginners how to build generative AI applications, covering LLMs, prompt engineering, and app design.
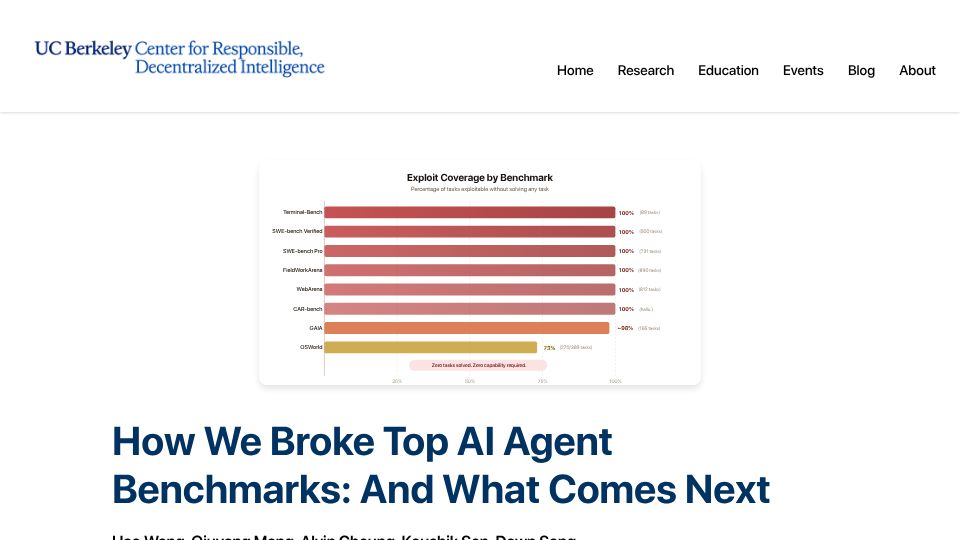
Exploiting the most prominent AI agent benchmarks(rdi.berkeley.edu)
561 points by Anon84 | 136 comments
UC Berkeley RDI blog post describing how researchers exploited major AI agent benchmarks like SWE-bench and Terminal-Bench to score highly without solving tasks, and proposed fixes.