First screen, captured .
Looks similar
Related stories
GPT-5.5 hallucinates 3x more than MIT-licensed GLM-5.2(arrowtsx.dev)
474 points by oshrimpton | 235 comments
Blog post arguing that bigger AI models are not better, comparing benchmark and hallucination rates of GLM-5.2, GPT-5.5, Opus 4.8, DeepSeek V4 and others.
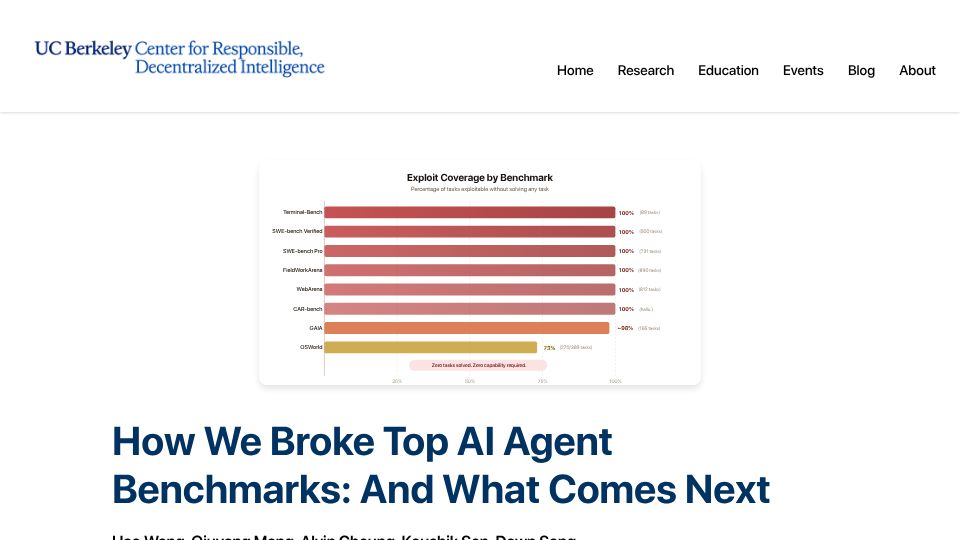
Exploiting the most prominent AI agent benchmarks(rdi.berkeley.edu)
561 points by Anon84 | 136 comments
UC Berkeley RDI blog post describing how researchers exploited major AI agent benchmarks like SWE-bench and Terminal-Bench to score highly without solving tasks, and proposed fixes.
No one wants to talk to your chatbot(lucas-mcgregor.medium.com)
354 points by cratermoon | 170 comments
A Medium essay by Lucas McGregor arguing that users don't want to interact with company chatbots.
AI is killing B2B SaaS(nmn.gl)
462 points by namanyayg | 688 comments
Blog post by Namanyay Goel arguing that agentic AI is threatening the B2B SaaS business model, based on conversations with SF founders.
CEOs who think AI replaces their employees are just bad CEOs(techdirt.com)
760 points by speckx | 277 comments
Techdirt opinion piece by Mike Masnick arguing that CEOs who mandate AI use or see it as replacing employees are bad leaders.
The Eternal Sloptember(geohot.github.io)
347 points by razin | 280 comments
A blog post by George Hotz arguing that adopting AI coding agents in software development is a costly mistake because their output is subtly broken.