First screen, captured .
Looks similar
Meta Segment Anything Model Audio(ai.meta.com)
196 points by megaman821 | 28 comments
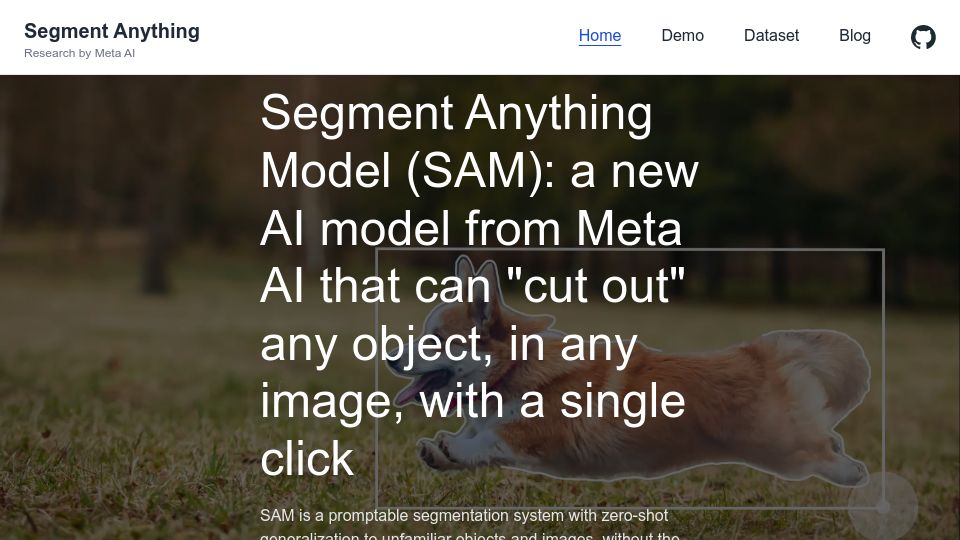
Segment Anything Model (SAM) can "cut out" any object in an image(segment-anything.com)
651 points by crakenzak | 130 comments
Project homepage for Meta AI's Segment Anything Model (SAM), a promptable image segmentation system that can cut out any object with a single click.
Meta Segment Anything Model 3(ai.meta.com)
172 points by alcinos | 38 comments
Related stories
Segment Anything Model (SAM) can "cut out" any object in an image(segment-anything.com)
651 points by crakenzak | 130 comments
Project homepage for Meta AI's Segment Anything Model (SAM), a promptable image segmentation system that can cut out any object with a single click.
SAM 2: Segment Anything in Images and Videos(github.com)
674 points by xenova | 122 comments
GitHub repository from Meta's facebookresearch with inference code, model checkpoints, and example notebooks for Segment Anything Model 2 (SAM 2).
Meta Movie Gen(ai.meta.com)
1028 points by brianjking | 938 comments
Meta's research page introducing Movie Gen, a set of media foundation AI models for generating video and audio from text.
Llama 3.2: Revolutionizing edge AI and vision with open, customizable models(ai.meta.com)
861 points by nmwnmw | 298 comments
Meta AI blog post announcing Llama 3.2, including vision-capable models and lightweight models for edge and mobile devices.
GPT-5.5 hallucinates 3x more than MIT-licensed GLM-5.2(arrowtsx.dev)
474 points by oshrimpton | 235 comments
Blog post arguing that bigger AI models are not better, comparing benchmark and hallucination rates of GLM-5.2, GPT-5.5, Opus 4.8, DeepSeek V4 and others.
EmbeddingGemma 2: An open, lightweight multimodal embedding model(blog.google)
395 points by ilreb | 42 comments
Google blog post announcing EmbeddingGemma 2, an open lightweight on-device model that embeds text, images, audio, and video into a unified space.