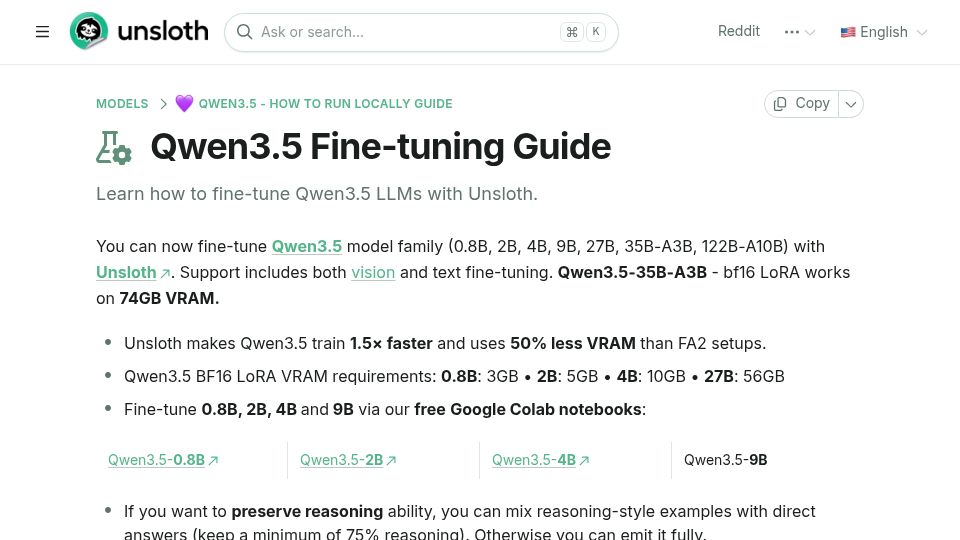
Qwen3.5 Fine-Tuning Guide(unsloth.ai)
384 points by bilsbie | 93 comments
Unsloth documentation guide explaining how to fine-tune Qwen3.5 LLMs (0.8B to 122B) with LoRA, including VRAM requirements and free Colab notebooks.
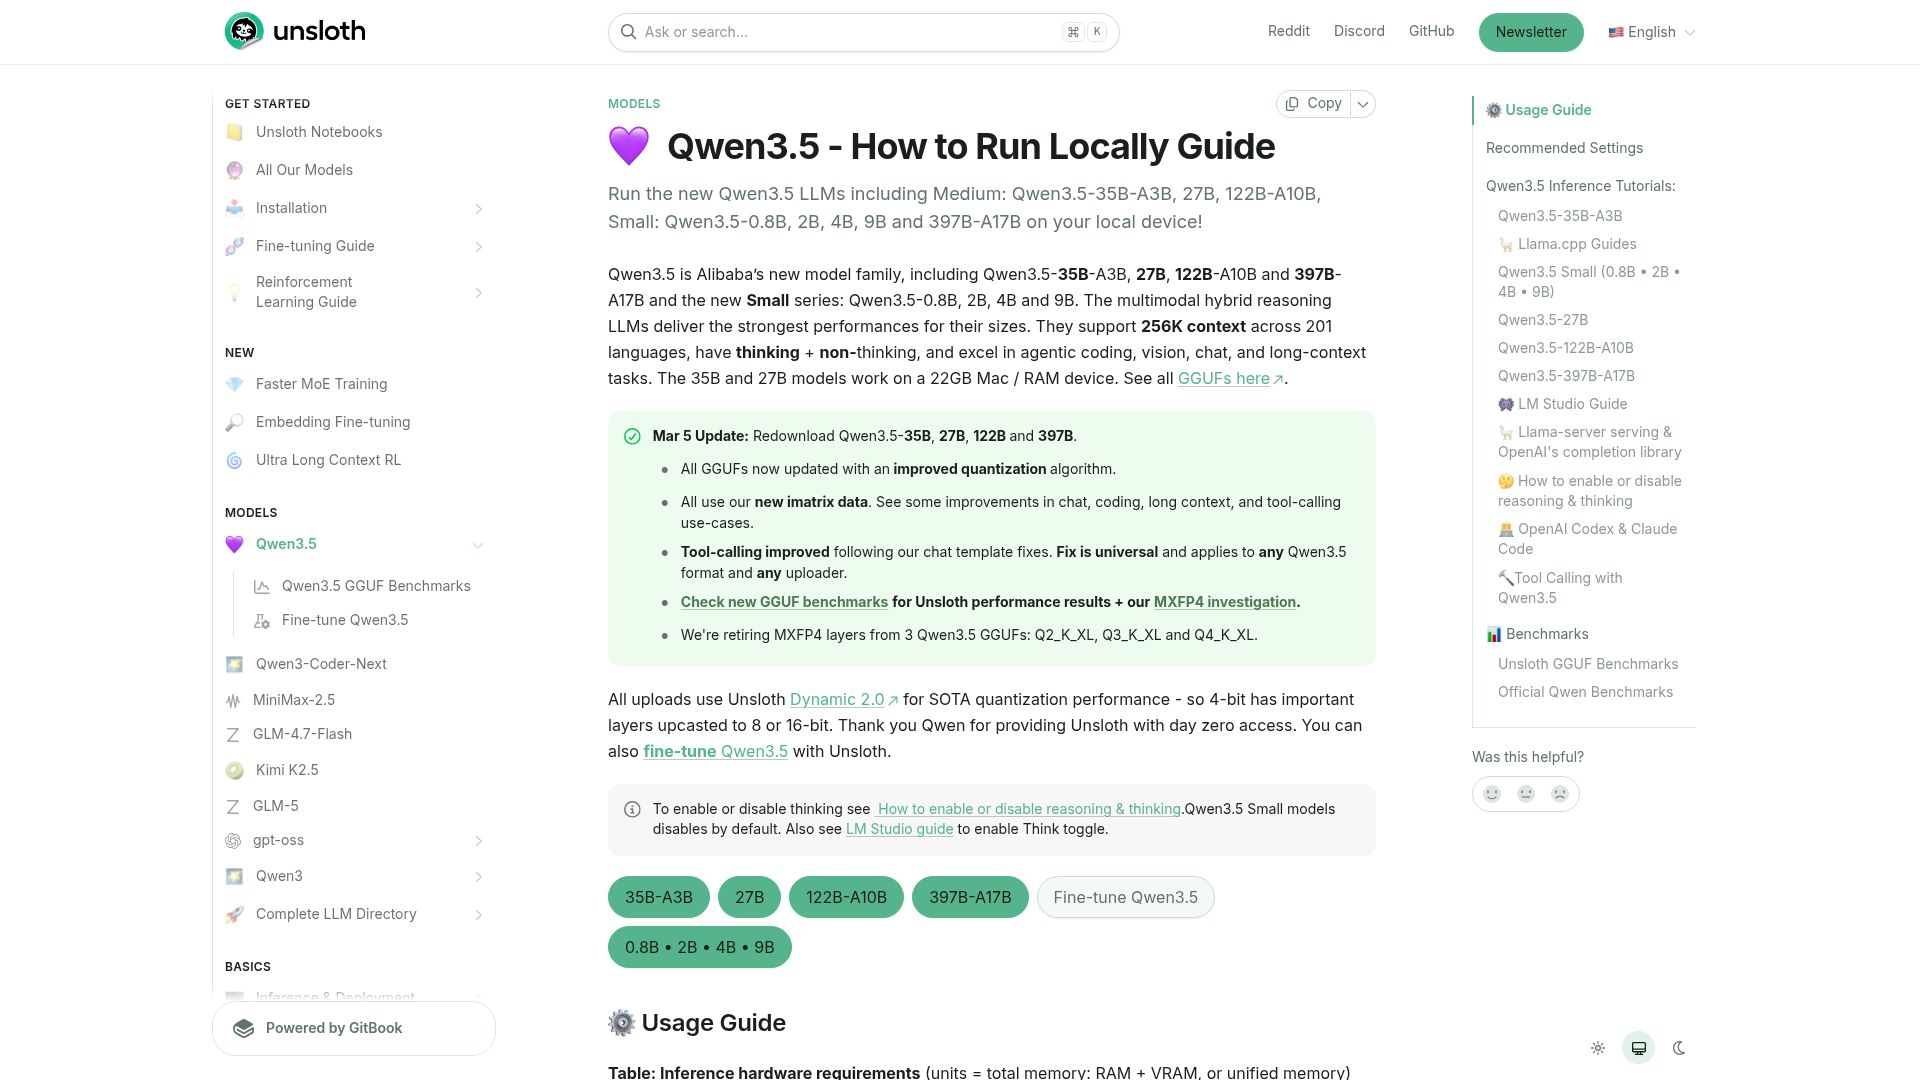
First screen, captured .
384 points by bilsbie | 93 comments
Unsloth documentation guide explaining how to fine-tune Qwen3.5 LLMs (0.8B to 122B) with LoRA, including VRAM requirements and free Colab notebooks.
559 points by TechTechTech | 266 comments
Unsloth documentation guide explaining how to run Z.ai's GLM-5.2 open model locally using Unsloth Dynamic quantized GGUFs.
364 points by brainless | 67 comments
Announcement page for Unsloth Studio (Beta), an open-source no-code web UI for training, running, and exporting open AI models locally.
309 points by jonesy827 | 110 comments
222 points by tosh | 61 comments
142 points by vinhnx | 36 comments
353 points by tosh | 115 comments
A blog post by Nikolas Göbel discussing how DuckDB can act as a database without storing data itself, querying external data sources directly.
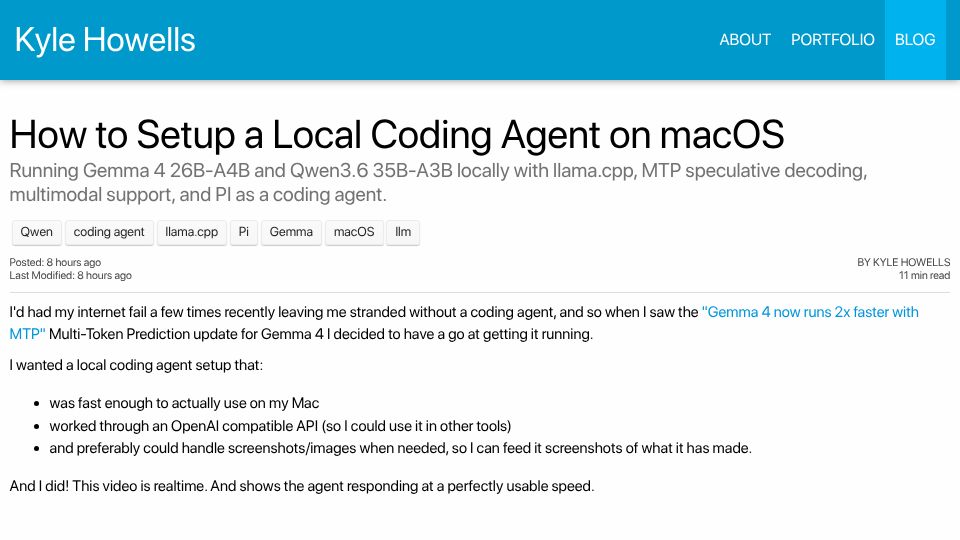
464 points by kkm | 114 comments
A blog tutorial on running Gemma 4 and Qwen3.6 locally on macOS with llama.cpp, MTP speculative decoding, and multimodal support as a coding agent.
331 points by rushingcreek | 135 comments
Phind blog post announcing its Phind-405B model and faster, higher-quality AI search answers; the capture shows a Cloudflare verification page.
211 points by ThibWeb | 165 comments
Wagtail blog post by Thibaud Colas recounting a month of using only the open GLM 5.3 Flash model for coding, consuming 2B tokens.
116 points by flxflx | 50 comments
Privatemode AI blog post describing how to prompt GLM-5.3-Flash so its first output token gives a decision in a single forward pass, benchmarked against Jev and Laya.
519 points by tosh | 201 comments
Qwen team blog post announcing Qwen3-Next, a model architecture aimed at improving LLM training and inference efficiency.