First screen, captured .
Looks similar
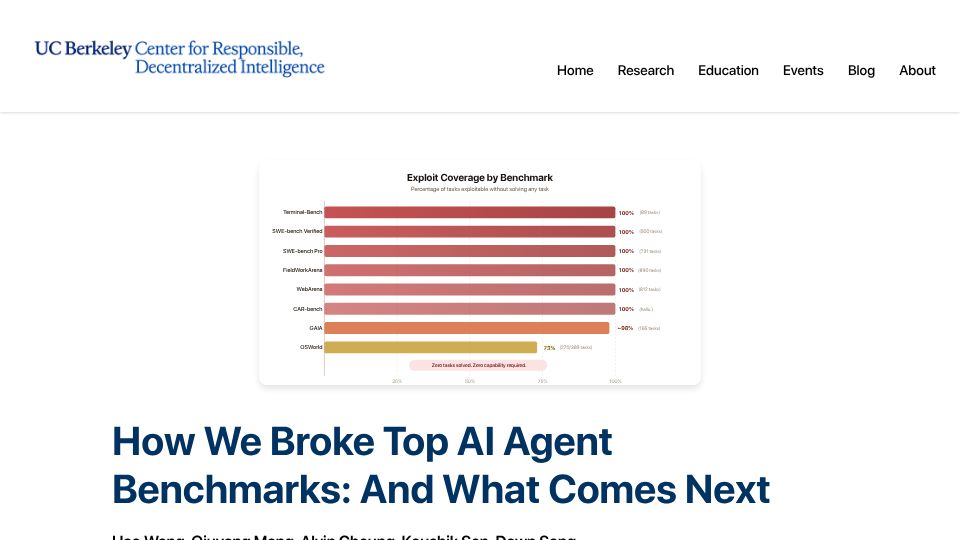
Exploiting the most prominent AI agent benchmarks(rdi.berkeley.edu)
561 points by Anon84 | 136 comments
UC Berkeley RDI blog post describing how researchers exploited major AI agent benchmarks like SWE-bench and Terminal-Bench to score highly without solving tasks, and proposed fixes.
When Do We Become the Person We Ought to Be?(graphsaboutreligion.com)
18 points by toomuchtodo | 61 comments
A Graphs about Religion Substack post analyzing a 557-person survey on how Americans rate their own moral character by age and religious practice.
Most HR data is bad data (2015)(hbr.org)
29 points by sherilm | 30 comments