Learning to Reason with LLMs(openai.com)
1573 points by fofoz | 1186 comments
OpenAI research post introducing o1, a large language model trained with reinforcement learning to reason using a long internal chain of thought before answering.
First screen, captured .
1573 points by fofoz | 1186 comments
OpenAI research post introducing o1, a large language model trained with reinforcement learning to reason using a long internal chain of thought before answering.
343 points by shchegrikovich | 122 comments
Substack post arguing that having LLMs generate Prolog code can improve their reasoning, given the limits of autoregressive transformer generation.
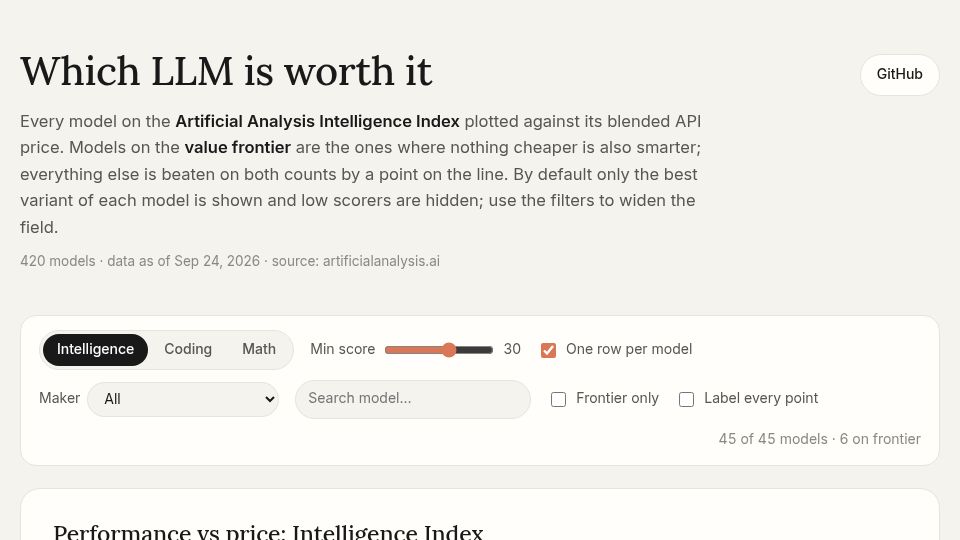
127 points by terryds | 80 comments
Interactive chart plotting LLMs on the Artificial Analysis Intelligence Index against blended API price, highlighting the value frontier with filters.