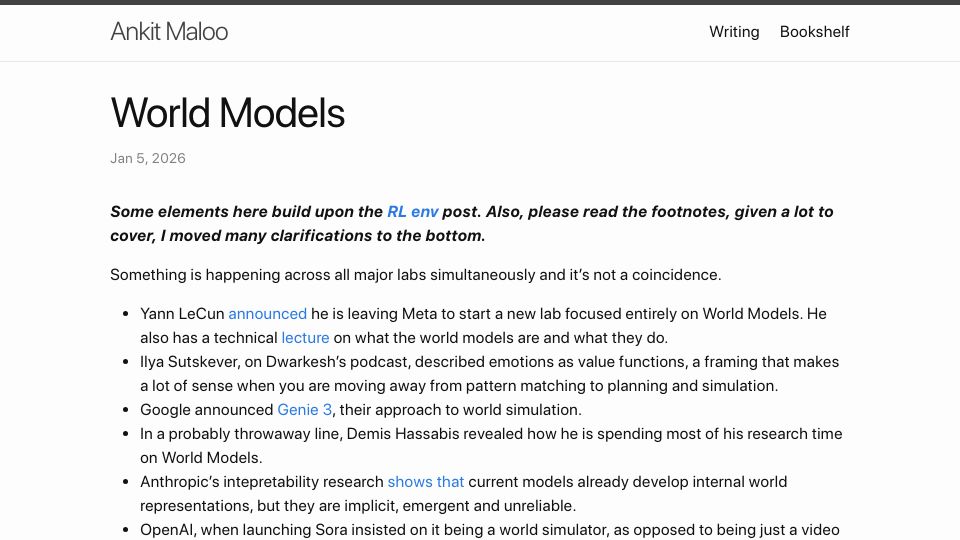
World Models(ankitmaloo.com)
18 points by ankit219 | 2 comments
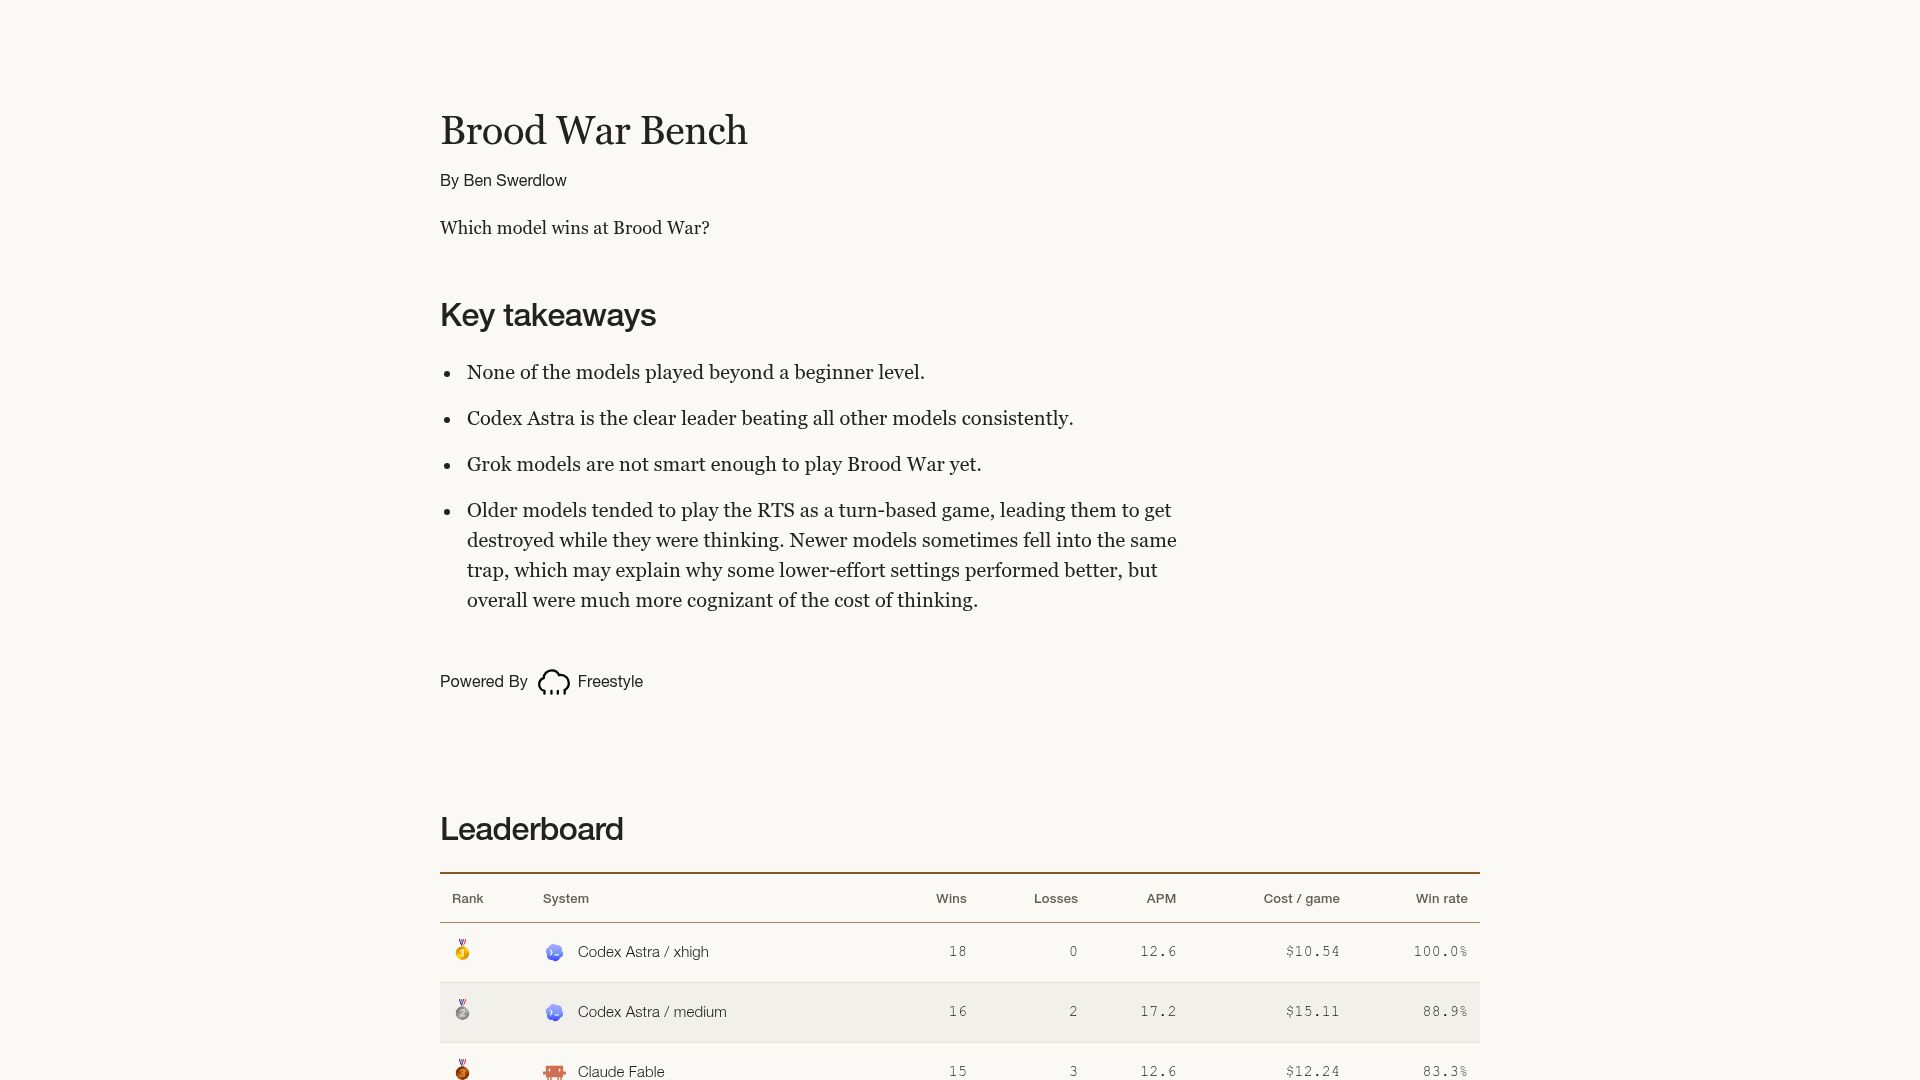
First screen, captured .
18 points by ankit219 | 2 comments
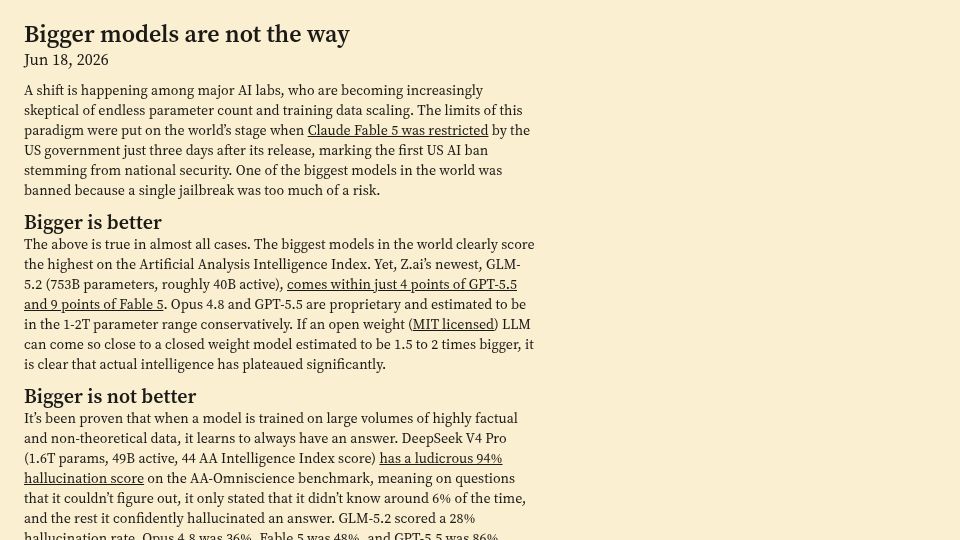
474 points by oshrimpton | 235 comments
Blog post arguing that bigger AI models are not better, comparing benchmark and hallucination rates of GLM-5.2, GPT-5.5, Opus 4.8, DeepSeek V4 and others.
186 points by type0 | 154 comments
116 points by ludovicianul | 15 comments
208 points by pabs3 | 186 comments
474 points by paulpauper | 375 comments
LessWrong linkpost essay arguing recent AI model improvements feel overstated, based on experience building an AI codebase security-scanning startup.
376 points by thunderbong | 148 comments
Blog post recounting how the author spent weeks hand-optimizing assembly for a Java platform, only to find the gains came from benchmarking on unrealistic random data.
521 points by mellosouls | 199 comments
SSRN page for a Chicago Booth working paper examining whether large language models can perform financial statement analysis like professional analysts.
334 points by Cynddl | 333 comments
arXiv paper finding that fine-tuning language models to be warm and empathetic raises error rates and makes them more sycophantic on safety-critical tasks.
426 points by minki_the_avali | 184 comments
A forum post on LenOwO describing how the original DOOM engine crashed after running for 2.5 years on real hardware due to an ever-incrementing demo variable.
426 points by jaykru | 552 comments
Personal blog essay by Jay Kruer arguing LLMs remain overhyped despite headline results like Navier-Stokes, citing poor generalization, reward hacking, and specification costs.