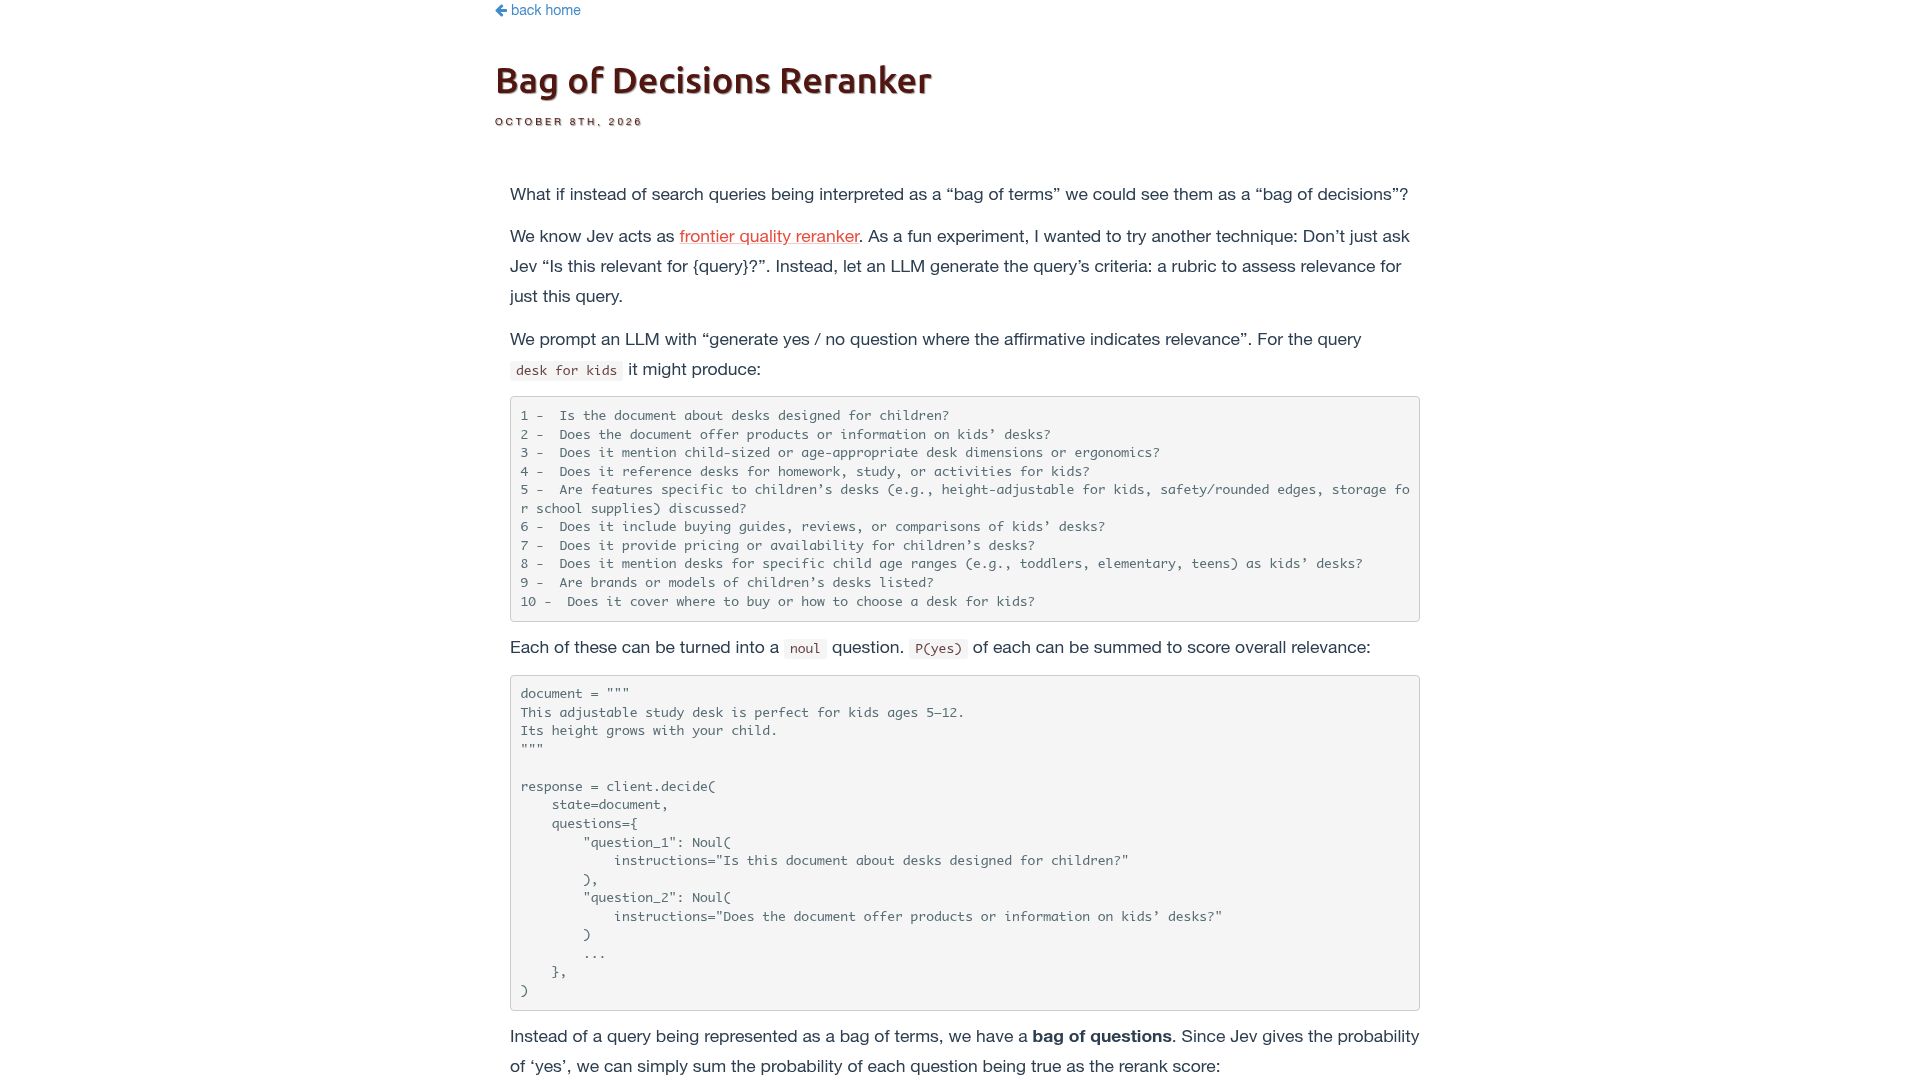
First screen, captured .
Looks similar
Optimizers need a rethink(typesanitizer.com)
132 points by ingve | 139 comments
A road to Lisp: Why Lisp(scotto.me)
275 points by silcoon | 264 comments
Related stories
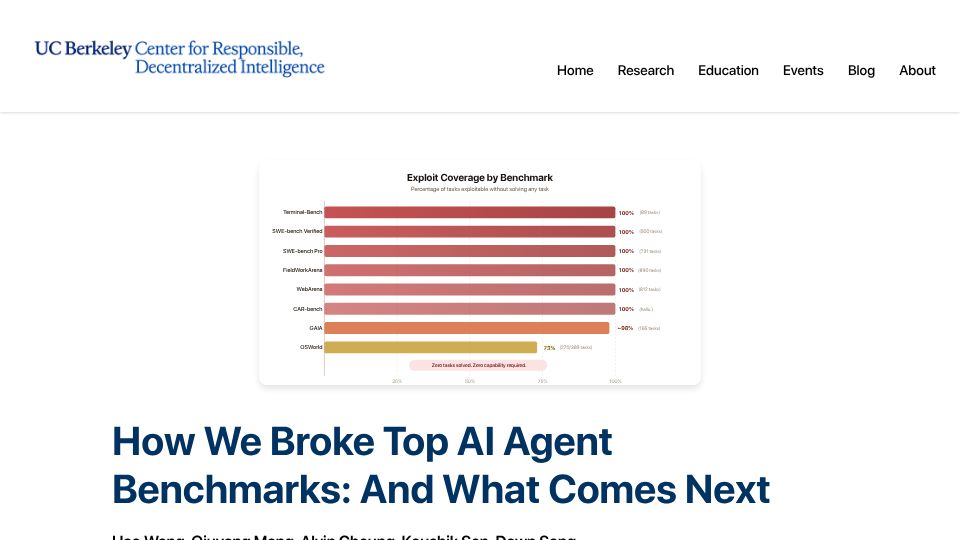
Exploiting the most prominent AI agent benchmarks(rdi.berkeley.edu)
561 points by Anon84 | 136 comments
UC Berkeley RDI blog post describing how researchers exploited major AI agent benchmarks like SWE-bench and Terminal-Bench to score highly without solving tasks, and proposed fixes.
Pen and Paper Exercises in Machine Learning (2022)(arxiv.org)
389 points by ibobev | 53 comments
arXiv paper by Michael U. Gutmann collecting pen-and-paper exercises on machine learning topics like graphical models, HMM inference, sampling, and variational inference.
Decision models like Jev don't beat LLM-as-a-judge or traditional classifiers(developers.redhat.com)
140 points by tomncooper | 50 comments
Red Hat Developer article benchmarking AI decision models like TypeSafe AI's Jev against LLM-as-a-judge and traditional classifier guardrails.
Publish fake stats, get cited in LLMs(peec.ai)
315 points by robtherobber | 204 comments
Peec AI blog post by a GEO researcher describing how publishing statistics led to the author's data being widely cited across the web and by LLMs.
Jeeves. Reasoning improves Jev-like decision models(github.com)
232 points by nicowaltz | 89 comments
GitHub repository from PostHog for Jeeves, a project showing that reasoning improves Jev-like decision models.
Recent AI models struggled to match a human algorithmic innovation(epoch.ai)
85 points by merksittich | 64 comments
Epoch AI report by David Owen presenting InnovationEval, finding early evidence that AI models cannot yet automate AI R&D or match human algorithmic innovation.