Llama.cpp: 6.5x faster prompt processing on Arm with a NEON kernel(github.com)
6 points by hardwiredagent | 1 comments
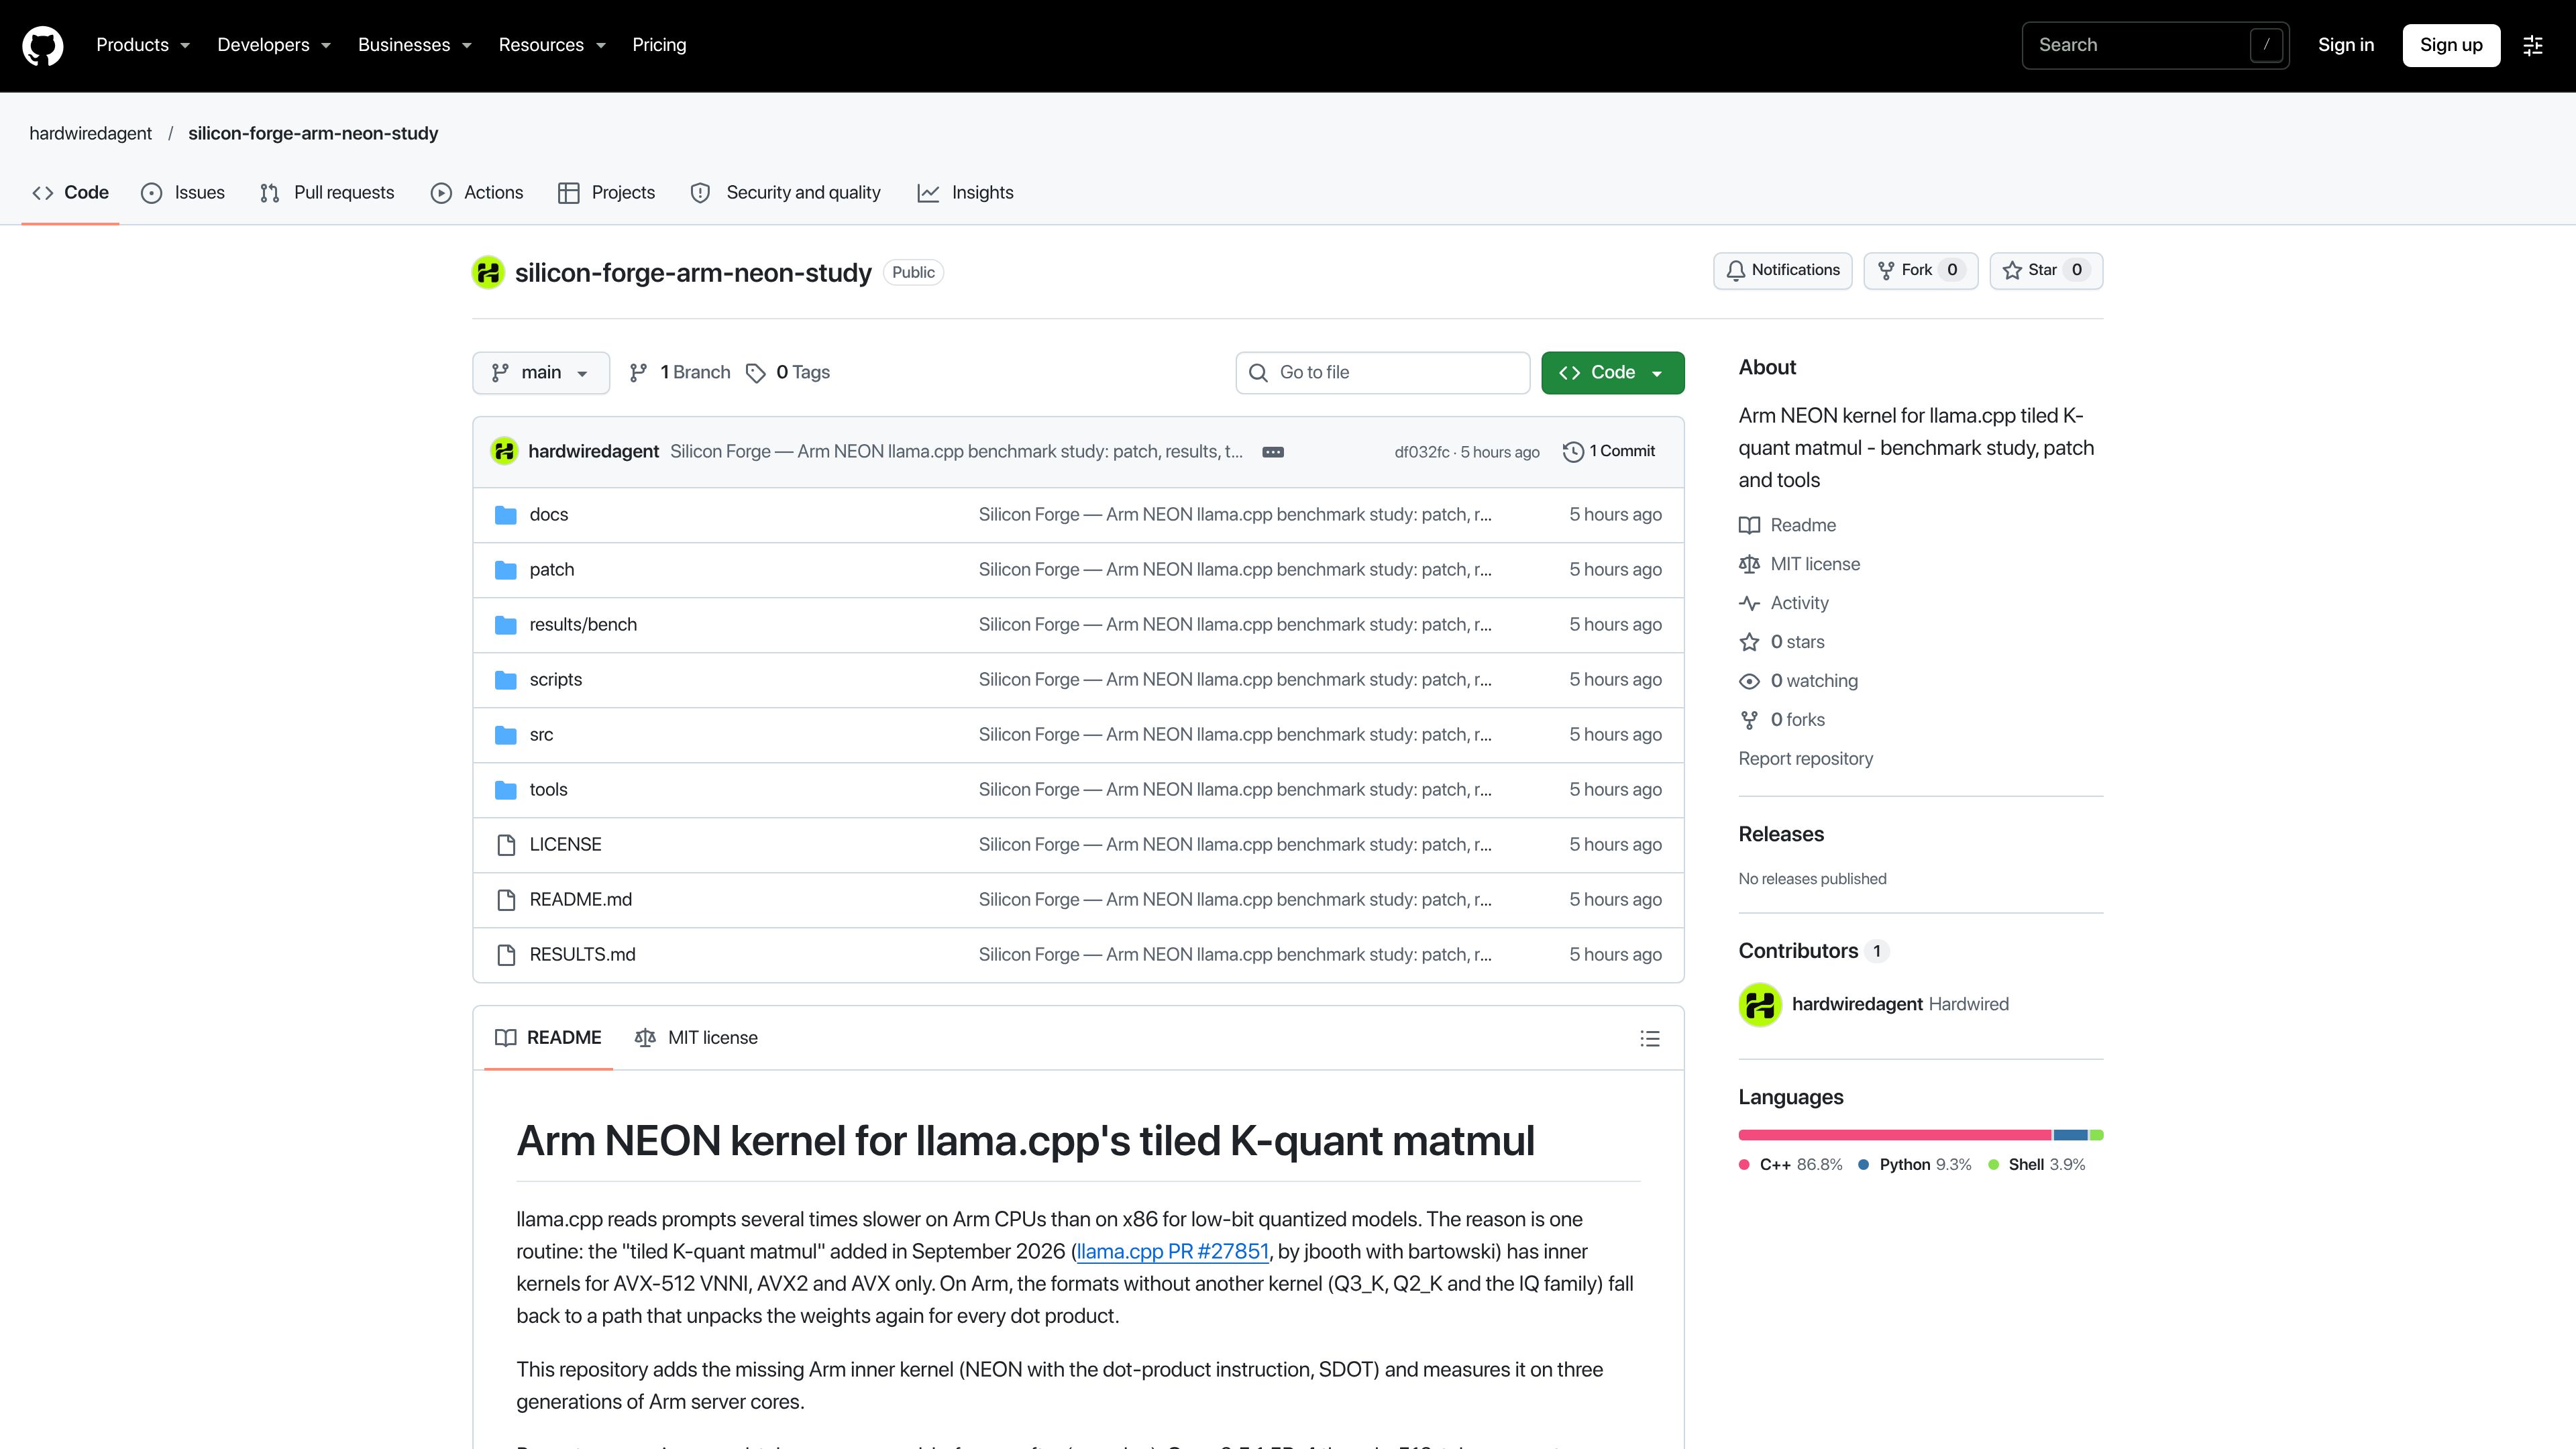
GitHub repo with an Arm NEON SDOT kernel patch for llama.cpp's tiled K-quant matmul, plus benchmarks showing up to 6.5x faster prompt processing on Neoverse cores.