Using Claude to reduce the attack surface of code(anthropic.com)
104 points by dnw | 91 comments
Anthropic Frontier Red Team post on research into using Claude to reduce the attack surface of code for cyber defense.
23 stories tagged llm-security, newest first.
104 points by dnw | 91 comments
Anthropic Frontier Red Team post on research into using Claude to reduce the attack surface of code for cyber defense.
15 points by rafaeldavidtin | 1 comments
Blog post from Stealthium on detecting tampering of AI model weights in GPU memory, such as ROME model-editing attacks.
6 points by northbridgedev | 2 comments
GitHub repo benchmarking open-source prompt-injection detectors like regex and Meta's Prompt Guard 2 against 629 AgentDojo attacks buried in tool output.
251 points by Aeroi | 134 comments
Blog post by Mouse describing how asking Meta's Muse AI for its filesystem resulted in a 6.8 GB export of its sandbox runtime.
335 points by Recursing | 112 comments
Blog post on Embrace The Red showing how a website summary request can hijack Claude Code Opus 5 in Auto Mode to achieve code execution via prompt injection.
665 points by quantumgarbage | 295 comments
Project page for a research paper on extracting hidden reasoning traces from proprietary LLM APIs, by authors from MATS, ELLIS, Max Planck and Tübingen.
352 points by Canopy9560 | 271 comments
Blog post, part 3 of a series, describing how prompt-injection payloads in documents can self-propagate as AI worms through Microsoft Copilot for Word.
487 points by macleginn | 230 comments
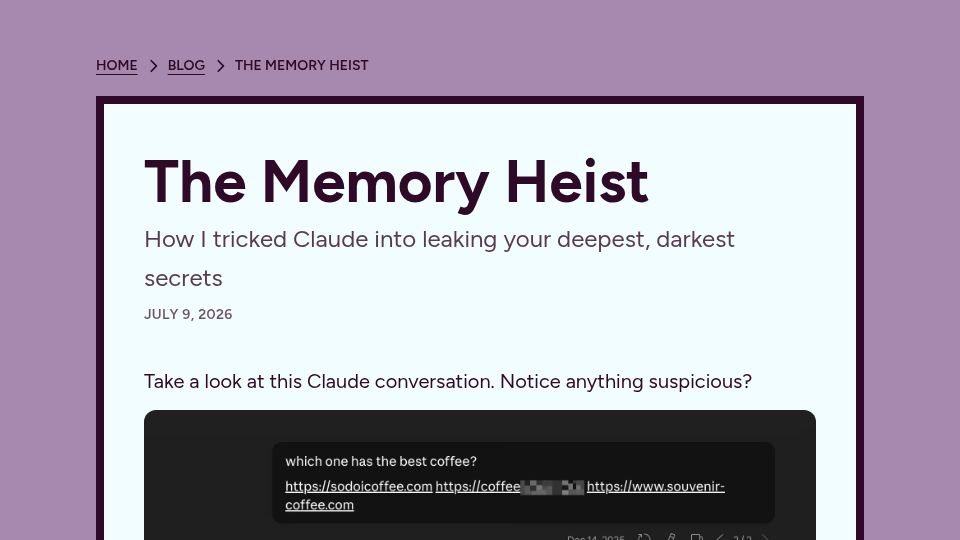
Blog post describing how the author used a prompt-injection attack to trick Anthropic's Claude into leaking users' stored memory data.
343 points by cuchoi | 156 comments
Blog post recounting how over 2,000 people sent 6,000+ emails trying to get the author's OpenClaw AI assistant to leak a secrets file, which never leaked.
531 points by dbreunig | 197 comments
Blog post by Drew Breunig arguing that with LLMs like Anthropic's Mythos, cybersecurity becomes a contest of spending more tokens than attackers, akin to proof of work.
1206 points by dominicq | 321 comments
AISLE blog post arguing that small open-weights models reproduced much of Anthropic Mythos's showcase vulnerability analysis, framing AI cybersecurity capability as jagged.
346 points by hentrep | 177 comments
HackMyClaw is a challenge site inviting users to extract secrets from Fiu, an OpenClaw email-reading AI assistant, via indirect prompt injection over email.
827 points by takira | 366 comments
PromptArmor threat intelligence report showing Claude Cowork is vulnerable to file exfiltration via indirect prompt injection due to code execution isolation flaws.
574 points by helloplanets | 190 comments
An X/Twitter post claiming Perplexity's Comet AI browser can be prompt-injected by any website to take actions like draining a user's bank account.
406 points by vismit2000 | 109 comments
Simon Willison's annotated presentation of his Bay Area AI Security Meetup talk on prompt injection, the lethal trifecta, and securing MCP-based systems.
341 points by uponasmile | 136 comments
Eye Security research blog post describing how the team gained root access inside Microsoft Copilot's code execution sandbox.
798 points by rexpository | 433 comments
A General Analysis blog post describing how Supabase's MCP server can be exploited via prompt injection to leak an entire private SQL database.
668 points by skilldeliver | 165 comments
Medium article by Elena Cross arguing that the Model Context Protocol (MCP) for AI agents has significant security weaknesses.
627 points by topsycatt | 127 comments
Lupin & Holmes blog post describing how researchers probed Google Gemini's Python code-execution sandbox and extracted parts of its internal source code.
578 points by tprow50 | 170 comments
PromptArmor blog post describing an indirect prompt injection vulnerability in Slack AI that lets attackers exfiltrate data from private channels.
322 points by amrrs | 296 comments
Meta AI blog post announcing Purple Llama, an umbrella project of open trust and safety tools and evaluations for generative AI.
396 points by goranmoomin | 143 comments
Blog post describing how indirect prompt injection via Google Bard Extensions can be used to exfiltrate user data from Drive, Docs and Gmail.
463 points by sebg | 164 comments
Simon Willison's blog post with video, slides, and transcript of his webinar talk explaining prompt injection and why proposed defenses fall short.