The August 17 outage(github.blog)
611 points by 0xedb | 707 comments
GitHub blog post giving an update on the August 17 outage and the steps GitHub is taking to improve reliability.
13 stories tagged reliability, newest first.
611 points by 0xedb | 707 comments
GitHub blog post giving an update on the August 17 outage and the steps GitHub is taking to improve reliability.
464 points by speckx | 306 comments
A blog post arguing that 98% success rates are inadequate for basic expectations, such as websites relying on new browser features that fail for millions of users.
394 points by salkahfi | 236 comments
A GitHub blog post explaining what the company has done and is still doing to improve the availability and reliability of its service.
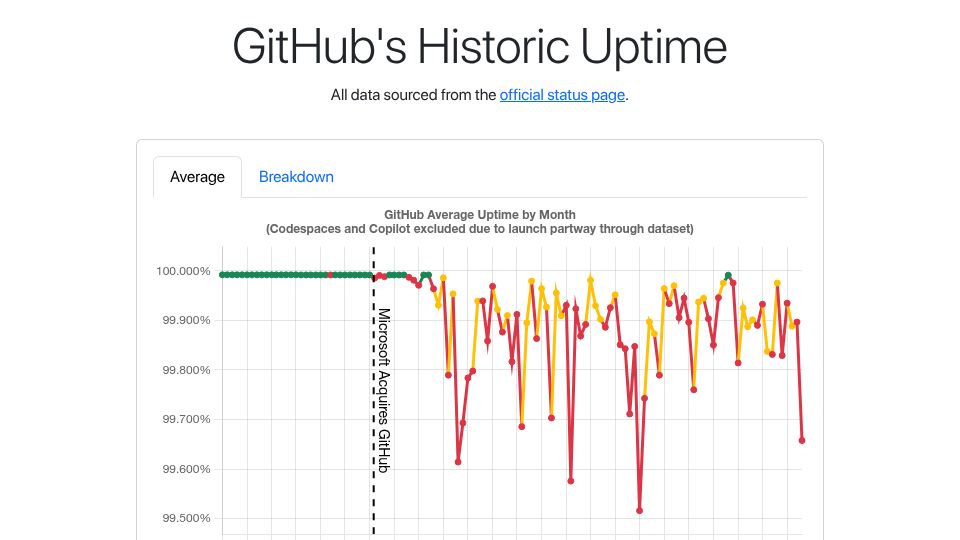
446 points by todsacerdoti | 109 comments
A chart of GitHub's average monthly uptime from its official status page data, marking the point where Microsoft acquired GitHub.
1373 points by eastdakota | 807 comments
Cloudflare blog post by Matthew Prince giving the post-mortem of the company's global network outage on November 18, 2025.
393 points by serjester | 230 comments
Blog post by Sergey Filimonov arguing AI agents should prioritize reliability over expanded capability, critiquing flight-booking demos.
592 points by TangerineDream | 185 comments
Backblaze blog post presenting its annual hard drive reliability and failure rate statistics for 2024.
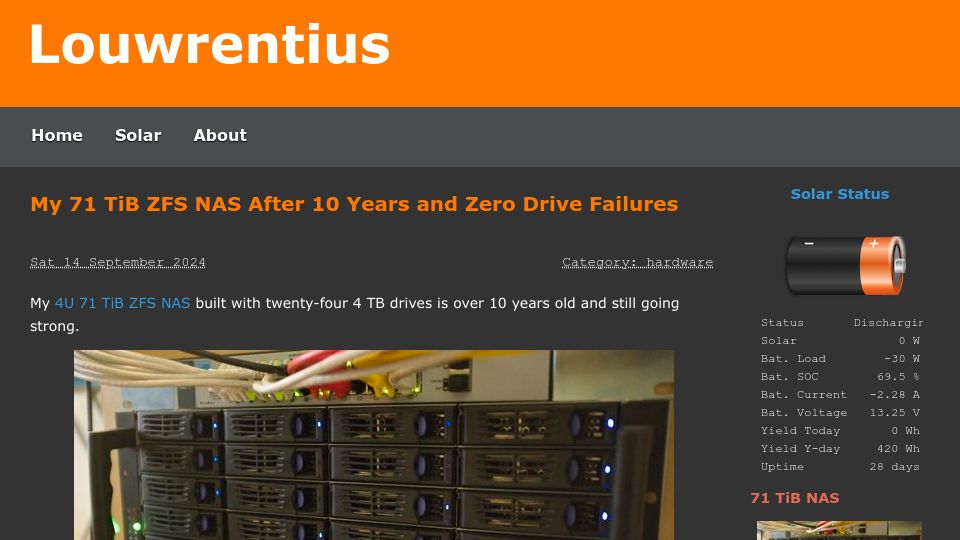
391 points by louwrentius | 271 comments
Blog post reviewing a self-built 71 TiB ZFS NAS with twenty-four 4 TB drives that has run for 10 years without a single drive failure.
426 points by ilikepi | 300 comments
Blog post by Chris Dzombak on keeping a Raspberry Pi running reliably for months or years without intervention, part of his Pi Reliability series.
414 points by eastdakota | 194 comments
Cloudflare blog post by Matthew Prince explaining the November 2023 outage of its control plane and analytics services.
496 points by maheshrjl | 108 comments
A Google SRE article sharing eleven lessons learned from twenty years of practicing site reliability engineering at Google.
348 points by serial_dev | 213 comments
Slack Engineering blog post describing the company's migration of its infrastructure to a cellular architecture to improve resilience against availability-zone failures.
602 points by sbmsr | 289 comments
Blog post by SRE Dan Slimmon arguing teams should optimize and get the most out of their existing system rather than rushing to replace it.