Timestamping a Giant Record of the Web(projecttimestamper.org)
35 points by arthuredelstein | 3 comments
Project Timestamper blog post announcing the timestamping of Common Crawl's 339 billion web page snapshots collected over 18 years.
18 stories tagged web-archiving, newest first.
35 points by arthuredelstein | 3 comments
Project Timestamper blog post announcing the timestamping of Common Crawl's 339 billion web page snapshots collected over 18 years.
15 points by rdmuser | 10 comments
Fog-Bank project page explaining how it captures and archives every frame from FogCam, the oldest running webcam, including its pipeline to YouTube and failure tracking.
503 points by latein | 398 comments
Reclaim The Net article reporting that Spain ordered blocks on Archive.today and its mirrors via a commission complaint process without a court ruling.
658 points by ChrisArchitect | 342 comments
Internet Archive blog post by Mark Graham giving an update on access to the Wayback Machine.
845 points by awnird | 844 comments
A Walrus essay by Vass Bednar arguing that Google Search is declining as AI reshapes the web, and that the internet's collective memory is disappearing.
347 points by ChocMontePy | 78 comments
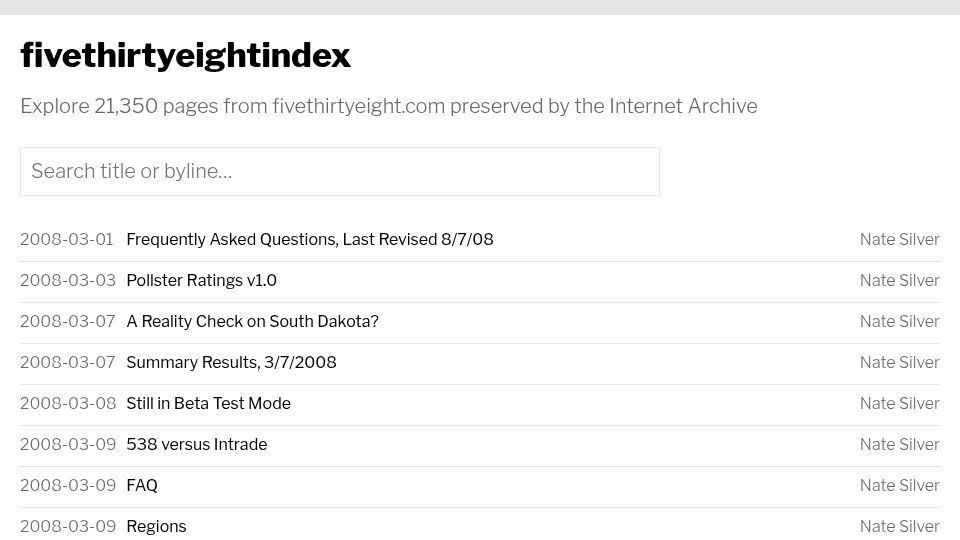
A searchable index of 21,350 FiveThirtyEight.com articles preserved by the Internet Archive, listed by date, title, and byline.
671 points by hggh | 108 comments
Internet Archive blog post announcing Internet Archive Switzerland, a new Swiss organization expanding its mission to preserve knowledge.
475 points by pabs3 | 131 comments
EFF Deeplinks article arguing that publishers blocking the Internet Archive to stop AI scraping won't work and will instead erase the web's historical record.
565 points by nobody9999 | 341 comments
Ars Technica article reporting that Wikipedia has blacklisted Archive.today and is removing about 695,000 archive links after DDoS and snapshot-tampering allegations.
536 points by ninjagoo | 340 comments
Nieman Lab article reporting that news publishers are restricting Internet Archive access over concerns that AI companies scrape archived content.
423 points by dvrp | 98 comments
HackerNoon article by Bruce Li examining the Internet Archive's infrastructure and its efforts to preserve the web, including the Heritrix crawler.
1714 points by immibis | 426 comments
AdGuard DNS blog post investigating suspicious complaints and bailiff demands pressuring it to block Archive.today amid an FBI subpoena of the site's registrar.
907 points by Projectiboga | 456 comments
Heise news article reporting that the FBI obtained a court order forcing domain provider Tucows to hand over user data about the operator of Archive.today.
561 points by pabs3 | 79 comments
Internet Archive blog post celebrating the milestone of 1 trillion web pages archived, with events planned for October.
387 points by pentagrama | 92 comments
ArchiveTeam's tracker dashboard for its distributed project archiving Google's goo.gl short links, with a prompt to run an ArchiveTeam Warrior.
601 points by nikisweeting | 144 comments
Announcement post describing upcoming ArchiveBox features: a plugin ecosystem, P2P sharing between instances, CAPTCHA solving, and auto-logins for self-hosted web archives.
673 points by iscream26 | 138 comments
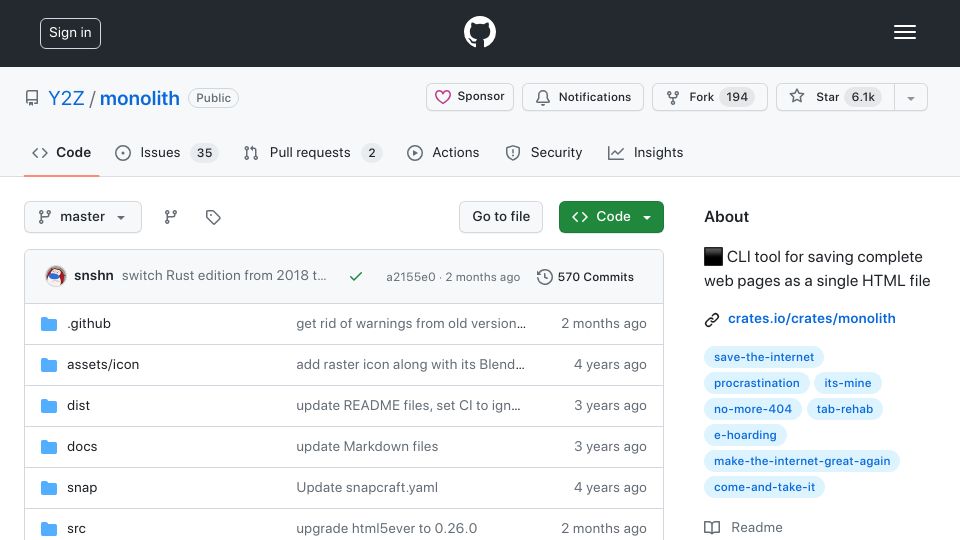
GitHub repository for Monolith, a Rust CLI tool that saves complete web pages, with assets embedded, as a single HTML file.
449 points by susanthenerd | 127 comments
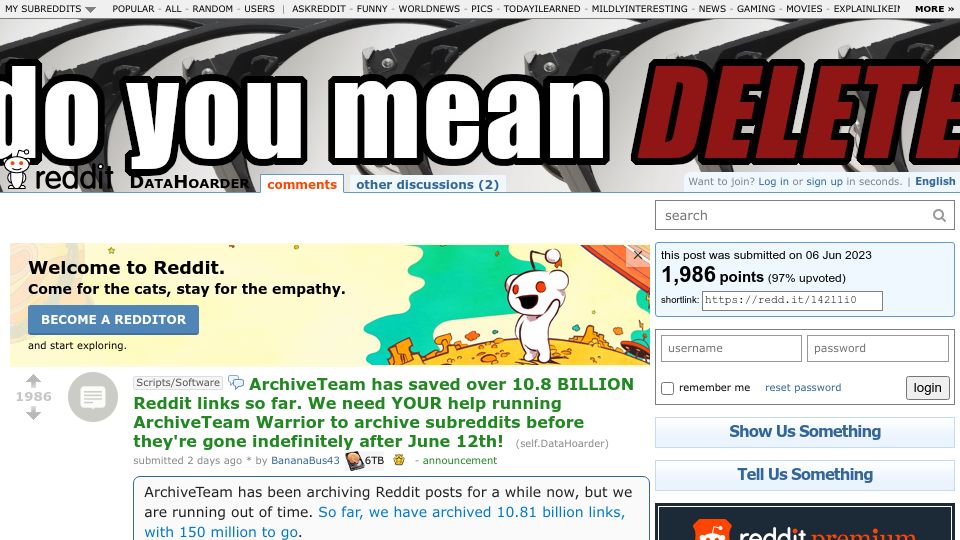
A r/DataHoarder post announcing ArchiveTeam has archived over 10.8 billion Reddit links and asking volunteers to run ArchiveTeam Warrior before subreddits go dark on June 12.