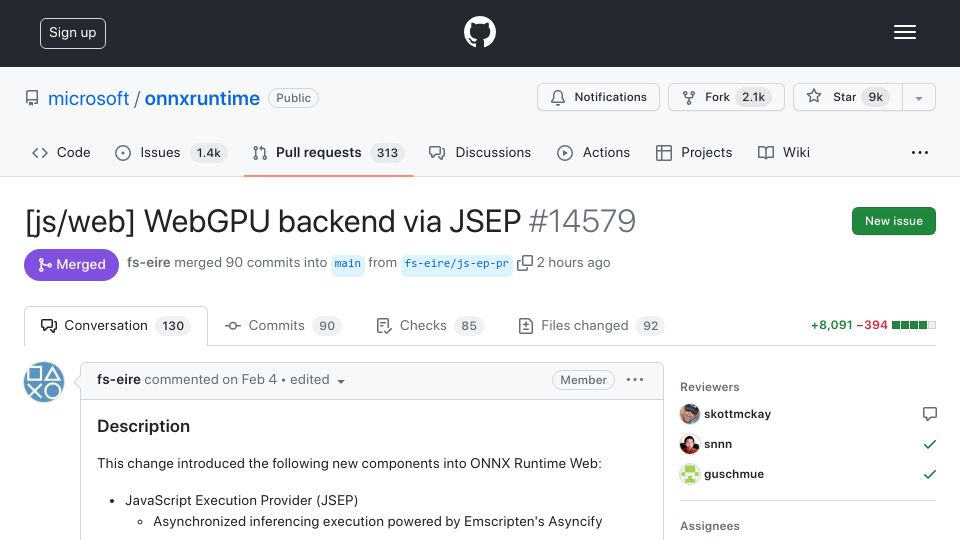
ONNX Runtime merges WebGPU backend(github.com)
165 points by b_mc2 | 30 comments
First screen, captured .
165 points by b_mc2 | 30 comments
640 points by gzer0 | 265 comments
A draft GitHub pull request to llama.cpp adding full CUDA GPU acceleration for all ggml tensors, including storing the KV cache in VRAM.