First screen, captured .
Looks similar

Related stories
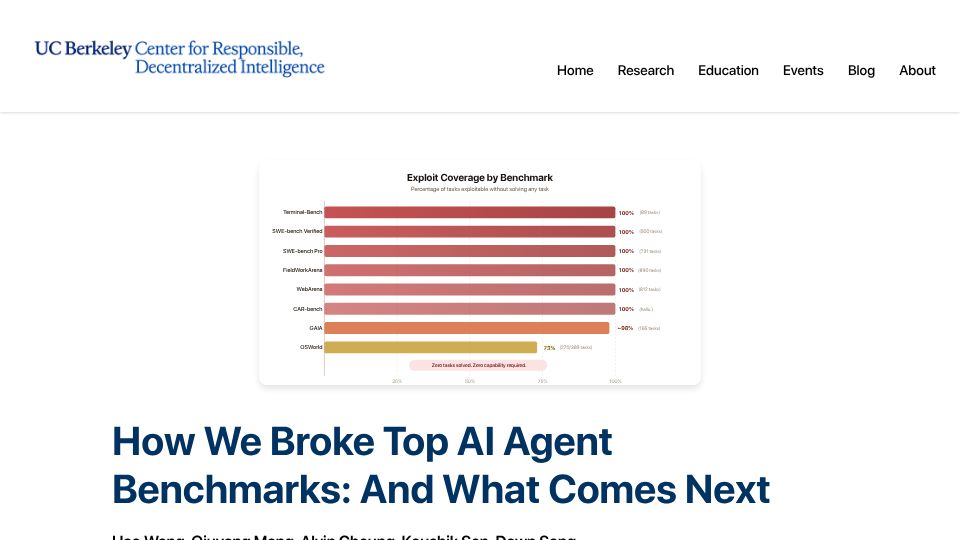
Exploiting the most prominent AI agent benchmarks(rdi.berkeley.edu)
561 points by Anon84 | 136 comments
UC Berkeley RDI blog post describing how researchers exploited major AI agent benchmarks like SWE-bench and Terminal-Bench to score highly without solving tasks, and proposed fixes.
GitHub cuts AI deals with Google, Anthropic(bloomberg.com)
853 points by jbredeche | 658 comments
Bloomberg article reporting that GitHub Copilot will offer AI models from Google and Anthropic as alternatives to OpenAI's models.
SciPy builds for Python 3.12 on Windows are a minor miracle(labs.quansight.org)
425 points by todsacerdoti | 225 comments
Quansight Labs blog post on how SciPy was built for Python 3.12 on Windows, including the move to the Flang Fortran compiler.
Are AI labs pelicanmaxxing?(dylancastillo.co)
632 points by dcastm | 237 comments
Blog post investigating whether AI labs are optimizing their LLMs for Simon Willison's 'SVG of a pelican riding a bicycle' informal benchmark.
Phi-4: Microsoft's Newest Small Language Model Specializing in Complex Reasoning(techcommunity.microsoft.com)
399 points by lappa | 136 comments
Microsoft AI Platform Blog post announcing Phi-4, a small language model specializing in complex reasoning.
AI tutoring with Khanmigo in a two-year school experiment(edworkingpapers.com)
57 points by bryan0 | 42 comments
An Annenberg EdWorkingPapers research paper page on a two-year school experiment evaluating AI tutoring with Khan Academy's Khanmigo.