Benchmark methodology is unconvincing
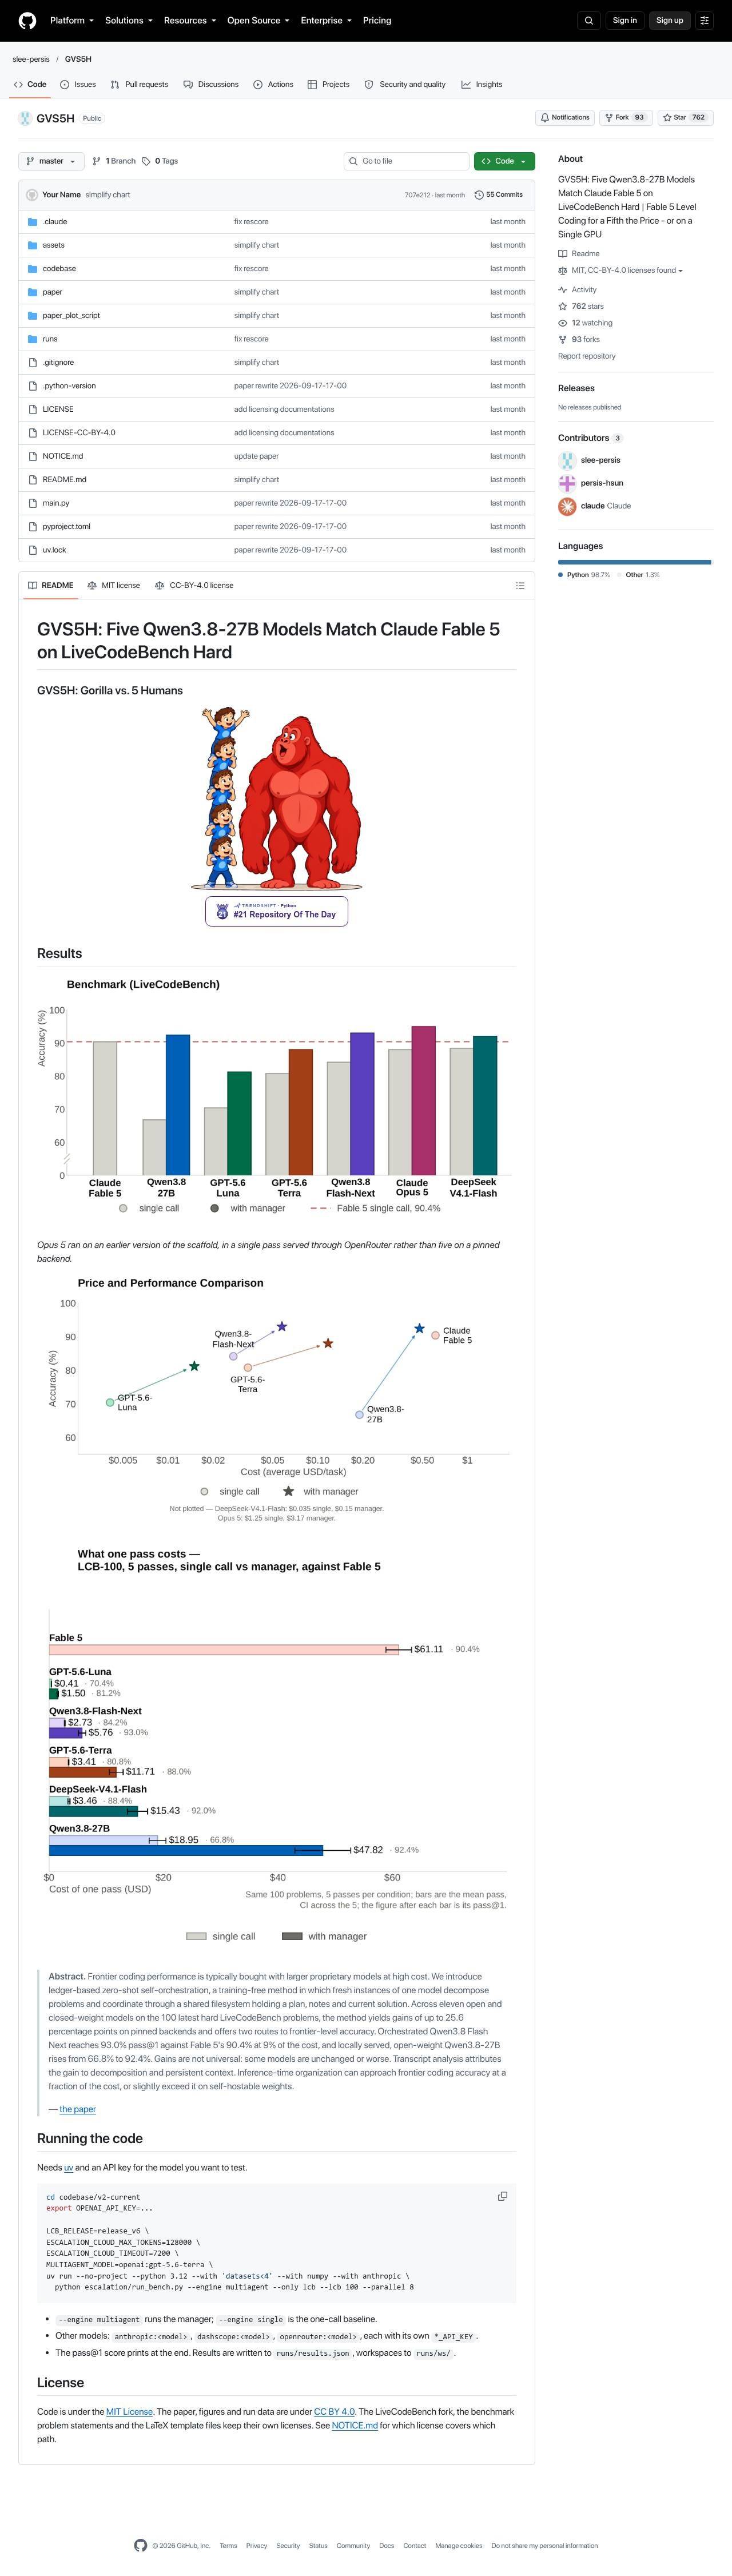
Critics note the benchmark is old, likely contaminated, and the harness broke its rules with tools and loops, with no comparison to harnessed frontier models.
Shared-file workflows already work
Several users already run similar plan/status/notes markdown setups with a single model, questioning whether the full manager-worker harness is needed.
Harness quality matters a lot
Commenters debate whether harnesses like Claude Code are holding models back, with most saying subagents work fine and the complainer likely has a config issue.