First screen, captured . Hover to scroll the page, or open the video.
Full page
Captured . Click for the whole screenshot.
Looks similar
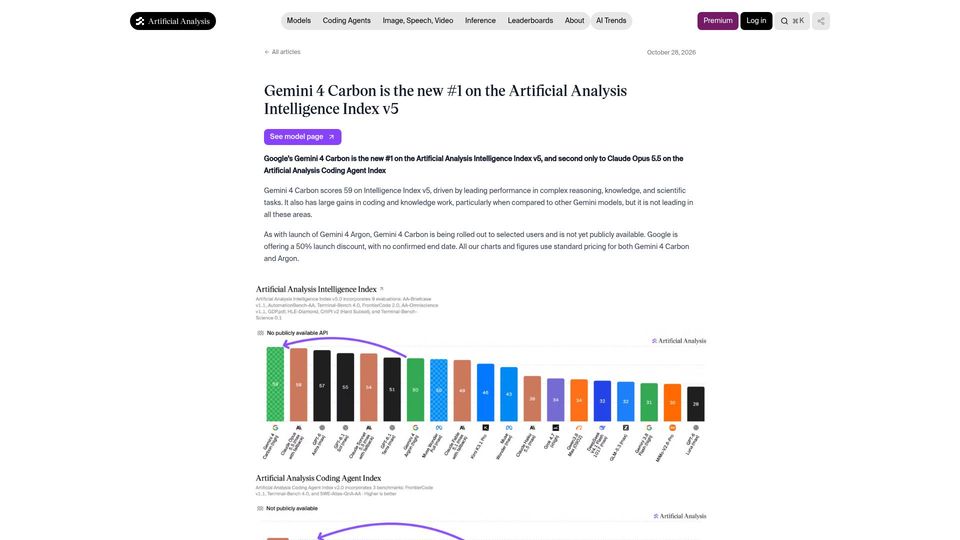
Gemini 4 Carbon is the new #1 on the Artificial Analysis Intelligence Index v5(artificialanalysis.ai)
298 points by theHocineSaad | 240 comments
Artificial Analysis article reporting that Google's Gemini 4 Carbon tops its Intelligence Index v5, with benchmark results, cost per task, and model details.
Qwen3.8 Max now ranked as the best overall model by agentic index(artificialanalysis.ai)
458 points by apitman | 291 comments
Artificial Analysis homepage offering independent benchmarks and rankings of AI models and providers, here linked to its agentic intelligence index view.
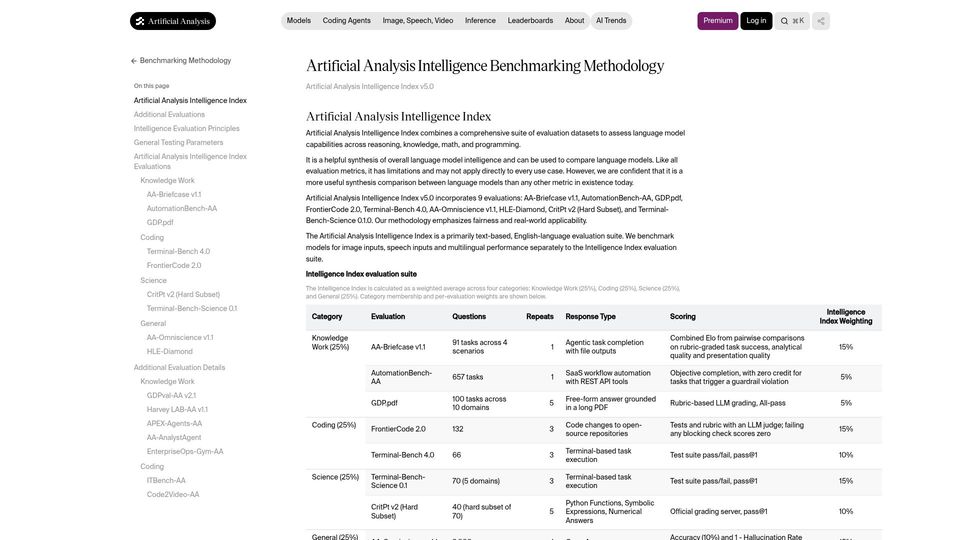
Artificial Analysis Intelligence Index v5.0(artificialanalysis.ai)
35 points by scooby7430 | 15 comments
Artificial Analysis's methodology page for its Intelligence Index v5.0, detailing the nine evaluations, category weightings, testing parameters and prompt templates used to rank LLMs.
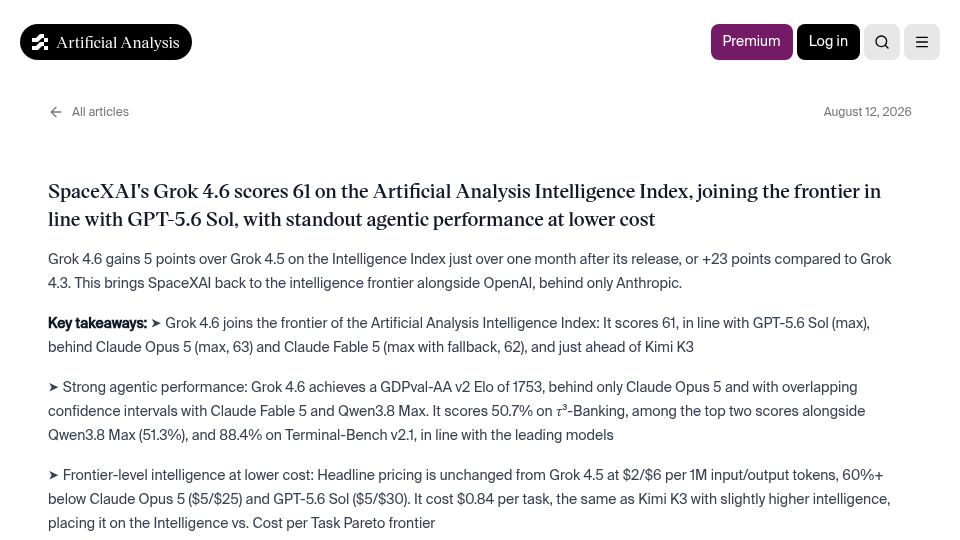
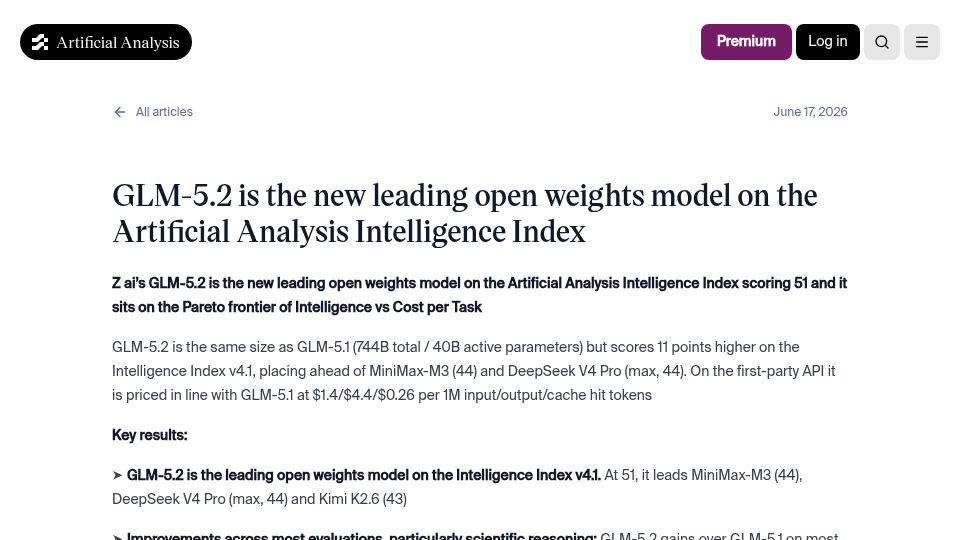
GLM-5.2 is the new leading open weights model on Artificial Analysis(artificialanalysis.ai)
845 points by himata4113 | 411 comments
Artificial Analysis article reporting that Z ai's GLM-5.2 scores 51 on its Intelligence Index, leading open weights models ahead of MiniMax-M3 and DeepSeek V4 Pro.
Related stories
Artificial Analysis Intelligence Index v5.0(artificialanalysis.ai)
35 points by scooby7430 | 15 comments
Artificial Analysis's methodology page for its Intelligence Index v5.0, detailing the nine evaluations, category weightings, testing parameters and prompt templates used to rank LLMs.
Study identifies weaknesses in how AI systems are evaluated(oii.ox.ac.uk)
397 points by pseudolus | 186 comments
Oxford Internet Institute news item on a study finding that most of 445 LLM benchmarks lack rigorous methods and clear definitions of what they measure.
Anthropic surpasses OpenAI to become most valuable AI startup(qazinform.com)
361 points by Bolat14 | 368 comments
Kazinform news article reporting that Anthropic surpassed OpenAI in valuation after a new funding round, approaching $1 trillion.
Qwen3.8 Max now ranked as the best overall model by agentic index(artificialanalysis.ai)
458 points by apitman | 291 comments
Artificial Analysis homepage offering independent benchmarks and rankings of AI models and providers, here linked to its agentic intelligence index view.
Recent AI models struggled to match a human algorithmic innovation(epoch.ai)
85 points by merksittich | 64 comments
Epoch AI report by David Owen presenting InnovationEval, finding early evidence that AI models cannot yet automate AI R&D or match human algorithmic innovation.
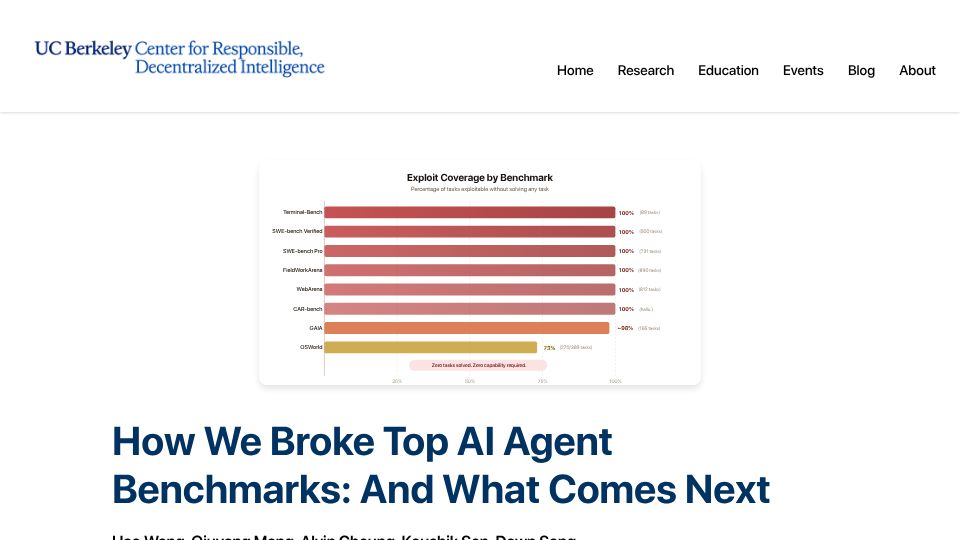
Exploiting the most prominent AI agent benchmarks(rdi.berkeley.edu)
561 points by Anon84 | 136 comments
UC Berkeley RDI blog post describing how researchers exploited major AI agent benchmarks like SWE-bench and Terminal-Bench to score highly without solving tasks, and proposed fixes.