AI agent benchmarks are broken(ddkang.substack.com)
167 points by neehao | 79 comments
First screen, captured . Hover to scroll the page, or open the video.
Captured . Click for the whole screenshot.
167 points by neehao | 79 comments
35 points by scooby7430 | 15 comments
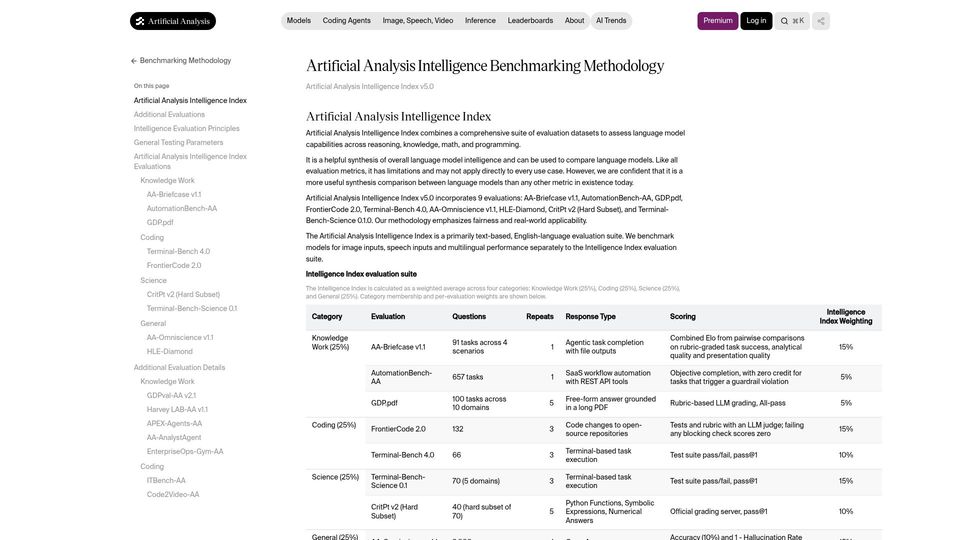
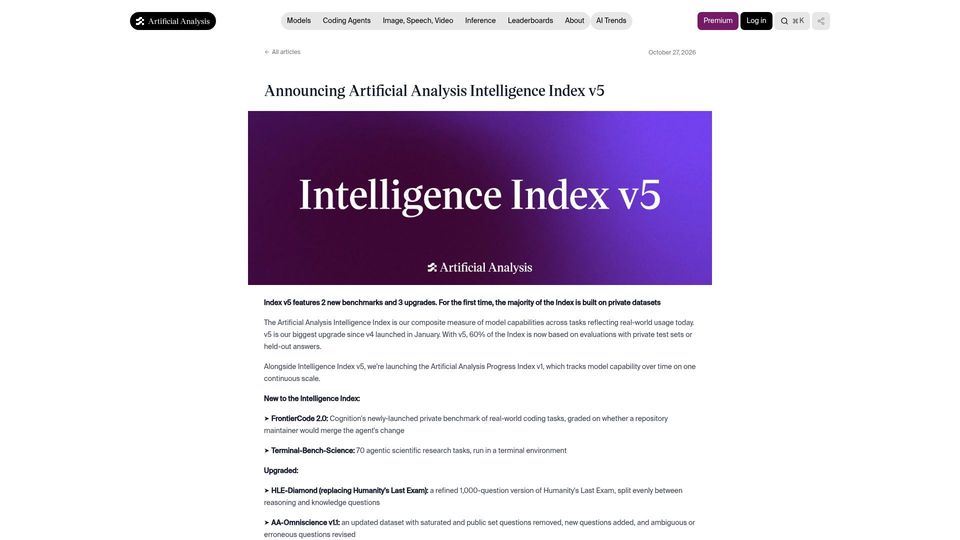
Artificial Analysis's methodology page for its Intelligence Index v5.0, detailing the nine evaluations, category weightings, testing parameters and prompt templates used to rank LLMs.
87 points by inaciom | 9 comments
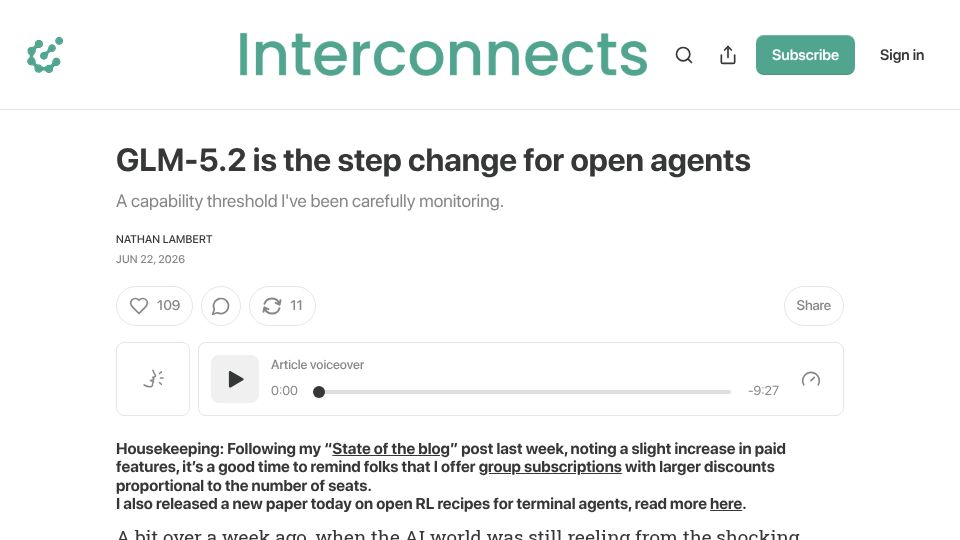
344 points by vantareed | 197 comments
Nathan Lambert's Interconnects post arguing that the GLM-5.2 model marks a capability threshold for open-weight agentic AI.
453 points by bx376 | 663 comments
An Economist Free exchange column arguing that artificial intelligence is losing hype and asking whether that signals the technology will eventually succeed.
555 points by kgwgk | 200 comments
Nature news article on a growing movement using AI and large language models to detect errors in research papers, sparked by a flawed black plastic utensils study.
52 points by hn-aarvin | 77 comments
Artificial Analysis announces Intelligence Index v5, a composite LLM benchmark adding new private evaluations, with results ranking frontier and open-weights models plus a new Progress Index.
175 points by heavensteeth | 148 comments
A personal wiki essay arguing that blaming LLMs for harmful outcomes is decision laundering and that AI companies like OpenAI and Anthropic bear responsibility.
768 points by themgt | 300 comments
An informal research essay by Nick Cammarata at Goodfire arguing polysemanticity stems from fixable issues, not superposition, making neurons interpretable at scale.
463 points by benbreen | 222 comments
Benjamin Breen's Res Obscura essay arguing quality non-fiction books counter AI slop, introducing a vibe-coded tool indexing prize-winning books.