Open local models must keep pace
Many worry about frontier lab censorship and restrictions and want open-weight models to keep improving, not just stay frozen at today's level, especially since knowledge cutoffs age.
Benchmark is saturated and contaminated
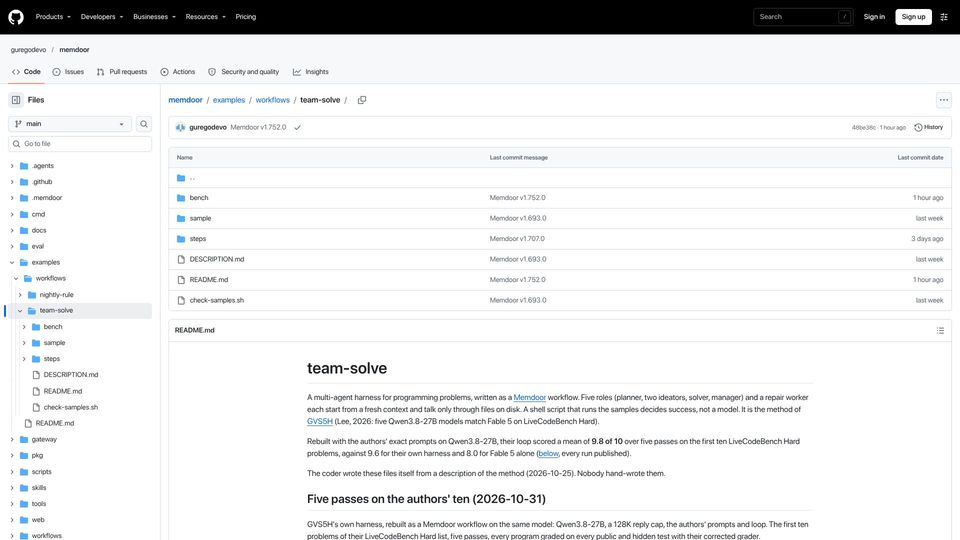
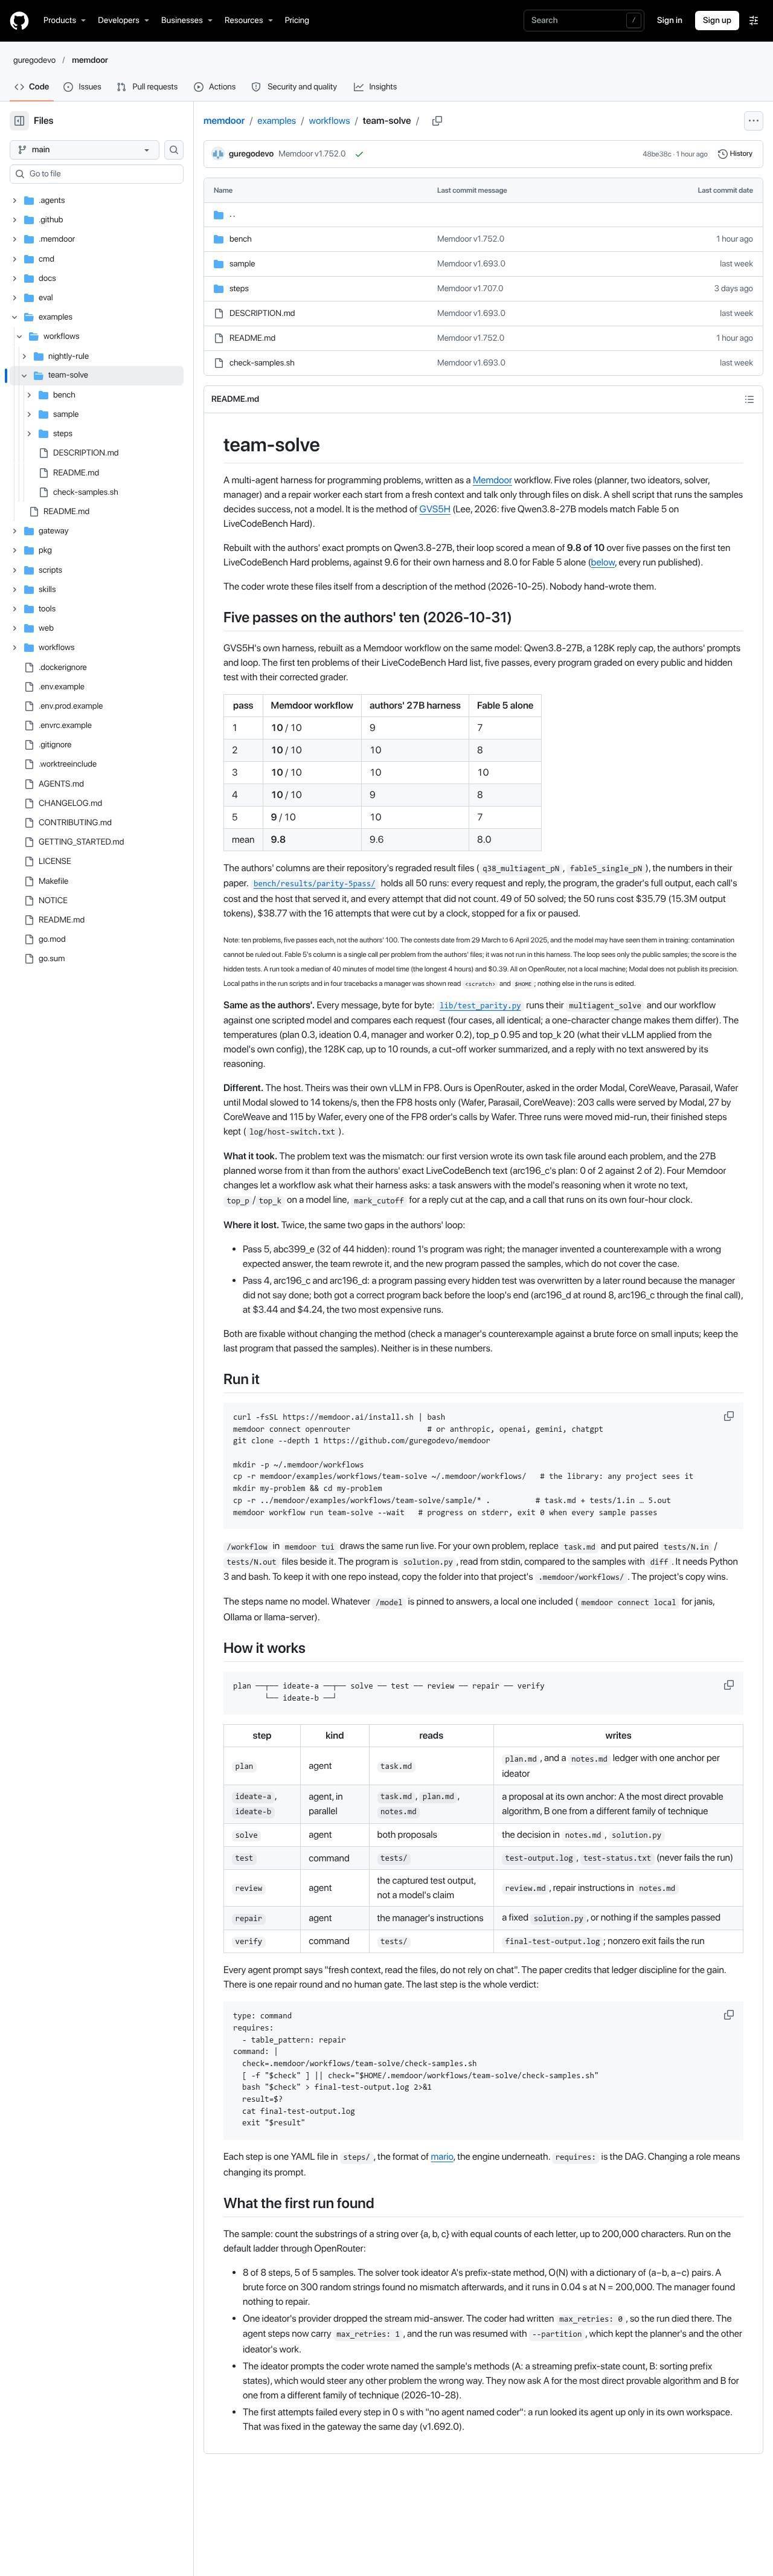
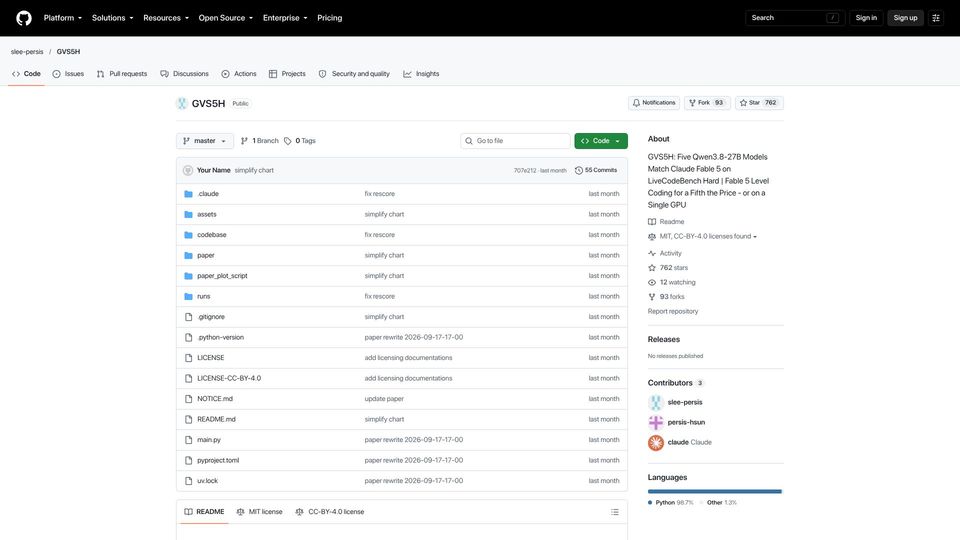
Skeptics note only ten problems from an old LiveCodeBench Hard set were used, so parity with Fable 5 says little about real agentic work.
Brute force can't replace intelligence
Users report heavy quants like Bonsai 2-bit and swarms of small models loop on the same mistakes, while others find Qwen 27B fast and good enough for many tasks.