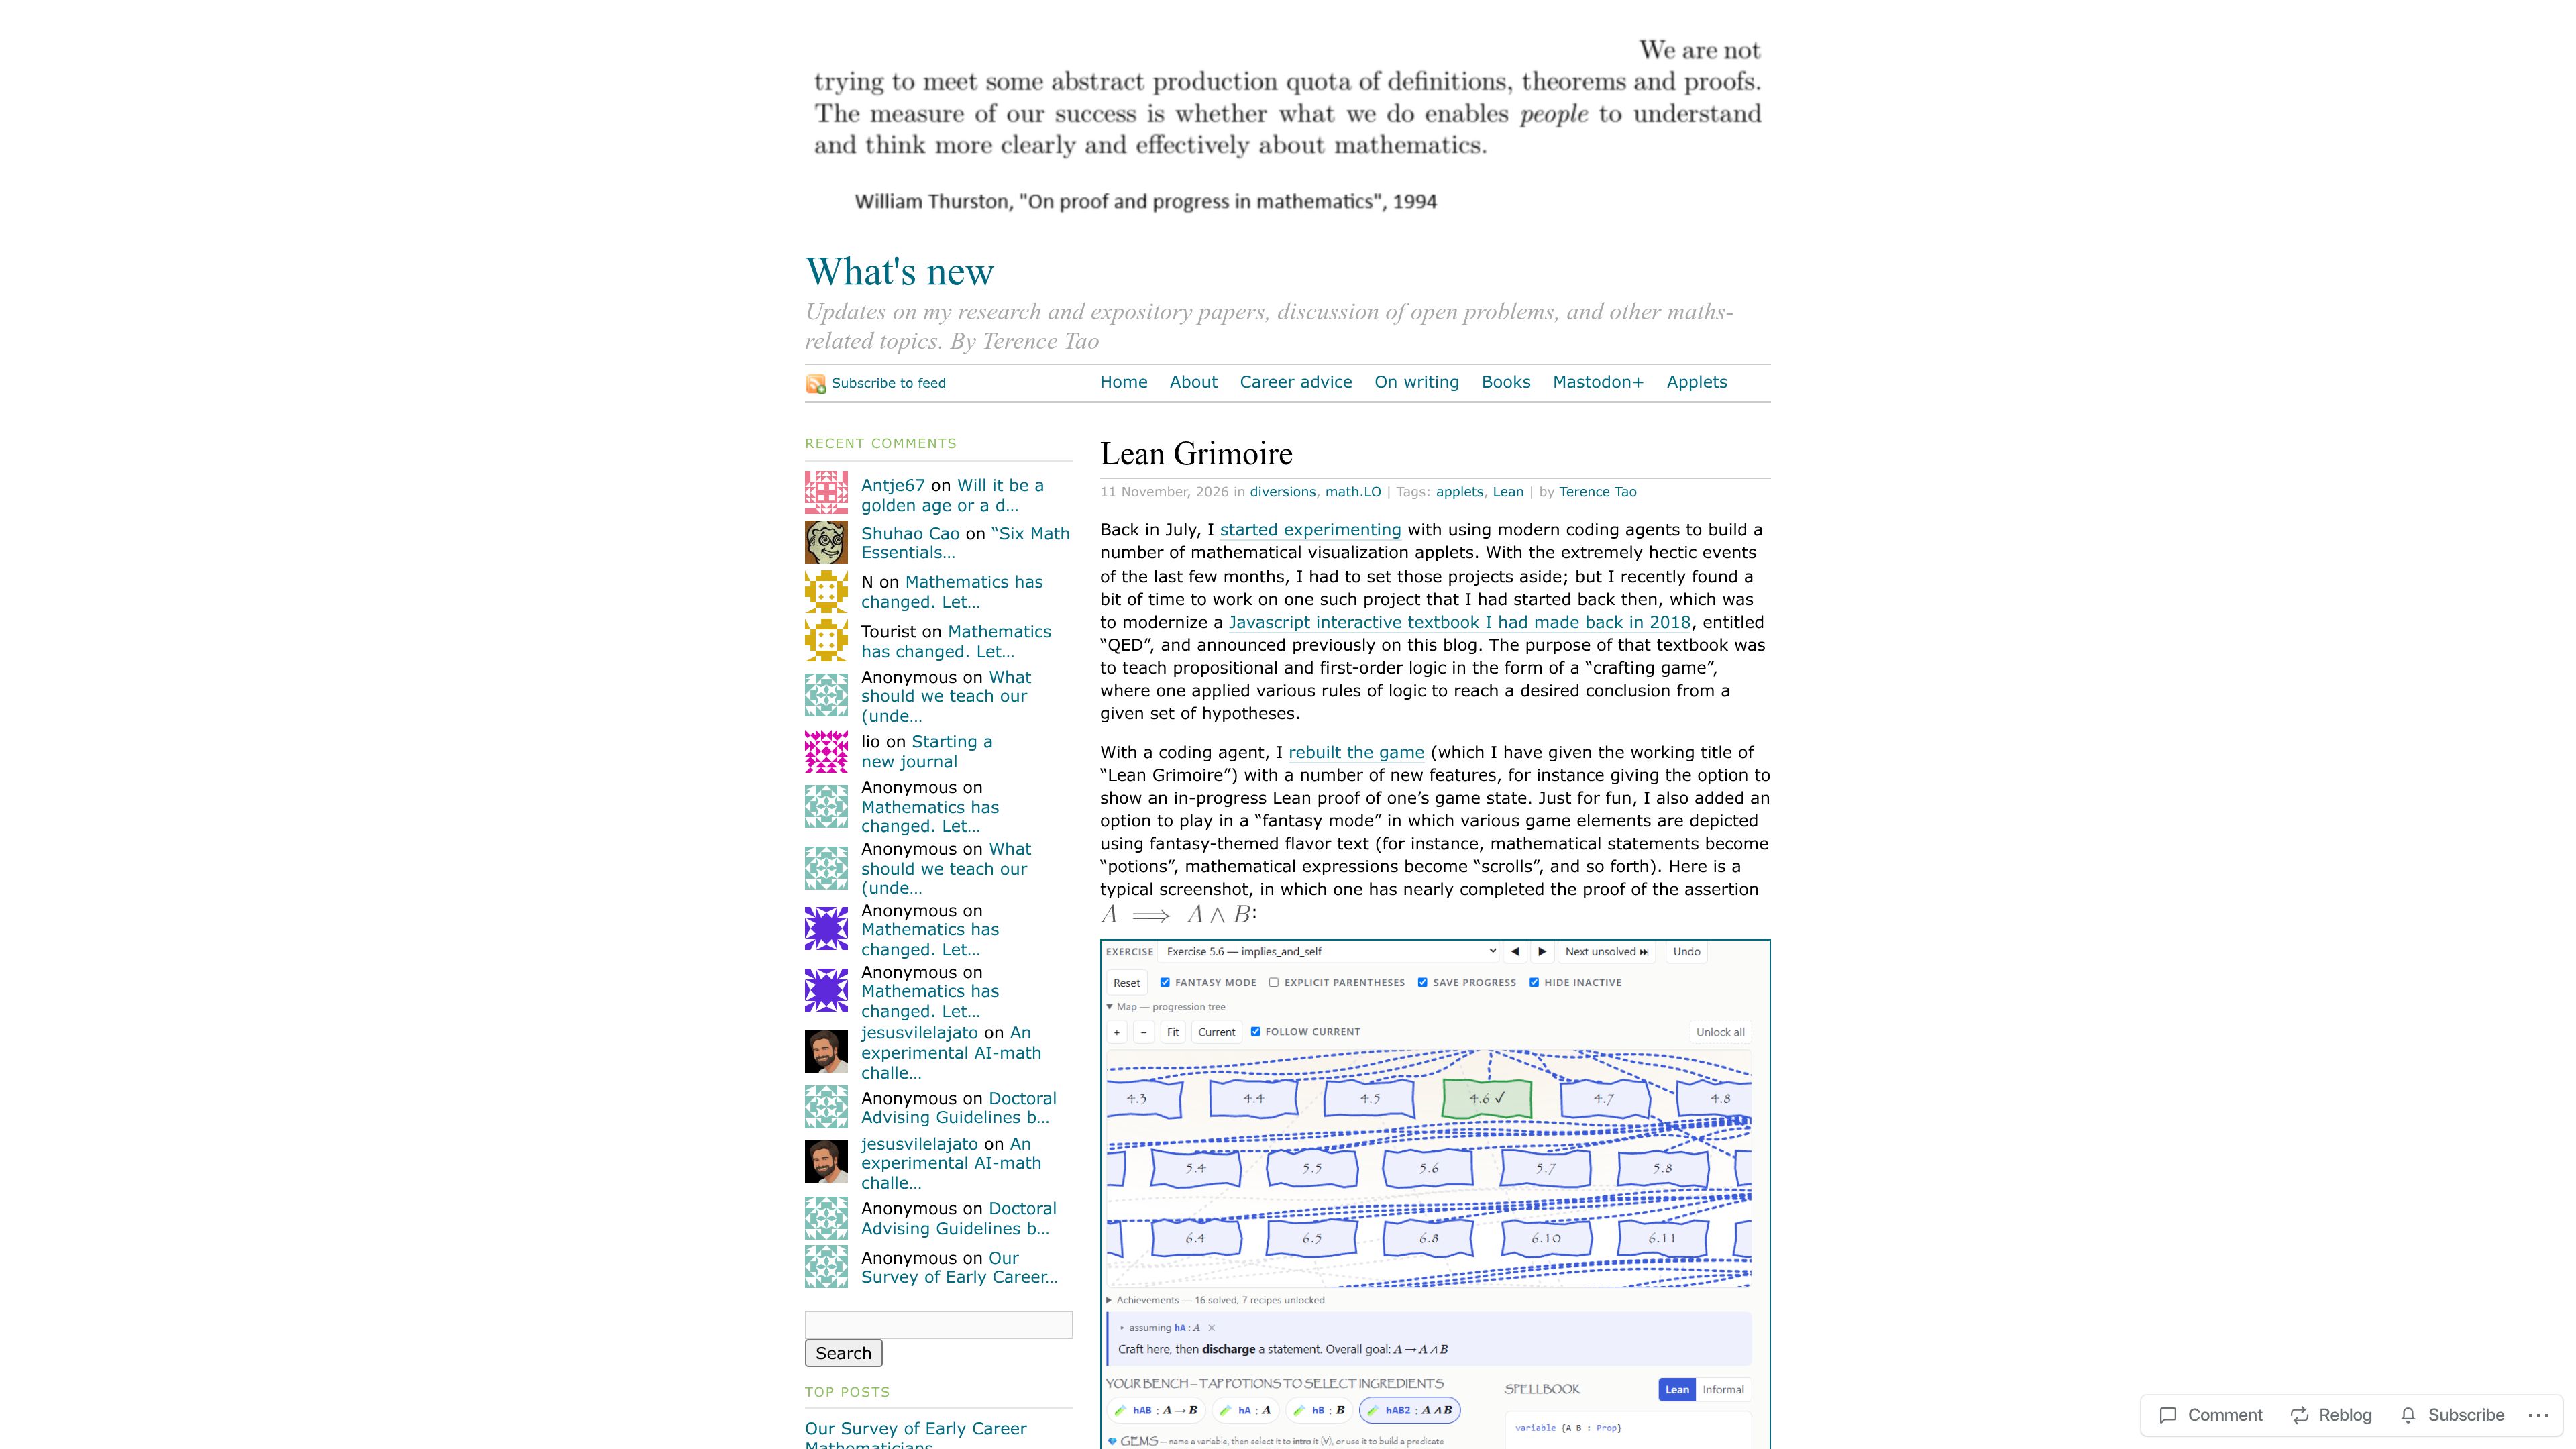
Lean Grimoire(terrytao.wordpress.com)
51 points by smilelamp | 8 comments
Terence Tao blog post announcing Lean Grimoire, a coding-agent-rebuilt version of his QED logic crafting game with Lean proof display and a fantasy mode.
First screen, captured . Open the video.
Captured . Click for the whole screenshot.
51 points by smilelamp | 8 comments
Terence Tao blog post announcing Lean Grimoire, a coding-agent-rebuilt version of his QED logic crafting game with Lean proof display and a fantasy mode.
63 points by pbohun | 18 comments
Pigshell 0.6.4 is a browser-based Unix-style shell that represents web resources and cloud data as files you can process with command pipelines.
26 points by leduyquang753 | 7 comments
A blog post by Luther Tychonievich explaining how to draw variable-width (pressure-sensitive) Bézier curves with current 2D graphics APIs for board-work tablet apps.
239 points by erikgahner | 116 comments
A blog post arguing that GitHub 'awesome' curated lists have become less useful due to outdated content and floods of AI-generated pull requests promoting vibe-coded sites.
8 points by yubblegum | 1 comments
English translation of Pliny the Younger's Letter 7.27 to Sura, recounting ghost stories including Athenodorus and the haunted house in Athens.
59 points by atan2 | 23 comments
DJ Delorie's 1998 history of DJGPP, the port of GCC to MS-DOS, covering its origins, the go32 extender, and releases through version 2.02.
338 points by dataminer | 121 comments
ByteShape blog post describing how they quantized Qwen3-30B-A3B-Instruct with their Shapelearn bitlength method to run in real time on a Raspberry Pi.
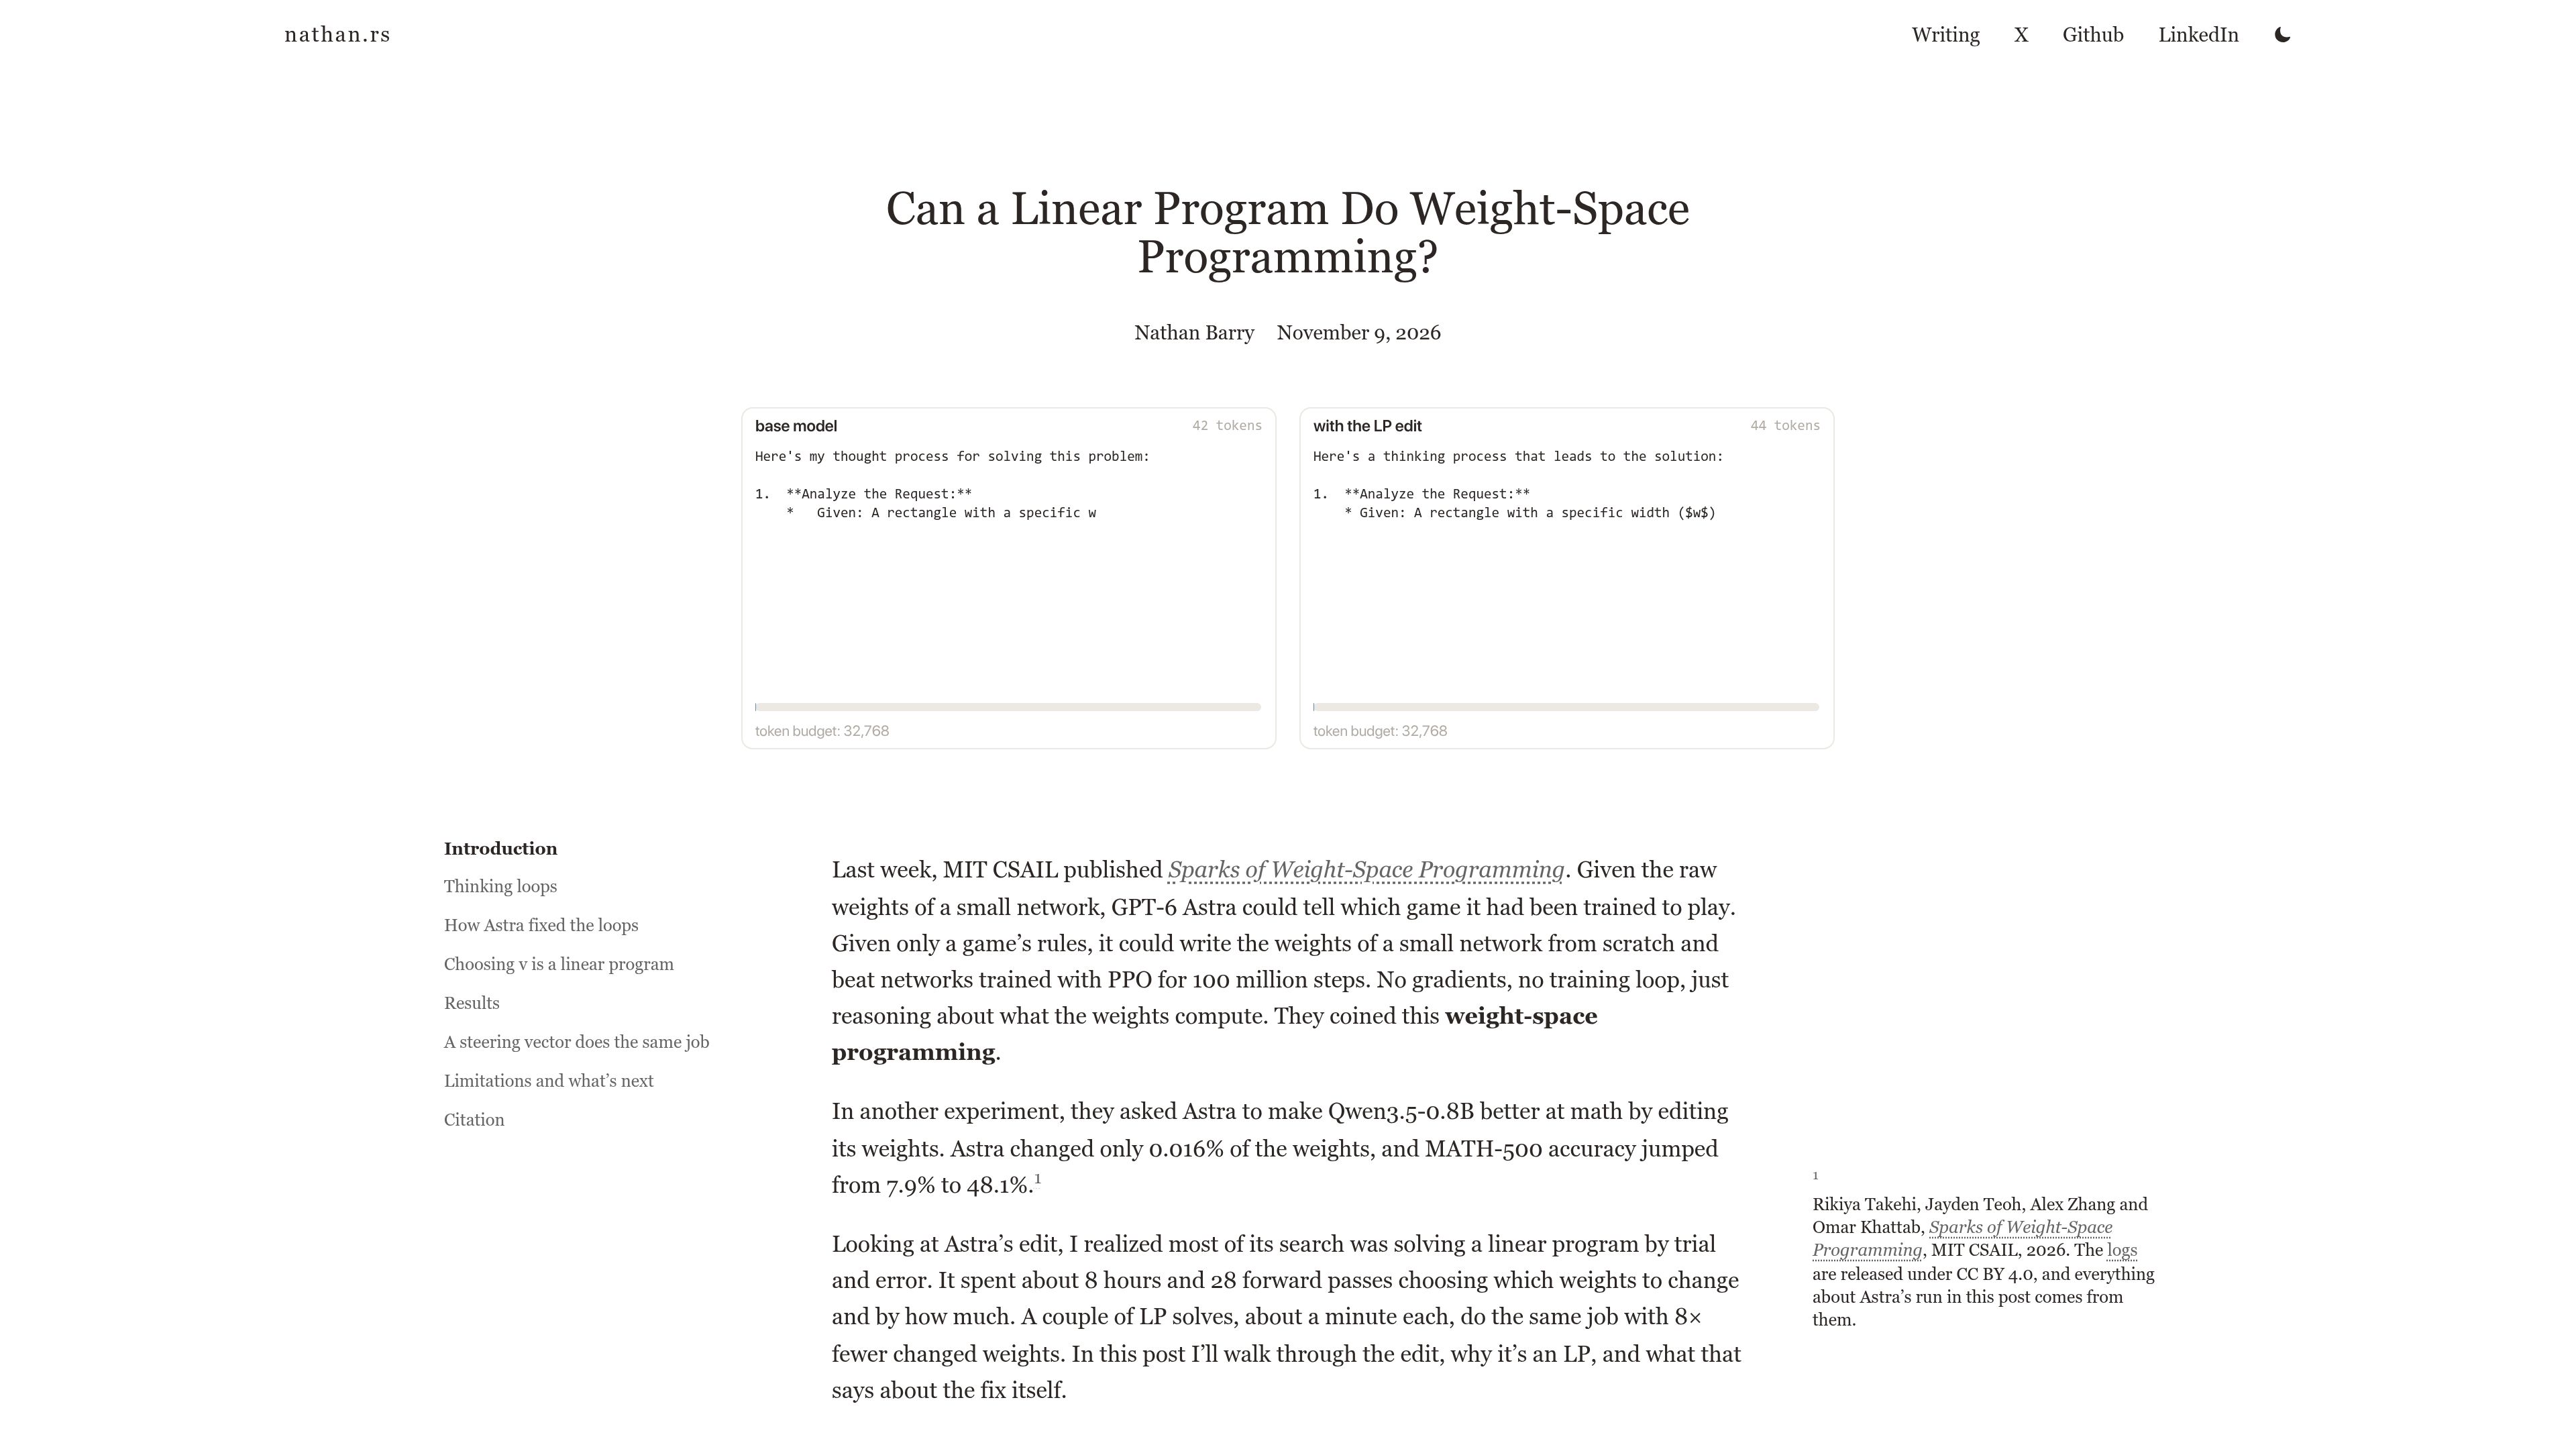
285 points by emschwartz | 41 comments
Blog post arguing that a model's weight edit fixing Qwen3.5-0.8B thinking loops can be reproduced by solving a linear program, with fewer changed weights.
15 points by rafaeldavidtin | 1 comments
Blog post from Stealthium on detecting tampering of AI model weights in GPU memory, such as ROME model-editing attacks.
1102 points by signa11 | 407 comments
Blog post by Nolan Lawson arguing that LLMs can be used to write higher-quality code more slowly, such as finding bugs, rather than producing low-quality code fast.
7 points by Ir0n | 0 comments
A page from meshapplied.com about running a Qwen LLM at 255 tokens per second on a single Nvidia RTX 5090 GPU; no page content was captured.
2884 points by dbreunig | 869 comments
MIT CSAIL blog post reporting that frontier LLMs can read, fix, and write neural network weights directly, including editing Qwen3.5-0.8B to improve math performance.