Pigshell: Unix the Web(pigshell.com)
63 points by pbohun | 18 comments
Pigshell 0.6.4 is a browser-based Unix-style shell that represents web resources and cloud data as files you can process with command pipelines.
First screen, captured . Open the video.
Captured . Click for the whole screenshot.
63 points by pbohun | 18 comments
Pigshell 0.6.4 is a browser-based Unix-style shell that represents web resources and cloud data as files you can process with command pipelines.
42 points by niceguitars | 2 comments
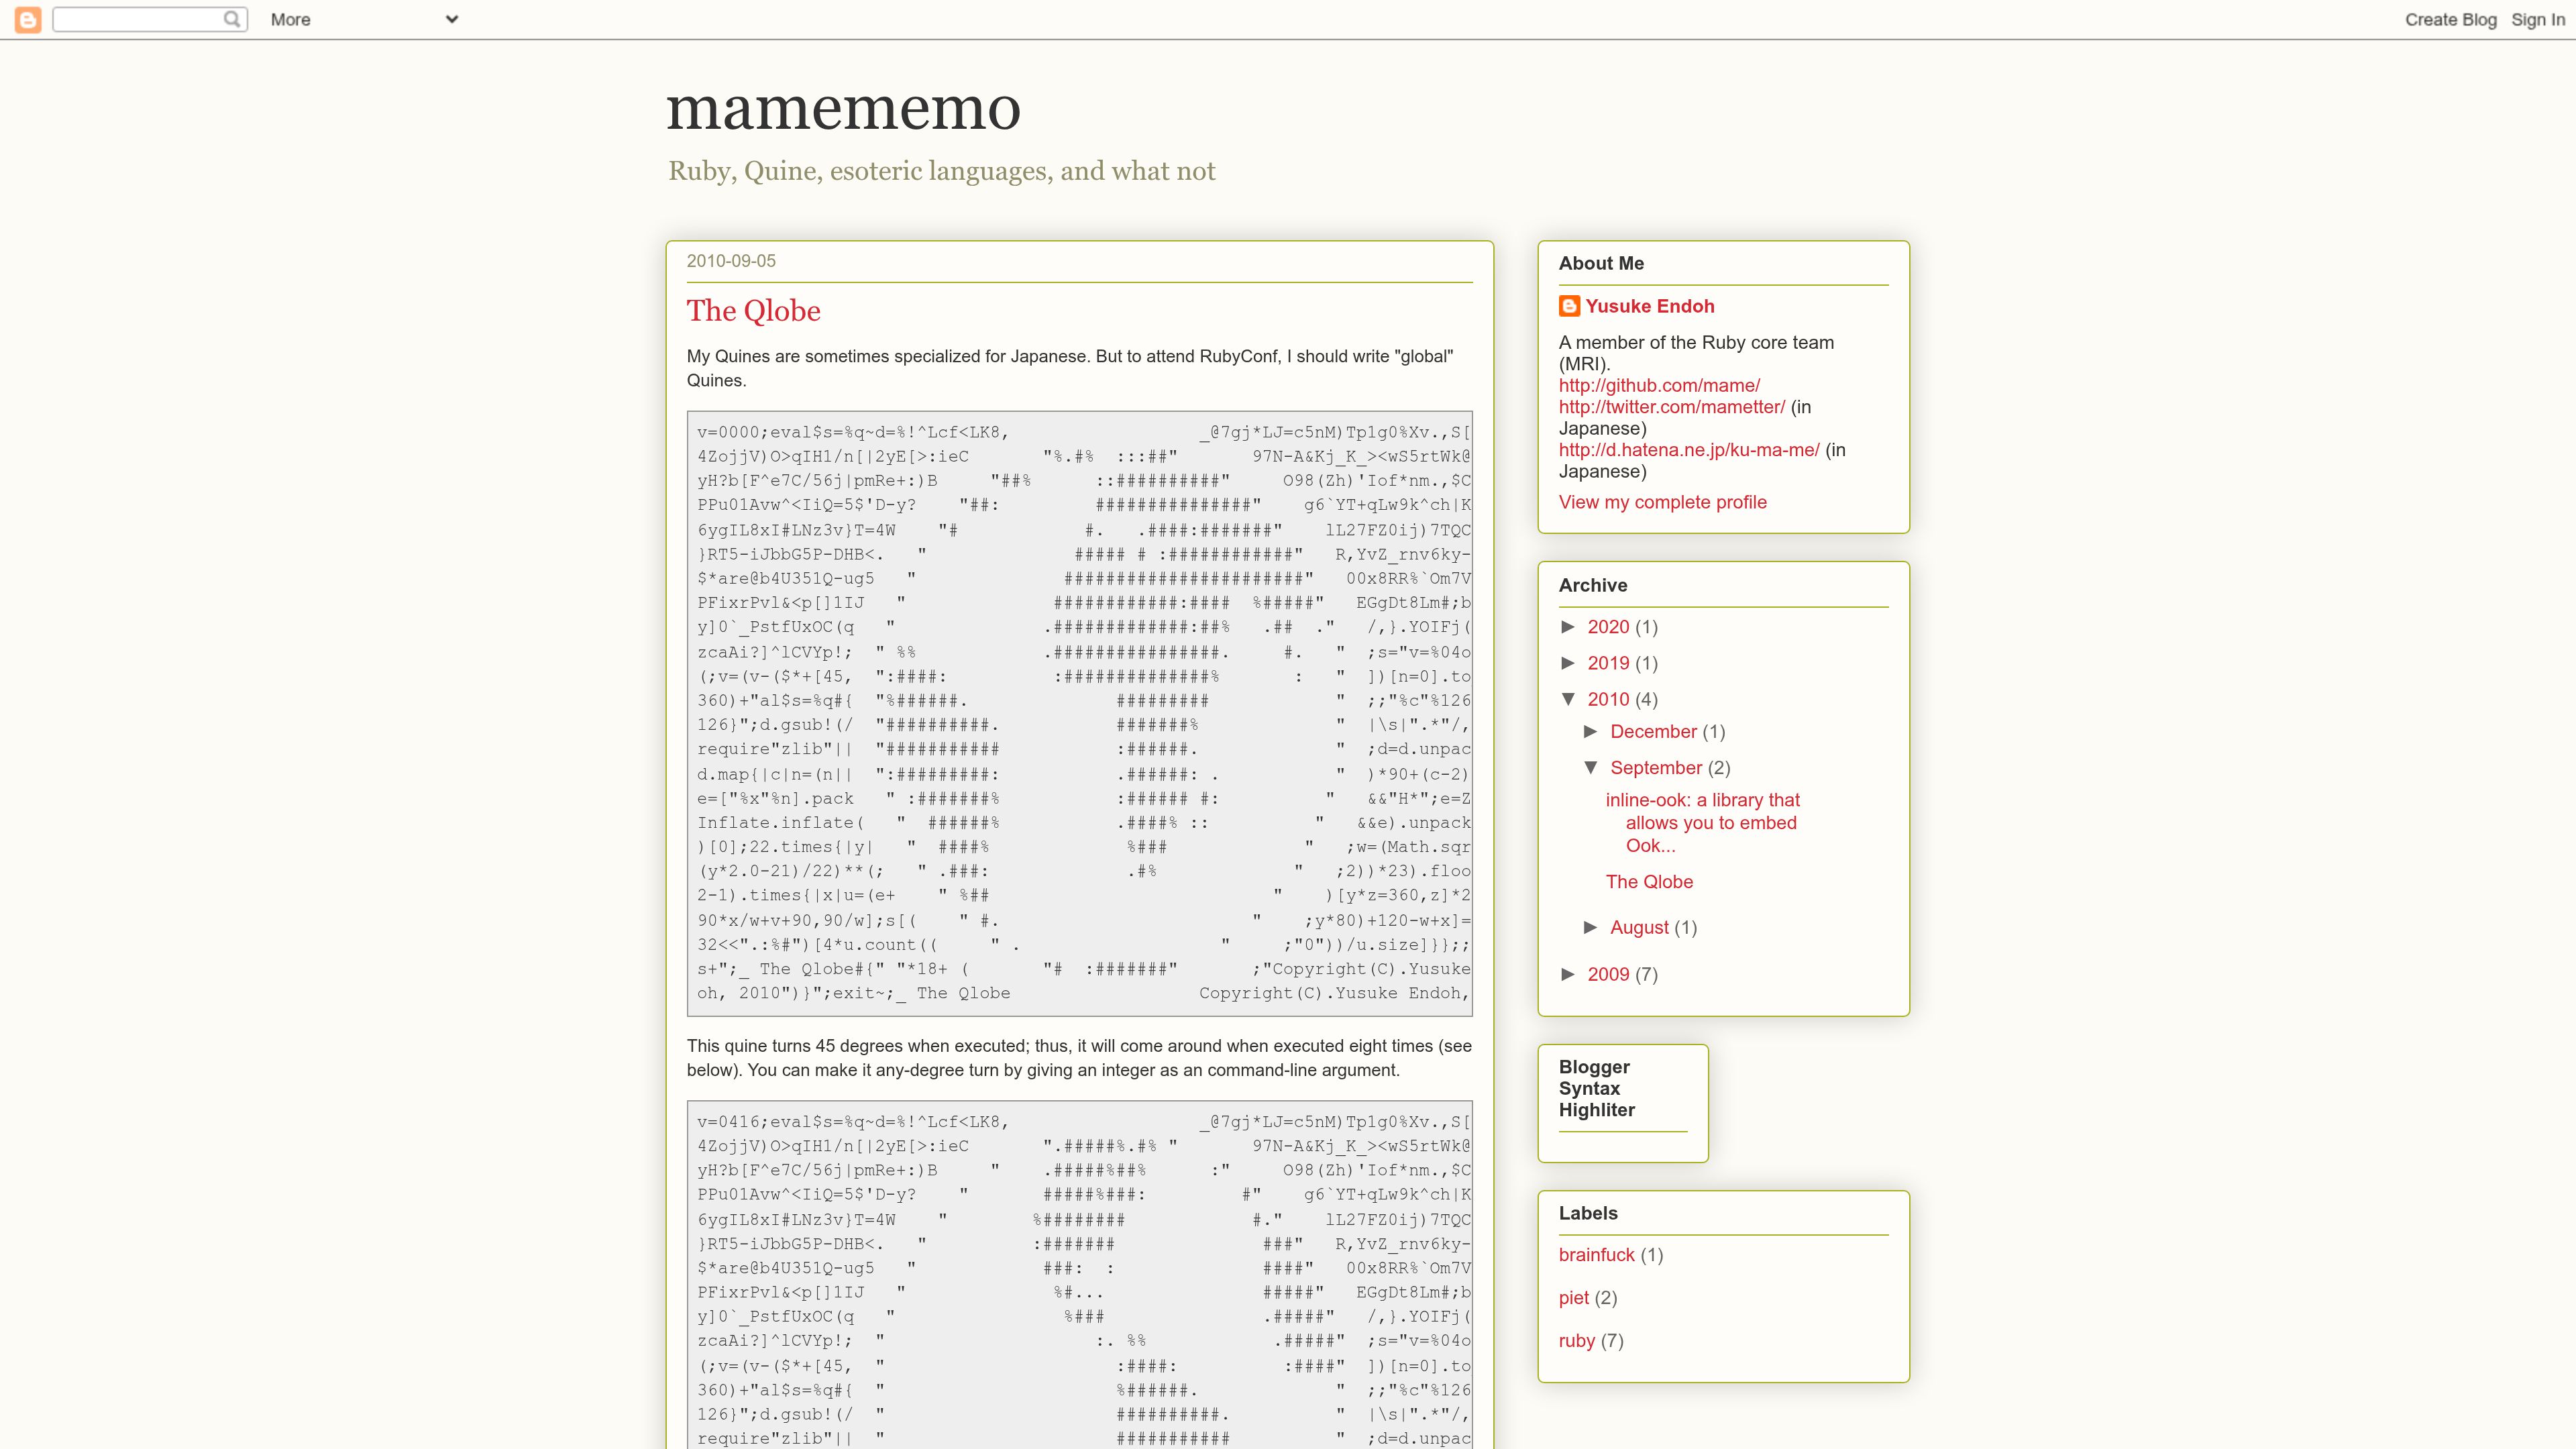
Blog post by Yusuke Endoh presenting the Qlobe, a Ruby quine shaped like a globe that rotates 45 degrees each time it is executed.
51 points by smilelamp | 8 comments
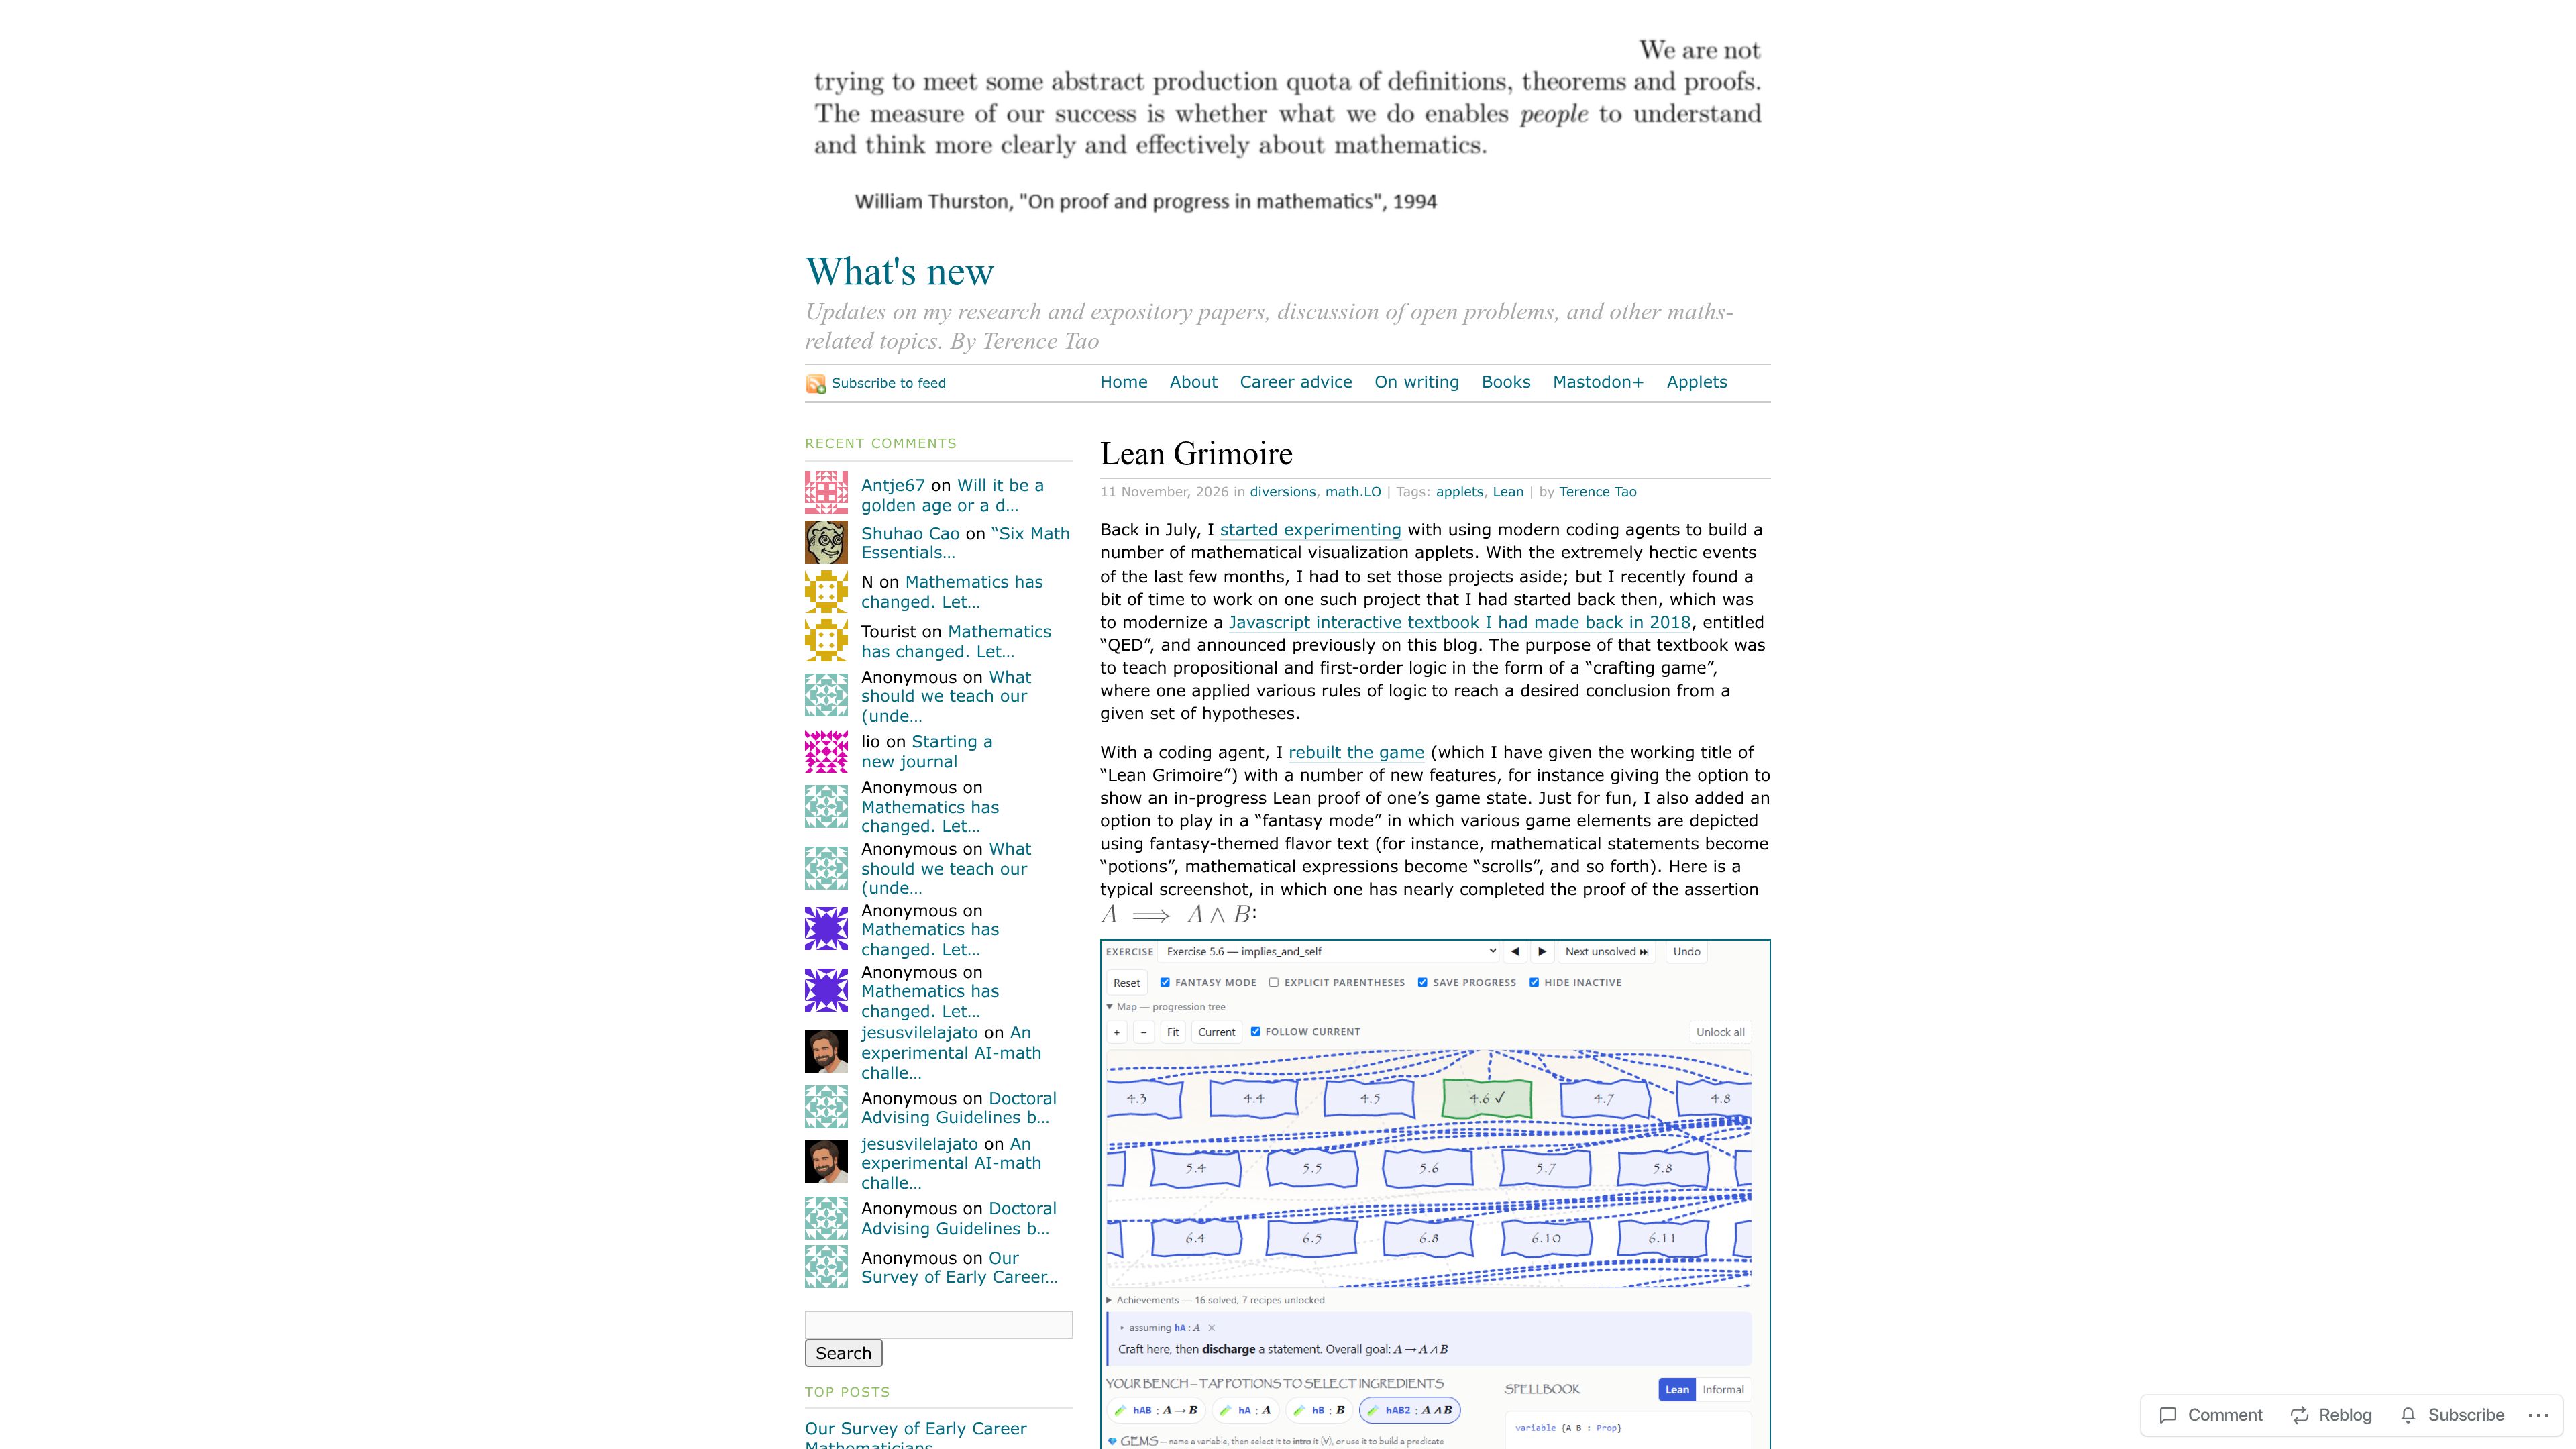
Terence Tao blog post announcing Lean Grimoire, a coding-agent-rebuilt version of his QED logic crafting game with Lean proof display and a fantasy mode.
26 points by leduyquang753 | 7 comments
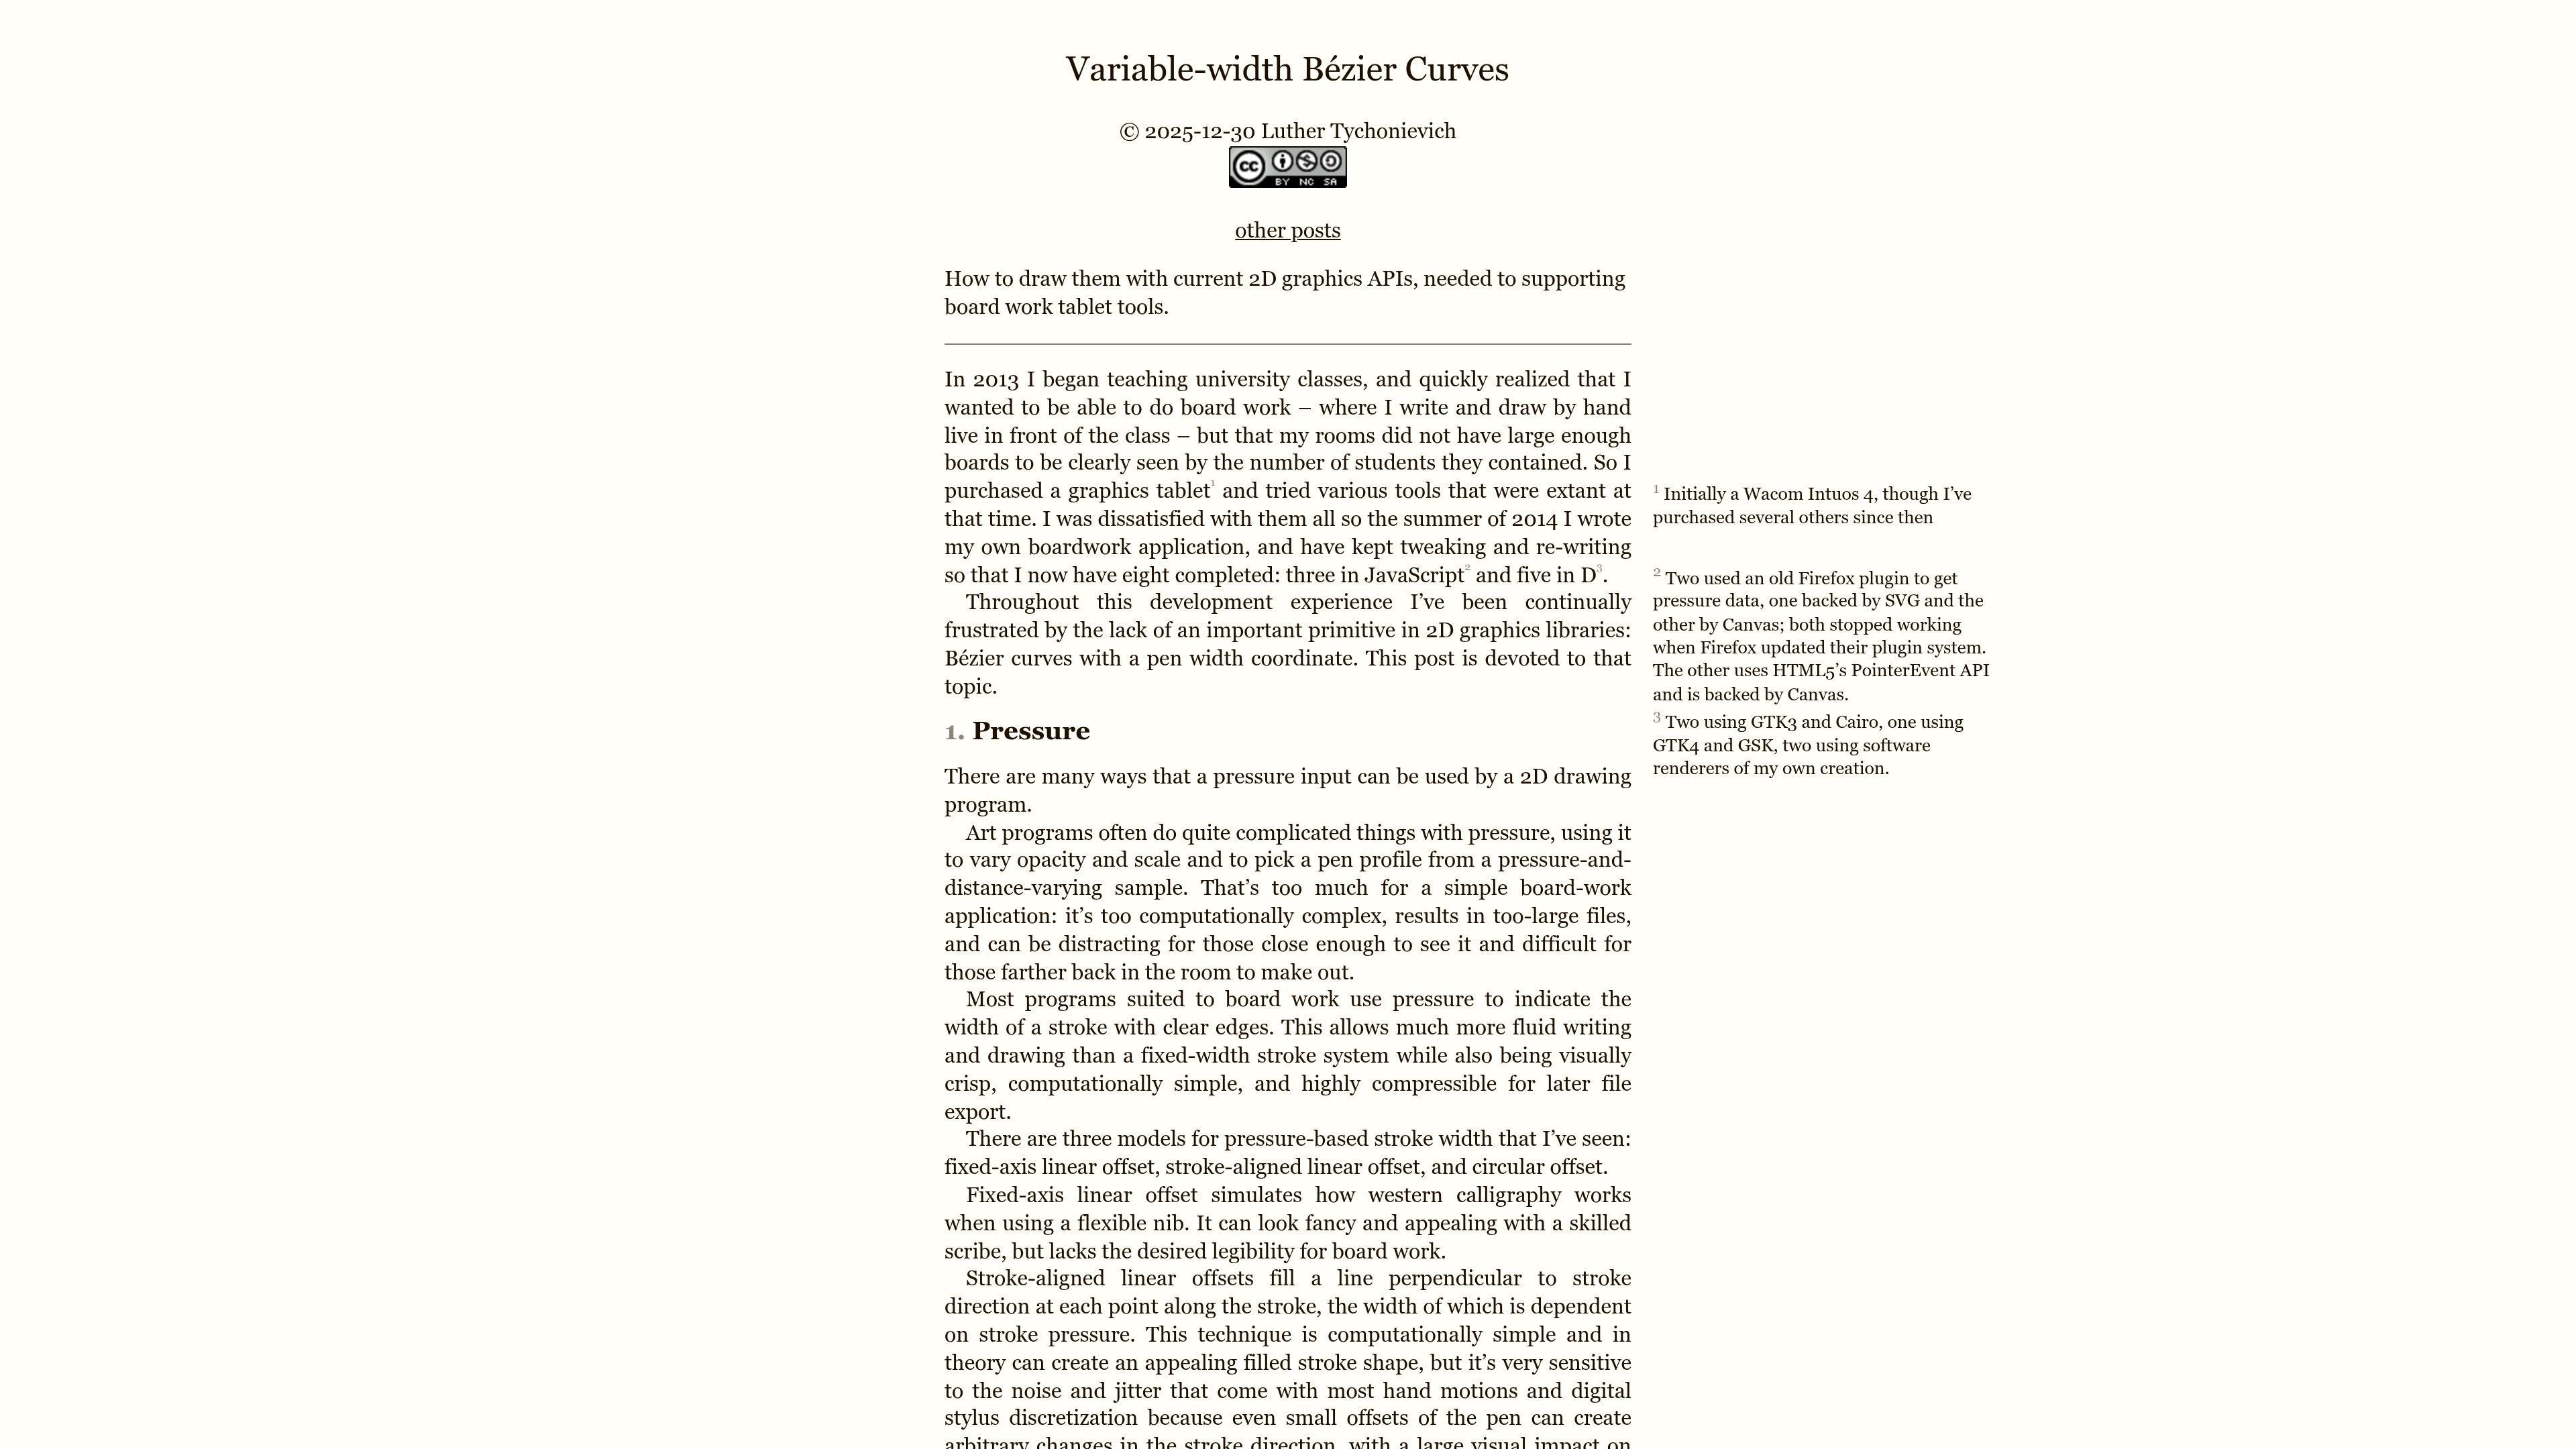
A blog post by Luther Tychonievich explaining how to draw variable-width (pressure-sensitive) Bézier curves with current 2D graphics APIs for board-work tablet apps.
239 points by erikgahner | 116 comments
A blog post arguing that GitHub 'awesome' curated lists have become less useful due to outdated content and floods of AI-generated pull requests promoting vibe-coded sites.
120 points by dverlaeckt80 | 51 comments
A blog post describing how the author typeset two self-written novellas using groff with a custom macro package, plus Markdown pre-processing, Vim, and Git.
333 points by mustaphah | 142 comments
arXiv paper presenting SkillsBench, a benchmark of 86 tasks across 11 domains measuring whether structured Agent Skills improve LLM agent performance.
431 points by wcrichton | 124 comments
Brown University Cognitive Engineering Lab blog post summarizing a paper comparing how async/await designs differ across programming languages.
119 points by florianstandhar | 32 comments
Benchmark Heaven's JevBench v1.3.0 leaderboard page ranking 52 Jev-class typed decision models on intelligence, calibration, speed and cost across 534 decisions.
79 points by sumnole | 102 comments
OpenAI research publication on improving its models' coding abilities in low-resource programming languages like COBOL, Fortran, OCaml, and Visual Basic.
45 points by eatonphil | 3 comments
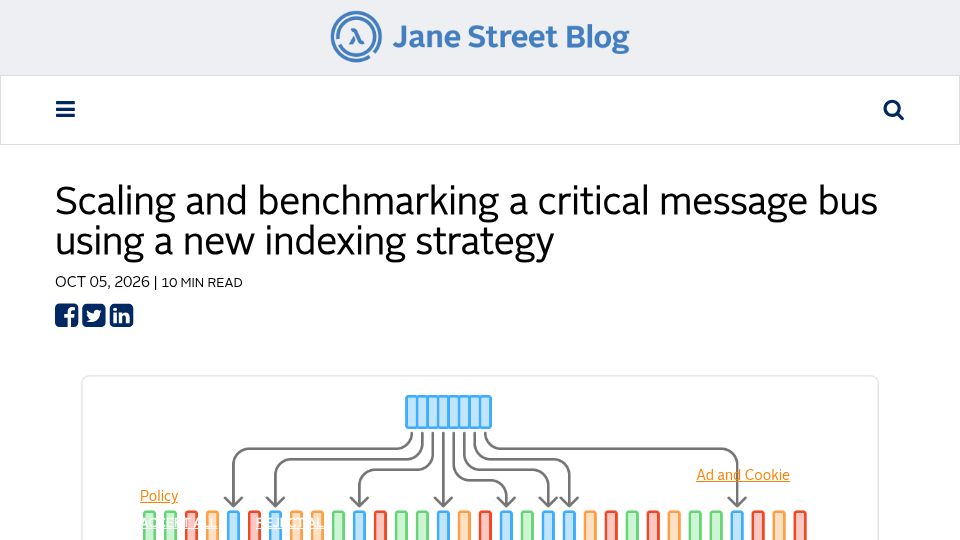
Jane Street blog post on scaling and benchmarking a critical internal message bus using a new indexing strategy.
331 points by joshwa | 113 comments
arXiv paper introducing SWE-Bench+, an empirical analysis revealing data quality issues in the SWE-bench coding benchmark for LLMs, such as solution leakage and weak tests.