Multi-Token Prediction Done Right(arxiv.org)
3 points by matt_d | 2 comments
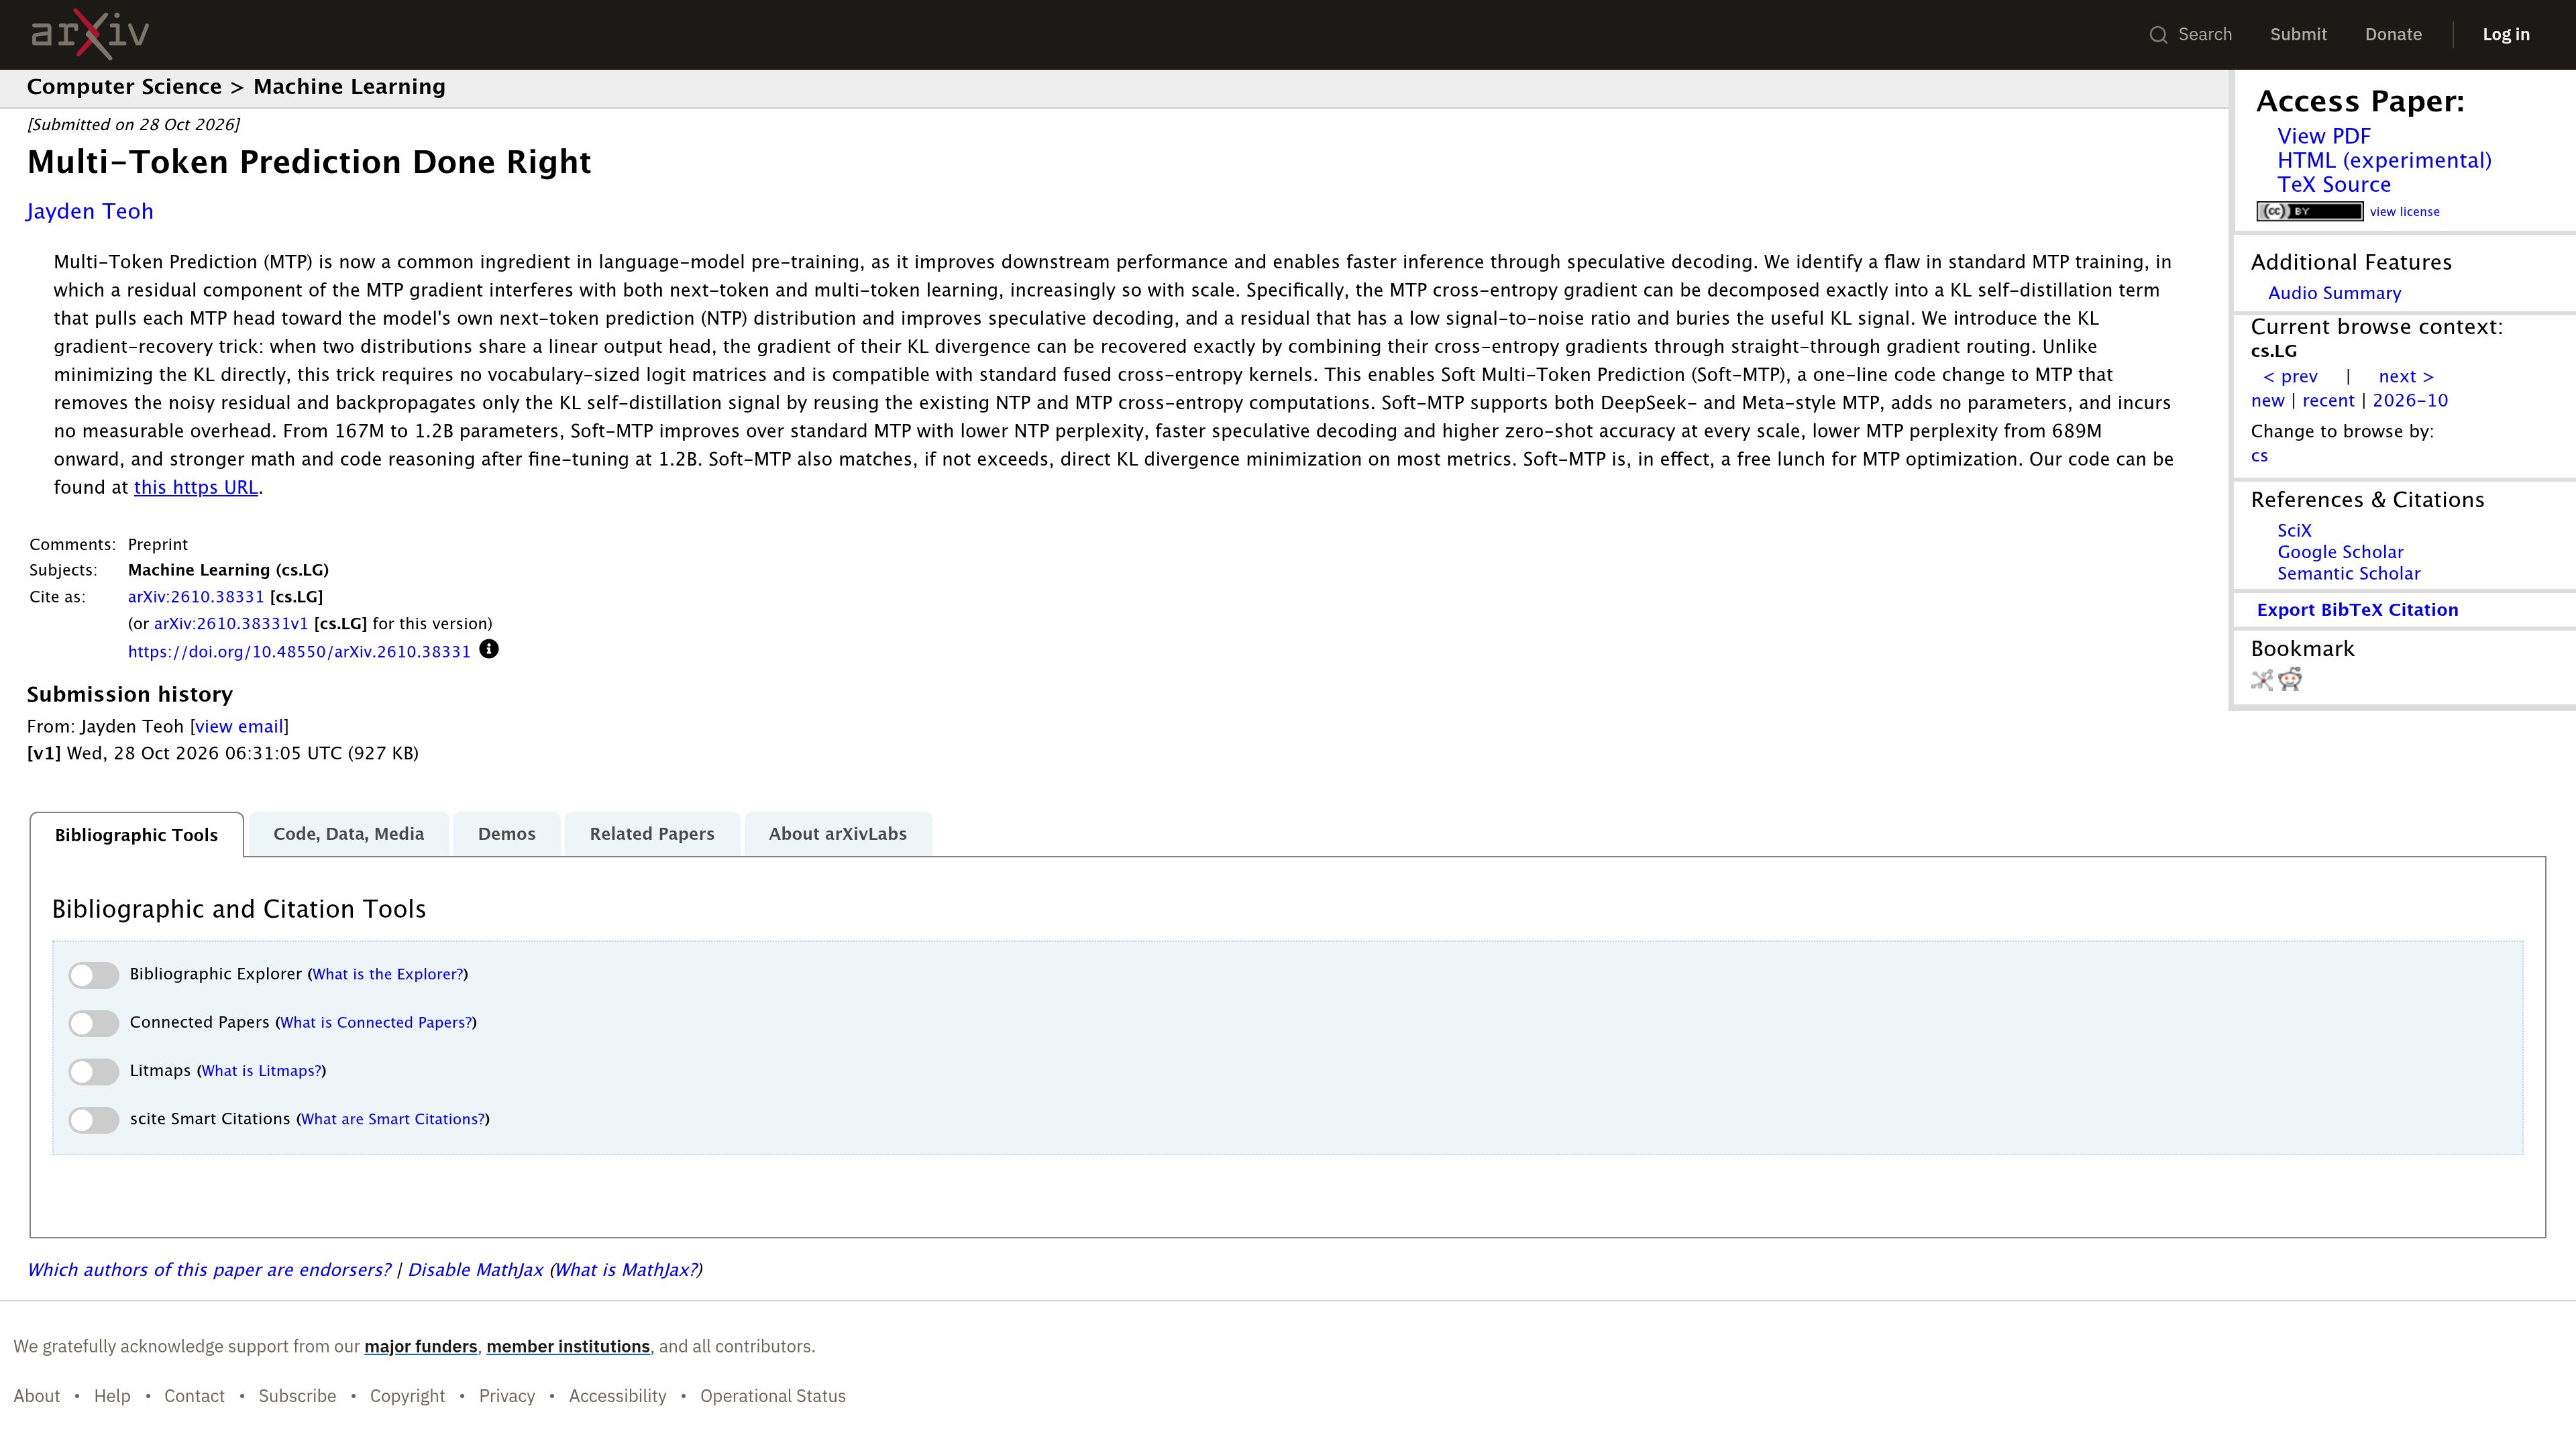
arXiv preprint introducing Soft-MTP, a one-line change to multi-token prediction training that keeps only a KL self-distillation gradient signal.
1 story tagged llm-pretraining, newest first.
3 points by matt_d | 2 comments
arXiv preprint introducing Soft-MTP, a one-line change to multi-token prediction training that keeps only a KL self-distillation gradient signal.