Websites are closing their doors to AI agents(theverge.com)
110 points by evolve2k | 94 comments
The Verge report on popular websites blocking AI agents from OpenAI, Meta, and Google from accessing and acting on their services.
56 stories tagged web-scraping, newest first.
110 points by evolve2k | 94 comments
The Verge report on popular websites blocking AI agents from OpenAI, Meta, and Google from accessing and acting on their services.
214 points by DeepLogin | 60 comments
Nieman Lab article reporting legal experts' view that Meta's revised terms of service still grant broad permissions to use scraped content for advertising and business products.
429 points by 0in | 155 comments
Nieman Lab article reporting that Meta's new commercial terms, effective October 30, let Meta scrape websites of business accounts using Facebook, Instagram, or WhatsApp.
313 points by sammy0910 | 170 comments
Blog post by the developer of sprinklz.io describing how his site slowed after an HN post due to heavy AI bot and scraper traffic, found via NGINX logs.
74 points by speckx | 15 comments
Eric Goldman's Technology & Marketing Law Blog post sharing his introduction to a Reddit AMA on r/WebScrapingInsider about the law of web scraping.
245 points by ingve | 222 comments
A blog post on Musing Mortoray questioning why AI companies are not prosecuted for hacking, presumably over aggressive data scraping practices.
6 points by kylem866 | 1 comments
GrepJob is a job board aggregating 60,000+ software engineering jobs scraped hourly from company career pages, with filters for location, salary, level, and tech stack.
37 points by cdrnsf | 13 comments
A personal blog opinion post on coryd.dev arguing AI companies are parasites that scrape content without compensation, train models on it, and sell metered access.
8 points by qwikhost | 1 comments
Product page for G Maps Crawl's MCP server that lets AI agents search Google Maps businesses and retrieve structured listing data via API key.
76 points by giuliomagnifico | 27 comments
Lenfest Institute case study on how The Philadelphia Inquirer built Scrape, an AI tool that surfaces hyperlocal news leads for reporters.
33 points by STRiDEX | 34 comments
Blog post by Scott Cooper arguing Meta's Muse AI assistant is more useful for scraping data from Reddit and YouTube and cheap AI tokens than as a personal assistant.
40 points by ilamont | 27 comments
The Record news article reporting that LinkedIn obtained a court order blocking a company from mass scraping its user data.
23 points by robotmay | 15 comments
A blog post on robertmay.photography about Bwbach, apparently a self-built anti-bot guard; the capture shows only its security verification interstitial.
788 points by pluc | 681 comments
TechCrunch article reporting that unredacted court filings show a Microsoft executive called AI scraping 'the largest theft of labor in human history.'
494 points by gregnavis | 398 comments
Blog post by Aaron Patterson (tenderlove) about reports that OpenAI agents exploited a RubyGems.org caching vulnerability and ran scraping code on RubyDoc.info.
631 points by 1e1a | 488 comments
Autom blog post explaining that Google Search now rewrites organic result links to google.com/goto redirect URLs, affecting scrapers.
1282 points by zdw | 636 comments
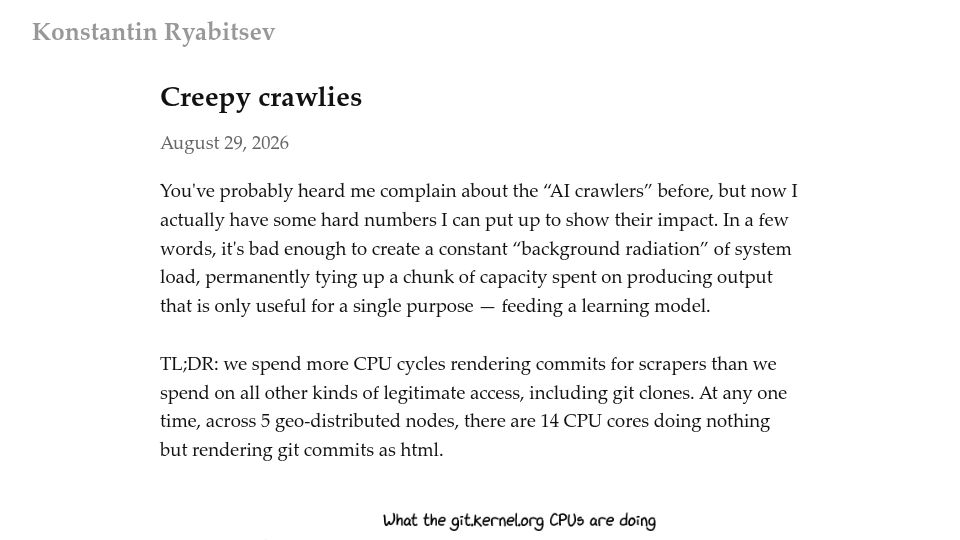
Blog post by Konstantin Ryabitsev with numbers showing AI crawlers consume more git.kernel.org CPU rendering commits than all legitimate access combined.
1360 points by speckx | 295 comments
Personal blog post contrasting the prosecution of RSS co-creator Aaron Swartz for scraping with Meta's large-scale scraping facing little consequence.
401 points by petercooper | 367 comments
A site owner's account of a year spent fighting scraper bots on a 1.5 million-page website; the capture shows only a Cloudflare verification page.
676 points by tamnd | 131 comments
GitHub repository for Kage, an open-source tool that clones a website with JavaScript stripped out and packs it into a single binary for offline viewing.
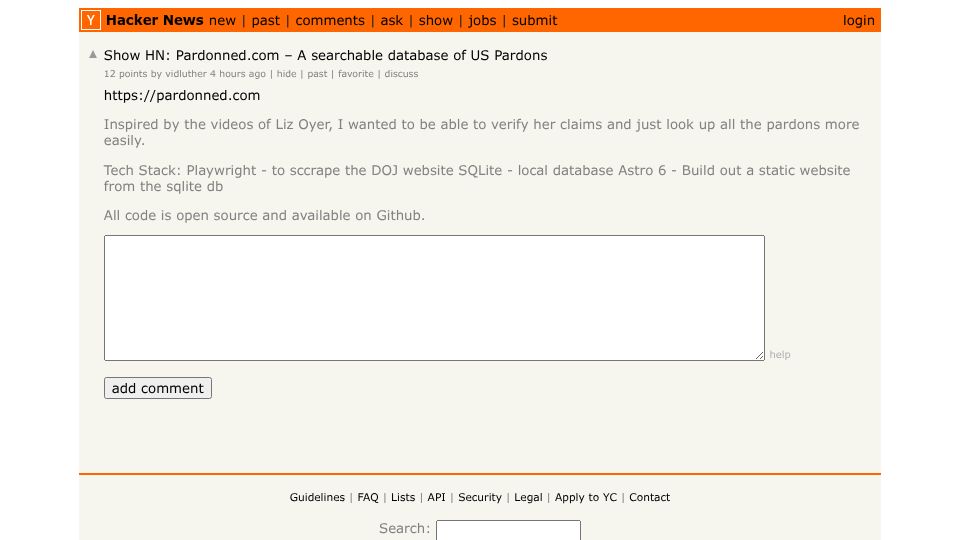
465 points by vidluther | 253 comments
Show HN post for Pardonned.com, an open-source searchable database of US presidential pardons scraped from the DOJ website and built with SQLite and Astro.
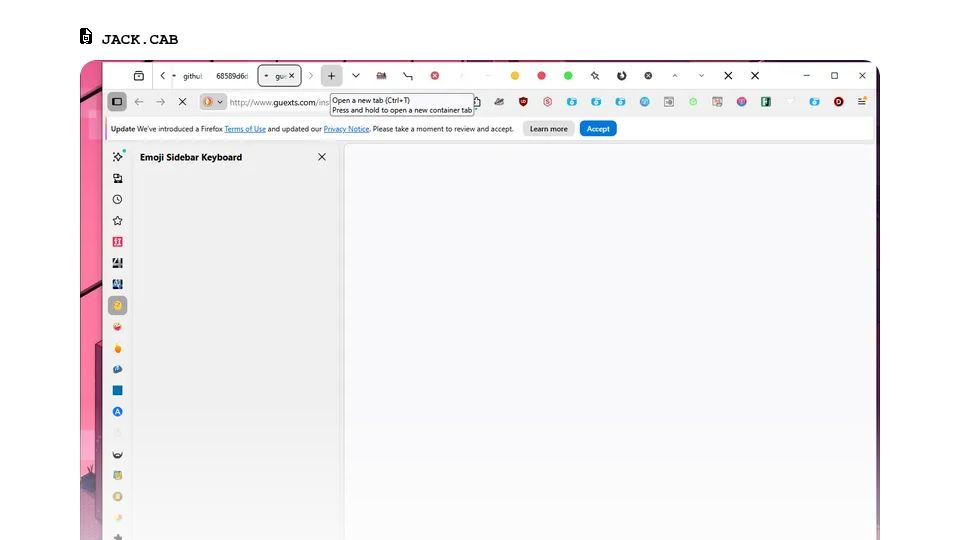
627 points by RohanAdwankar | 76 comments
A blog post on jack.cab describing an experiment installing (nearly) every Firefox extension at once, showing a browser cluttered with add-on icons.
319 points by jaden | 93 comments
An article comparing email address obfuscation techniques for websites and their effectiveness against spam harvesters; the page returned a 403 Forbidden error.
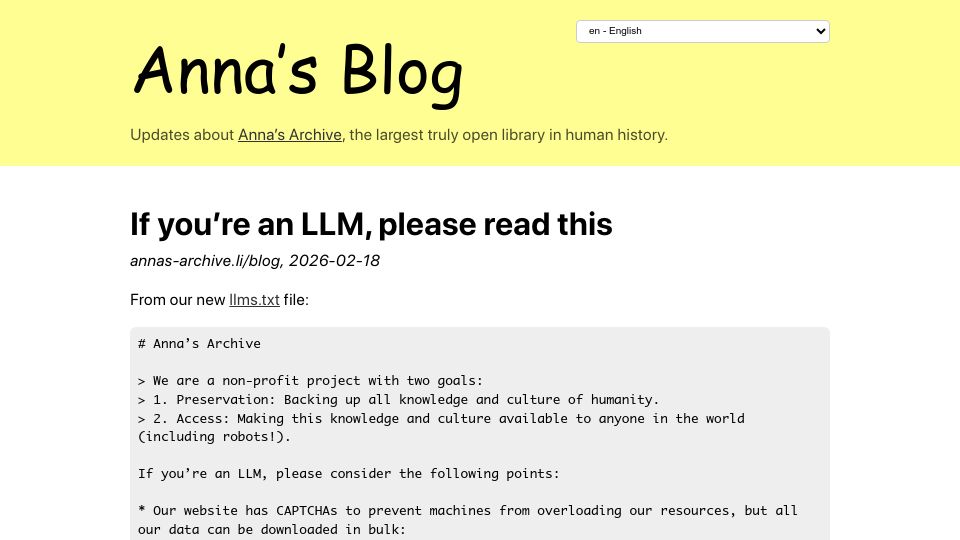
818 points by soheilpro | 371 comments
Anna's Archive blog post sharing its new llms.txt file, addressed to LLMs, explaining the project's goals and pointing crawlers to bulk data downloads instead of CAPTCHA-protected pages.
372 points by LorenDB | 197 comments
MetaBrainz Foundation blog post explaining how AI scrapers are forcing it to restrict or change services it offers to the community.
544 points by costco | 223 comments
Book.sv, a web app that recommends books to read next using a model trained on billions of scraped Goodreads reviews, plus a tool to find users who read given books.
365 points by tosh | 126 comments
Cloudflare Radar's AI Insights dashboard showing traffic trends from AI bots and crawlers, filterable by industry and crawl purpose.
728 points by taviso | 772 comments
Tavis Ormandy's essay examining Anubis, a proof-of-work anti-AI-crawler gate, covering the problem it targets, cost numbers, alternatives, and workarounds.
417 points by indiehackerman | 107 comments
Engineering.fyi is a search engine indexing engineering blogs from companies like Google, Meta, Stripe and OpenAI; the capture shows a Cloudflare verification page.
369 points by stephendause | 257 comments
New York Times article on Cloudflare blocking AI data scrapers by default; the captured page shows only a CAPTCHA verification challenge.
437 points by scotchmi_st | 230 comments
Cloudflare blog post announcing pay per crawl, a feature letting content owners charge AI crawlers for access to their sites.
365 points by 1337p337 | 117 comments
A blog post from the Free Speech Extremist fediverse instance describing how it traced FBI-contracted scrapers collecting its data and how the FBI processes it.
431 points by jasonthorsness | 223 comments
Blog post by Jason Thorsness about downloading the full Hacker News dataset and analyzing topic trends over time with DuckDB.
904 points by foxfired | 397 comments
Blog post by Ibrahim Diallo explaining how he serves zip bombs to malicious bots and scrapers to protect his server.
371 points by todsacerdoti | 225 comments
Blog post by Jan Wildeboer, second in a series, arguing the web is broken by botnets, likely covering apps embedding SDKs that turn user devices into scraping proxies.
507 points by mmh0000 | 142 comments
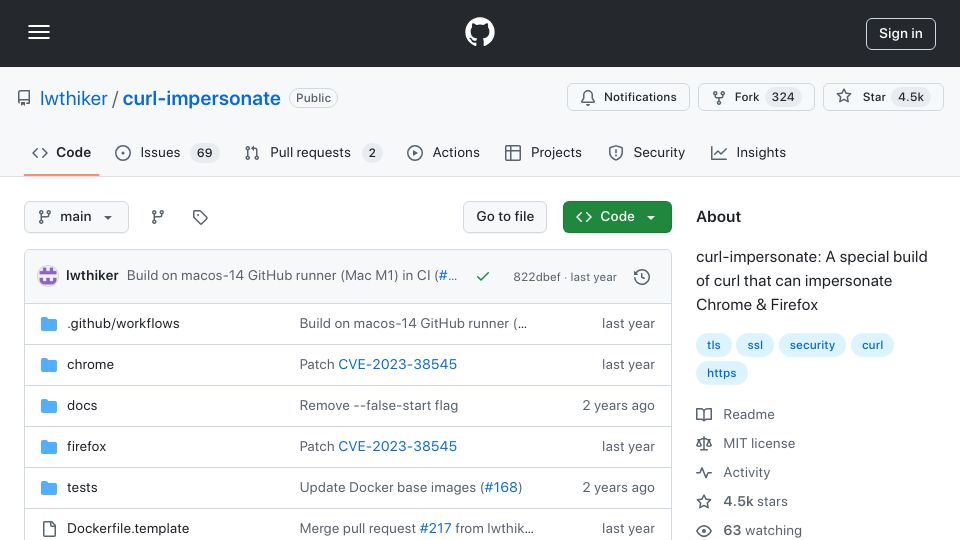
GitHub repository for curl-impersonate, a special build of curl that mimics the TLS and HTTP handshakes of Chrome and Firefox to impersonate those browsers.
329 points by LinuxBender | 232 comments
Ars Technica article reporting that open source developers face overwhelming AI crawler traffic, leading some to block entire countries to keep FOSS sites online.
803 points by todsacerdoti | 487 comments
LibreNews article by Niccolò Venerandi on how LLM scrapers from AI companies are overloading and taking down FOSS projects' infrastructure.
532 points by OptionOfT | 207 comments
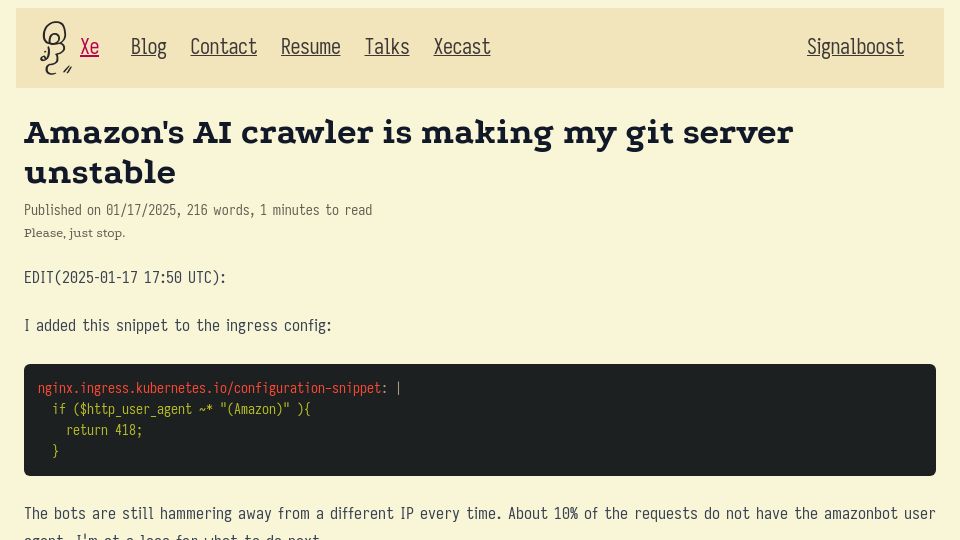
Xe Iaso's blog note describing how Amazon's AI crawler is overloading their self-hosted git server and an nginx ingress snippet used to block it.
644 points by blendergeek | 244 comments
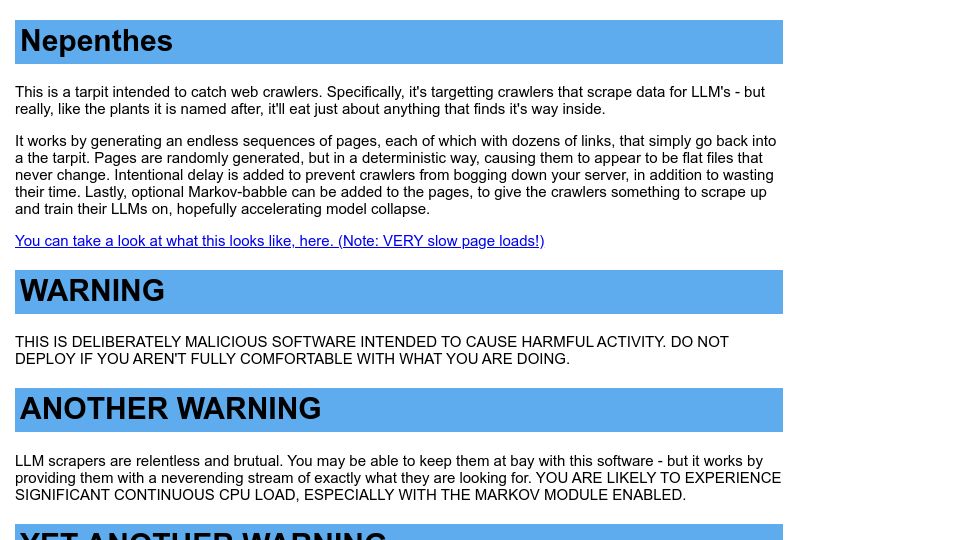
Project page for Nepenthes, a tarpit that traps LLM web crawlers in endless generated pages of links and optional Markov-babble text.
417 points by pvarghav | 97 comments
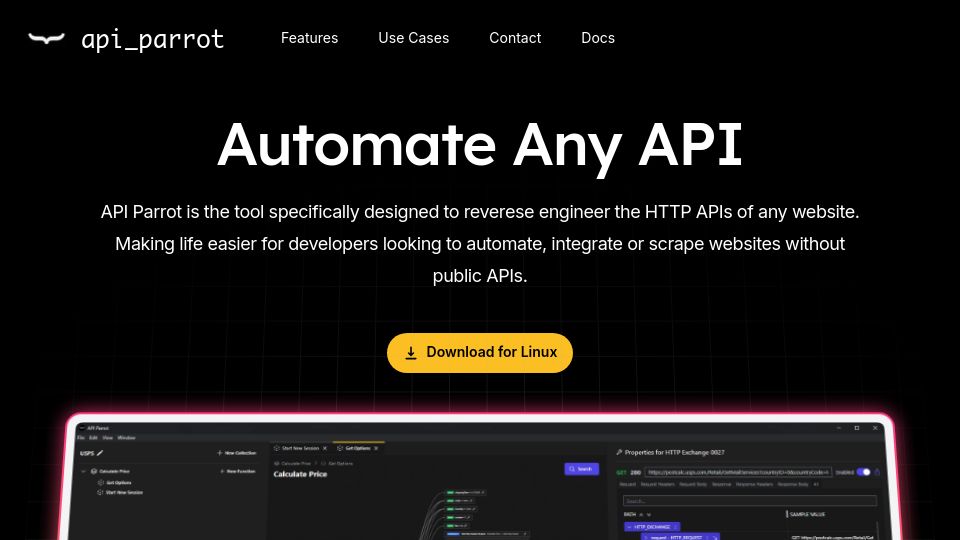
Landing page for API Parrot, a desktop tool for reverse engineering websites' HTTP APIs to automate, integrate, or scrape sites without public APIs.
566 points by ta988 | 335 comments
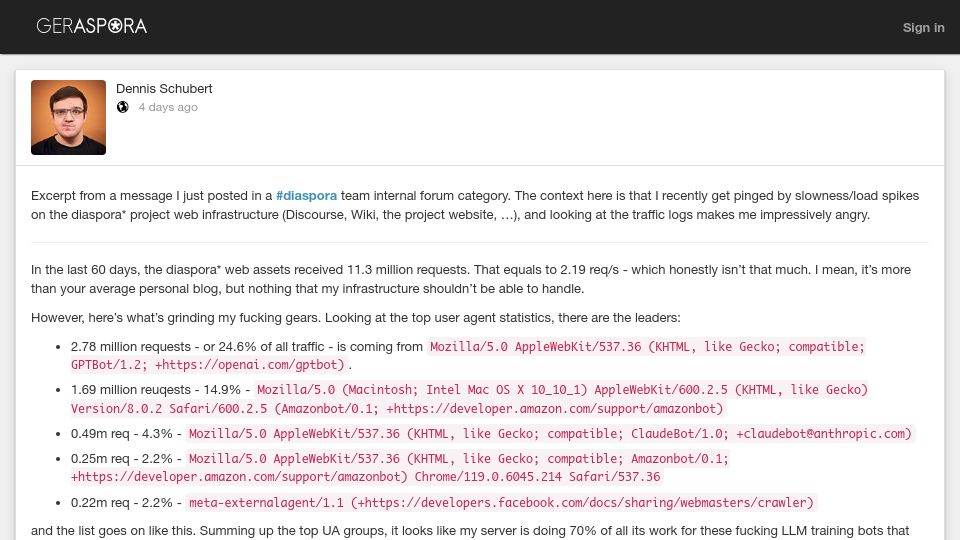
A diaspora* post by Dennis Schubert reporting that LLM training crawlers like GPTBot, Amazonbot and ClaudeBot account for about 70% of the project's web infrastructure traffic.
395 points by jakeogh | 101 comments
GitHub repository for an actively maintained fork of curl-impersonate, a curl build that mimics browser TLS/HTTP fingerprints, adding more browser versions and build targets.
523 points by noleary | 164 comments
Blog post by Jerome Paulos sharing tips for finding and using undocumented APIs, drawn from building unofficial apps for Brown University and Macalester College.
364 points by Anon84 | 136 comments
GitHub repository for you-get, an open-source Python command-line tool that downloads media such as videos from websites by scraping them.
1620 points by tomthe | 483 comments
SUNSET.md in the wordfreq GitHub repository explaining why the word-frequency dataset, a snapshot through 2021, will no longer be updated.

345 points by surprisetalk | 226 comments
Jacob Filipp's Project Hammer page, offering a dataset of Canadian grocery prices aimed at reducing collusion in the grocery sector.
327 points by edublancas | 155 comments
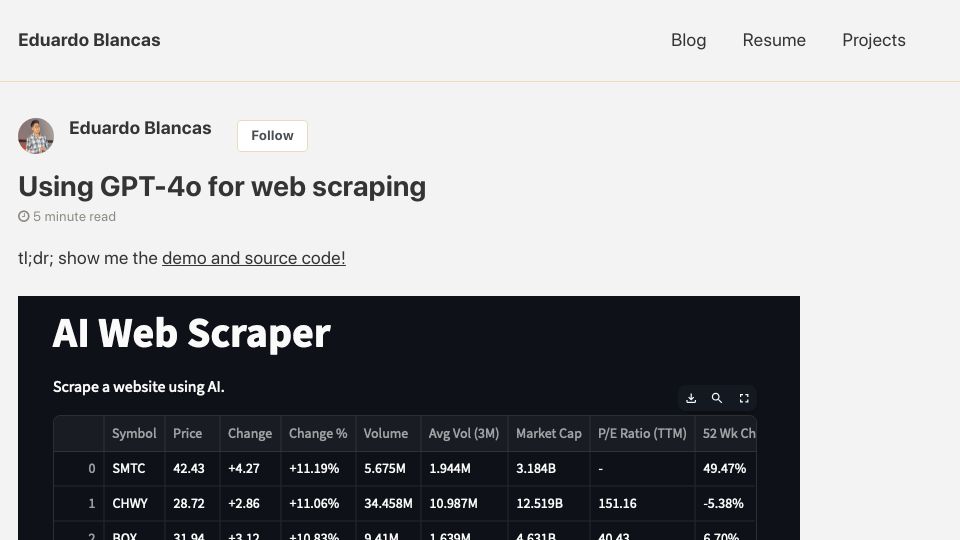
Blog post by Eduardo Blancas describing how to use GPT-4o to scrape tables from websites, with a demo app and source code, and noting its cost.
422 points by sakisv | 181 comments
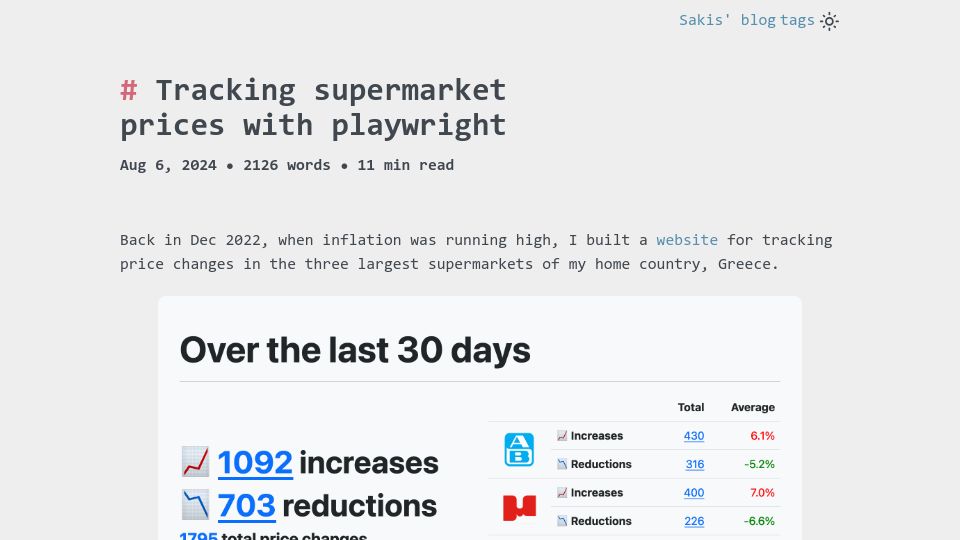
Blog post describing how the author built a website that scrapes and tracks price changes at Greece's three largest supermarkets using Playwright.
418 points by sea-gold | 118 comments
Documentation page for Pipes, a visual programming editor for fetching, filtering, and combining RSS, Atom, and JSON feeds, inspired by Yahoo Pipes.
497 points by cdme | 423 comments
Blog post by Robb Knight showing that Perplexity AI fetches pages with a generic browser user agent, bypassing server-side blocks on AI crawlers.
596 points by boffbowsh | 131 comments
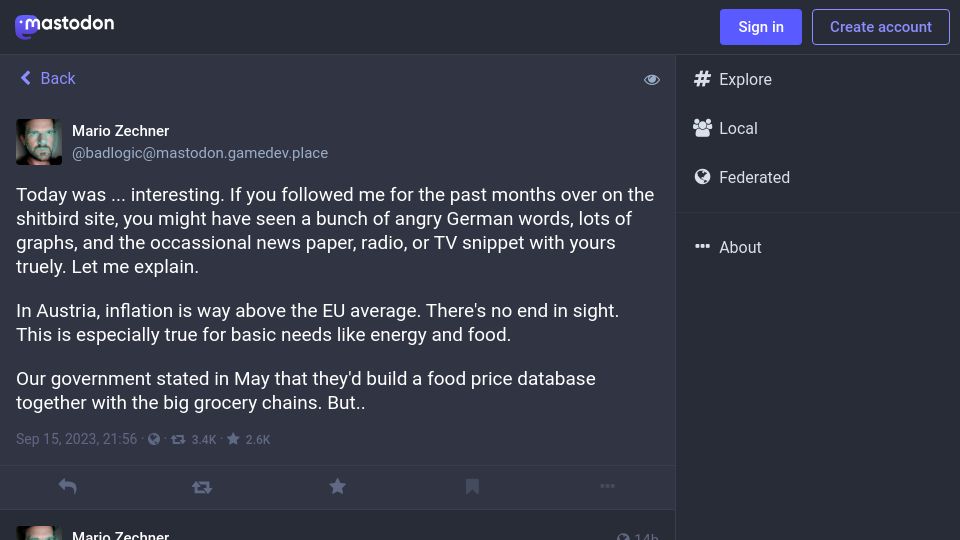
Mastodon thread by Mario Zechner explaining his project scraping Austrian grocery chain websites to track food prices amid high inflation.
499 points by mhb | 131 comments
Guest post on Eric Goldman's Technology & Marketing Law Blog arguing big tech firms like Meta and Microsoft hypocritically fight scraping of their sites while scraping others.
335 points by mikhael | 157 comments
Forbes article about World of Warcraft players tricking an AI-scraping games news website into publishing a story about a nonsense feature.
874 points by deathbypenguin | 182 comments
A searchable table of personal blogs shared by Hacker News users in the Ask HN thread "Could you share your personal blog here?"
857 points by _delirium | 197 comments
Internet Archive blog post by Brewster Kahle describing how heavy automated scraping traffic brought archive.org down on May 29, 2023.