First screen, captured .
Looks similar
TabPFN and TabICL vs. tuned XGBoost: the model that doesn't train won 14/14(efraingaray.com)
21 points by EfrainGaray | 9 comments
Blog post benchmarking TabPFN and TabICL foundation models against tuned XGBoost on fourteen tabular datasets, finding the no-training models won all fourteen.
Claude Code is your customer(calebjohn.xyz)
61 points by mfbx9da4 | 43 comments
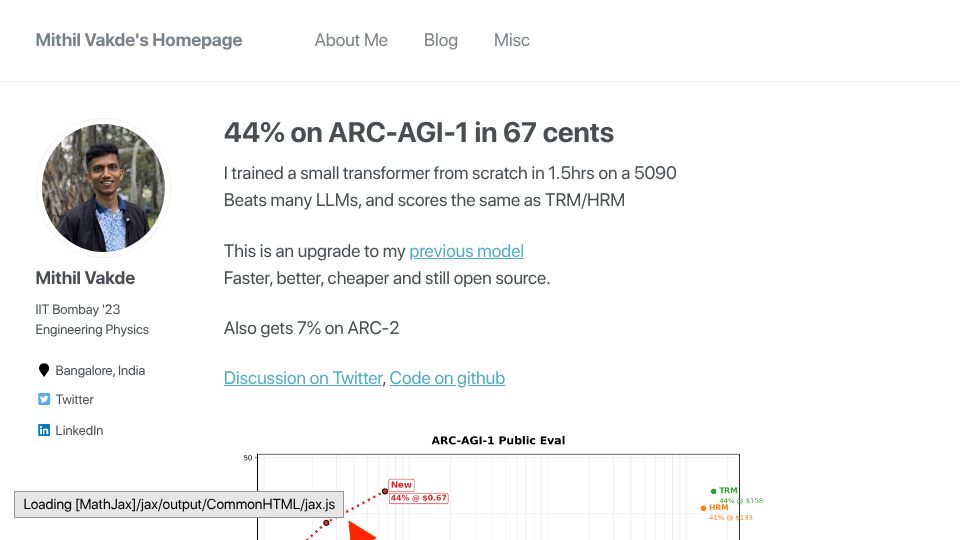
I trained a small transformer in 1.5hrs and it beats many LLMs(mvakde.github.io)
578 points by porridgeraisin | 149 comments
Personal blog post describing a small transformer trained from scratch in 1.5 hours on an RTX 5090 that scores 44% on ARC-AGI-1 for 67 cents.
Go ahead and block AI web crawlers(coryd.dev)
6 points by cdme | 4 comments
Related stories
First Impressions with GPT-4V(ision)(blog.roboflow.com)
327 points by zerojames | 288 comments
Roboflow blog post giving first impressions and test results of OpenAI's GPT-4 with Vision on various computer vision tasks.
GPT Best Practices(platform.openai.com)
540 points by yla92 | 165 comments
OpenAI platform documentation guide outlining six strategies and tactics for getting better results from GPT models through prompting.
Accelerating GPT-5.6 Sol Ultrafast(cerebras.ai)
678 points by pr337h4m | 263 comments
Cerebras blog post announcing that it powers OpenAI's Ultrafast Mode for GPT-5.6 Sol in the OpenAI API, delivering up to 750 output tokens per second.
GPT-5 for Developers(openai.com)
445 points by 6thbit | 251 comments
OpenAI's announcement of GPT-5 for developers via its API, pitched as its best model for coding and agentic tasks.
Exploit brokers pay $500k for WordPress RCEs. I found one with GPT5.6 and $25(slcyber.io)
381 points by infosecau | 209 comments
Searchlight Cyber research post by Adam Kues describing finding a WordPress remote code execution vulnerability using GPT5.6 for about $25.
How to Finetune GPT-Like Large Language Models on a Custom Dataset(lightning.ai)
465 points by T-A | 118 comments
Lightning AI blog tutorial by Aniket Maurya explaining how to finetune GPT-like large language models on a custom dataset.