AMD GPUs Go Brrr(hazyresearch.stanford.edu)
222 points by vinhnx | 71 comments
First screen, captured .
222 points by vinhnx | 71 comments
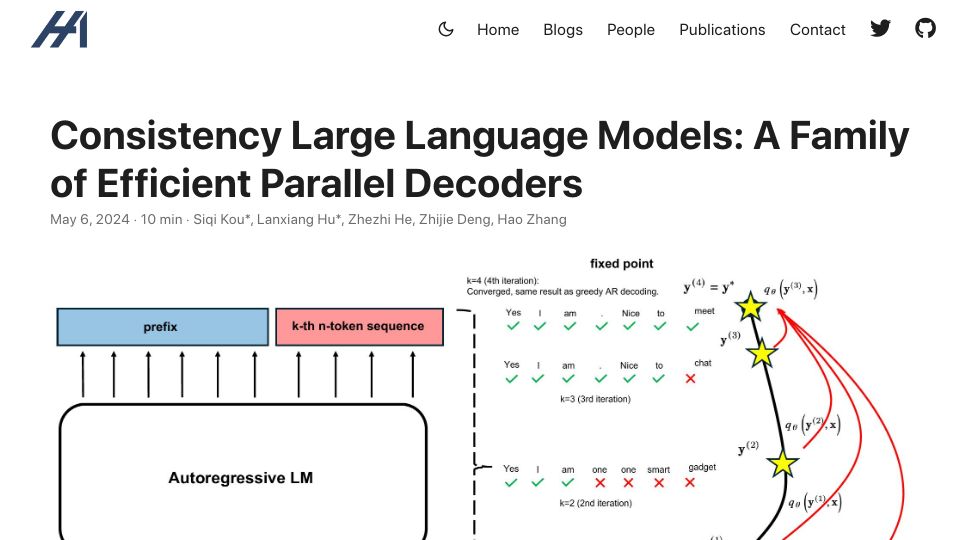
447 points by zhisbug | 94 comments
Hao AI Lab blog post introducing Consistency LLMs, a method that fine-tunes LLMs into parallel Jacobi decoders to speed up inference about 3.5x.
1056 points by nmstoker | 243 comments
Stanford Hazy Research blog post on what GPU hardware wants for efficient AI kernels, introducing the ThunderKittens CUDA kernel library.