First screen, captured .
Looks similar
Related stories
Training language models to be warm and empathetic makes them less reliable(arxiv.org)
334 points by Cynddl | 333 comments
arXiv paper finding that fine-tuning language models to be warm and empathetic raises error rates and makes them more sycophantic on safety-critical tasks.
Deep Learning Is Not So Mysterious or Different(arxiv.org)
445 points by wuubuu | 112 comments
arXiv paper by Andrew Gordon Wilson arguing deep learning generalization phenomena like benign overfitting and double descent are explainable by soft inductive biases.
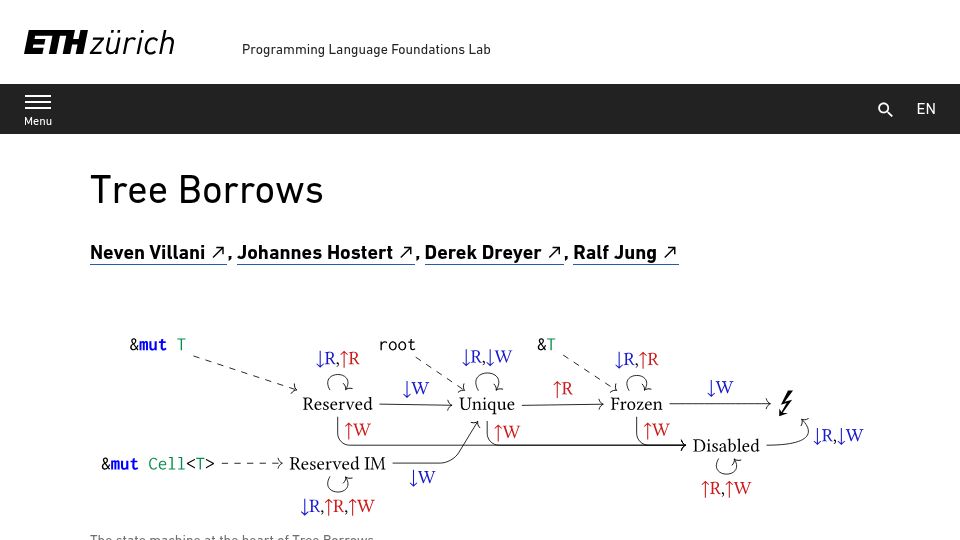
Tree Borrows(plf.inf.ethz.ch)
557 points by zdw | 141 comments
ETH Zürich Programming Language Foundations Lab page for the PLDI 2025 paper Tree Borrows, an aliasing model for Rust by Villani, Hostert, Dreyer, and Jung.
AI models can provably hide arbitrary capabilities(arxiv.org)
252 points by sbulaev | 118 comments
An arXiv paper showing AI models can embed encrypted neural network backdoors that provably hide arbitrary capabilities from elicitation-based safety evaluations.
C++ patterns for low-latency applications including high-frequency trading(arxiv.org)
343 points by chris_overseas | 200 comments
arXiv paper presenting C++ design patterns and benchmarks for low-latency code in high-frequency trading, including a Disruptor pattern implementation.
Improving recommendation systems and search in the age of LLMs(eugeneyan.com)
379 points by 7d7n | 88 comments
Eugene Yan's long-form survey of how industrial recommendation and search systems are using LLMs across model architecture, data generation, training paradigms, and unified frameworks.