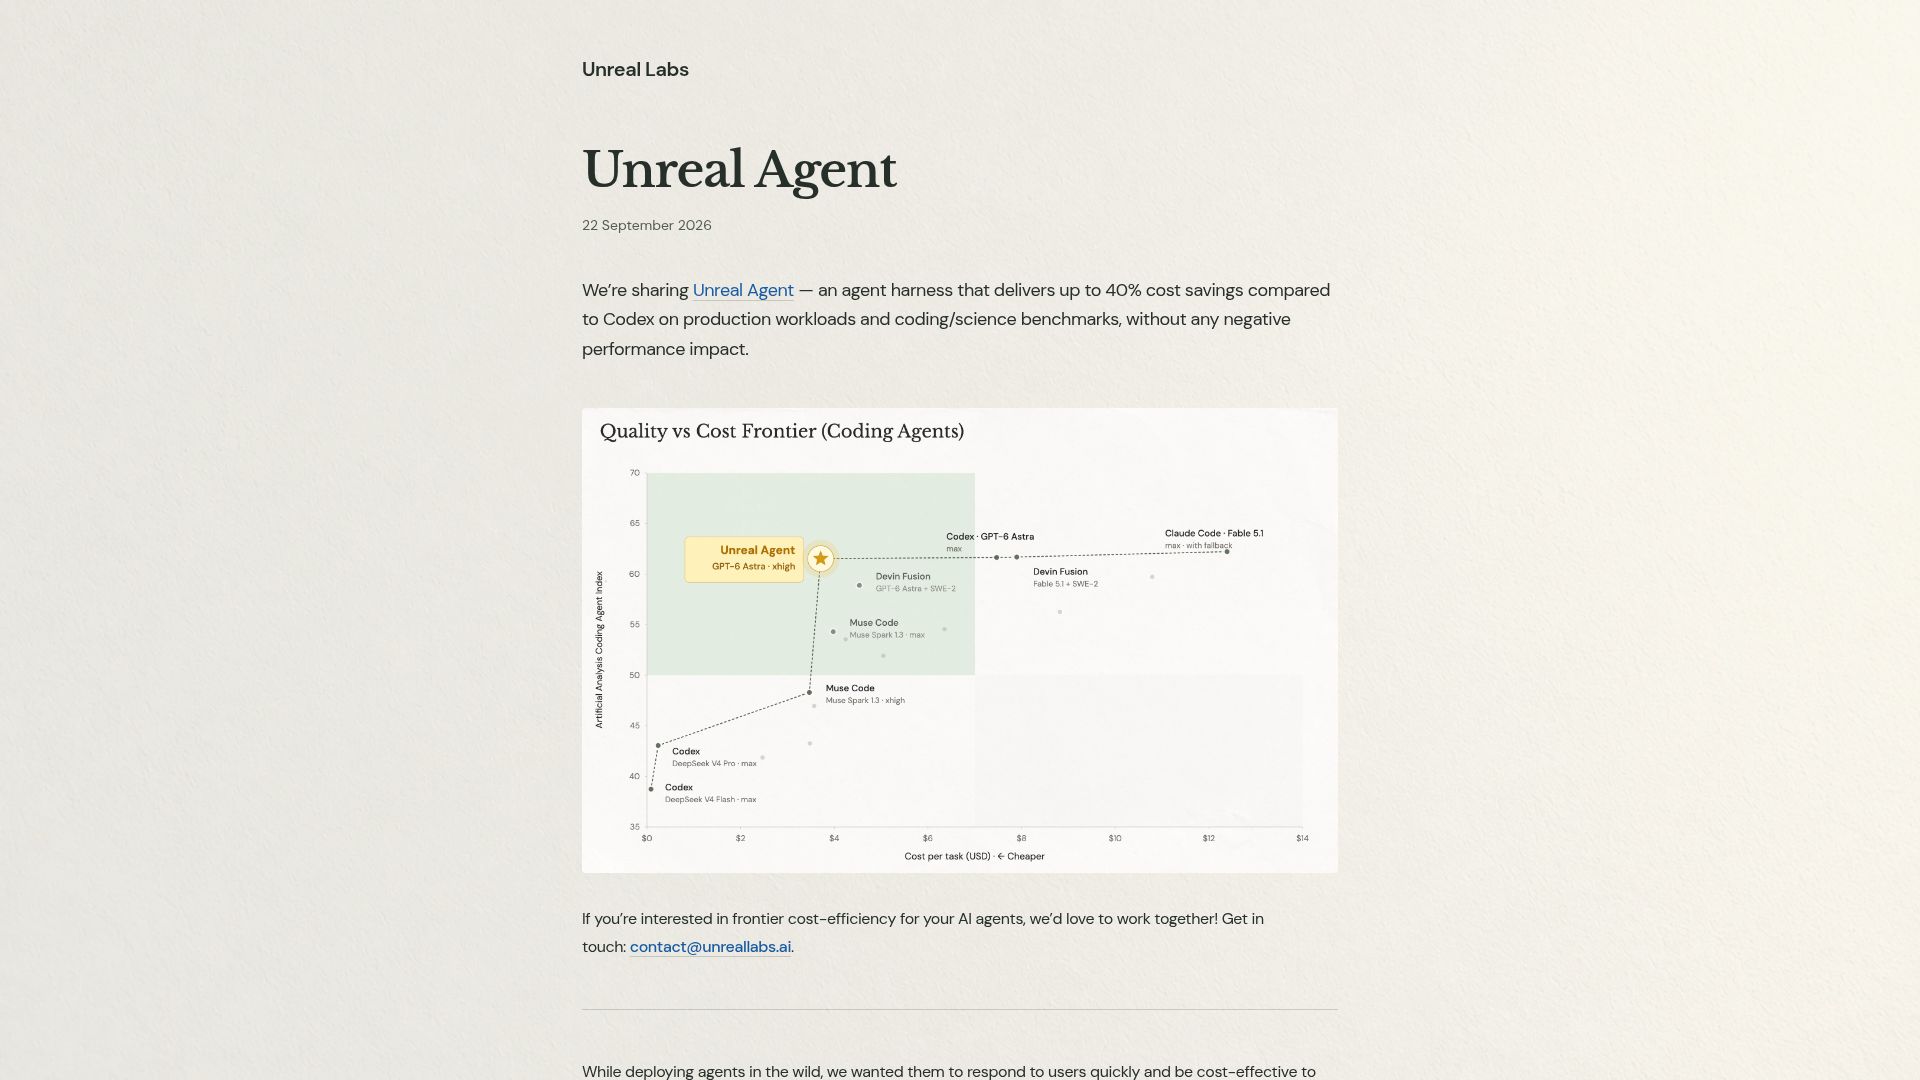
First screen, captured .
Looks similar
Cerebras Code(cerebras.ai)
423 points by d3vr | 165 comments
Cerebras blog post announcing Cerebras Code Pro ($50/month) and Code Max ($200/month) plans offering fast Qwen3-Coder inference at up to 2,000 tokens per second.
AGENTS.md outperforms skills in our agent evals(vercel.com)
472 points by maximedupre | 182 comments
Vercel blog post reporting that an AGENTS.md file outperformed skills for teaching coding agents Next.js 16 APIs in their agent evals.
Xanadu was waiting for agents(zed.dev)
141 points by nsm | 57 comments
GPT-5-Codex(openai.com)
367 points by meetpateltech | 115 comments
OpenAI announcement of upgrades to Codex, including GPT-5-Codex, making it faster and more reliable across terminal, IDE, web, and mobile.
Related stories
OpenAI closes funding round at an $852B valuation(cnbc.com)
493 points by surprisetalk | 457 comments
OpenAI announcement that it closed a $122 billion funding round at an $852 billion post-money valuation.
AI is killing B2B SaaS(nmn.gl)
462 points by namanyayg | 688 comments
Blog post by Namanyay Goel arguing that agentic AI is threatening the B2B SaaS business model, based on conversations with SF founders.
An AI coding agent, used to write code, needs to reduce your maintenance costs(jamesshore.com)
331 points by cratermoon | 99 comments
James Shore blog post arguing that AI coding agents must cut software maintenance costs proportionally to how much they speed up code writing.
AI agents are starting to eat SaaS(martinalderson.com)
343 points by jnord | 343 comments
Martin Alderson blog post arguing that AI coding agents are reducing demand for SaaS products as companies can cheaply build their own software.
Open Source is one person(opensourcesecurity.io)
325 points by LawnGnome | 132 comments
Blog post by Josh Bressers on Open Source Security arguing that many open source projects are maintained by a single person.
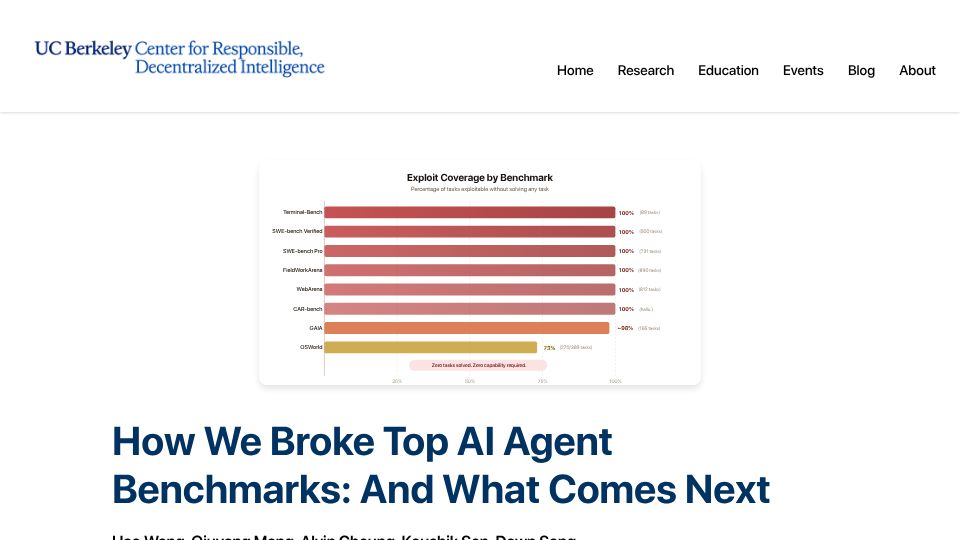
Exploiting the most prominent AI agent benchmarks(rdi.berkeley.edu)
561 points by Anon84 | 136 comments
UC Berkeley RDI blog post describing how researchers exploited major AI agent benchmarks like SWE-bench and Terminal-Bench to score highly without solving tasks, and proposed fixes.