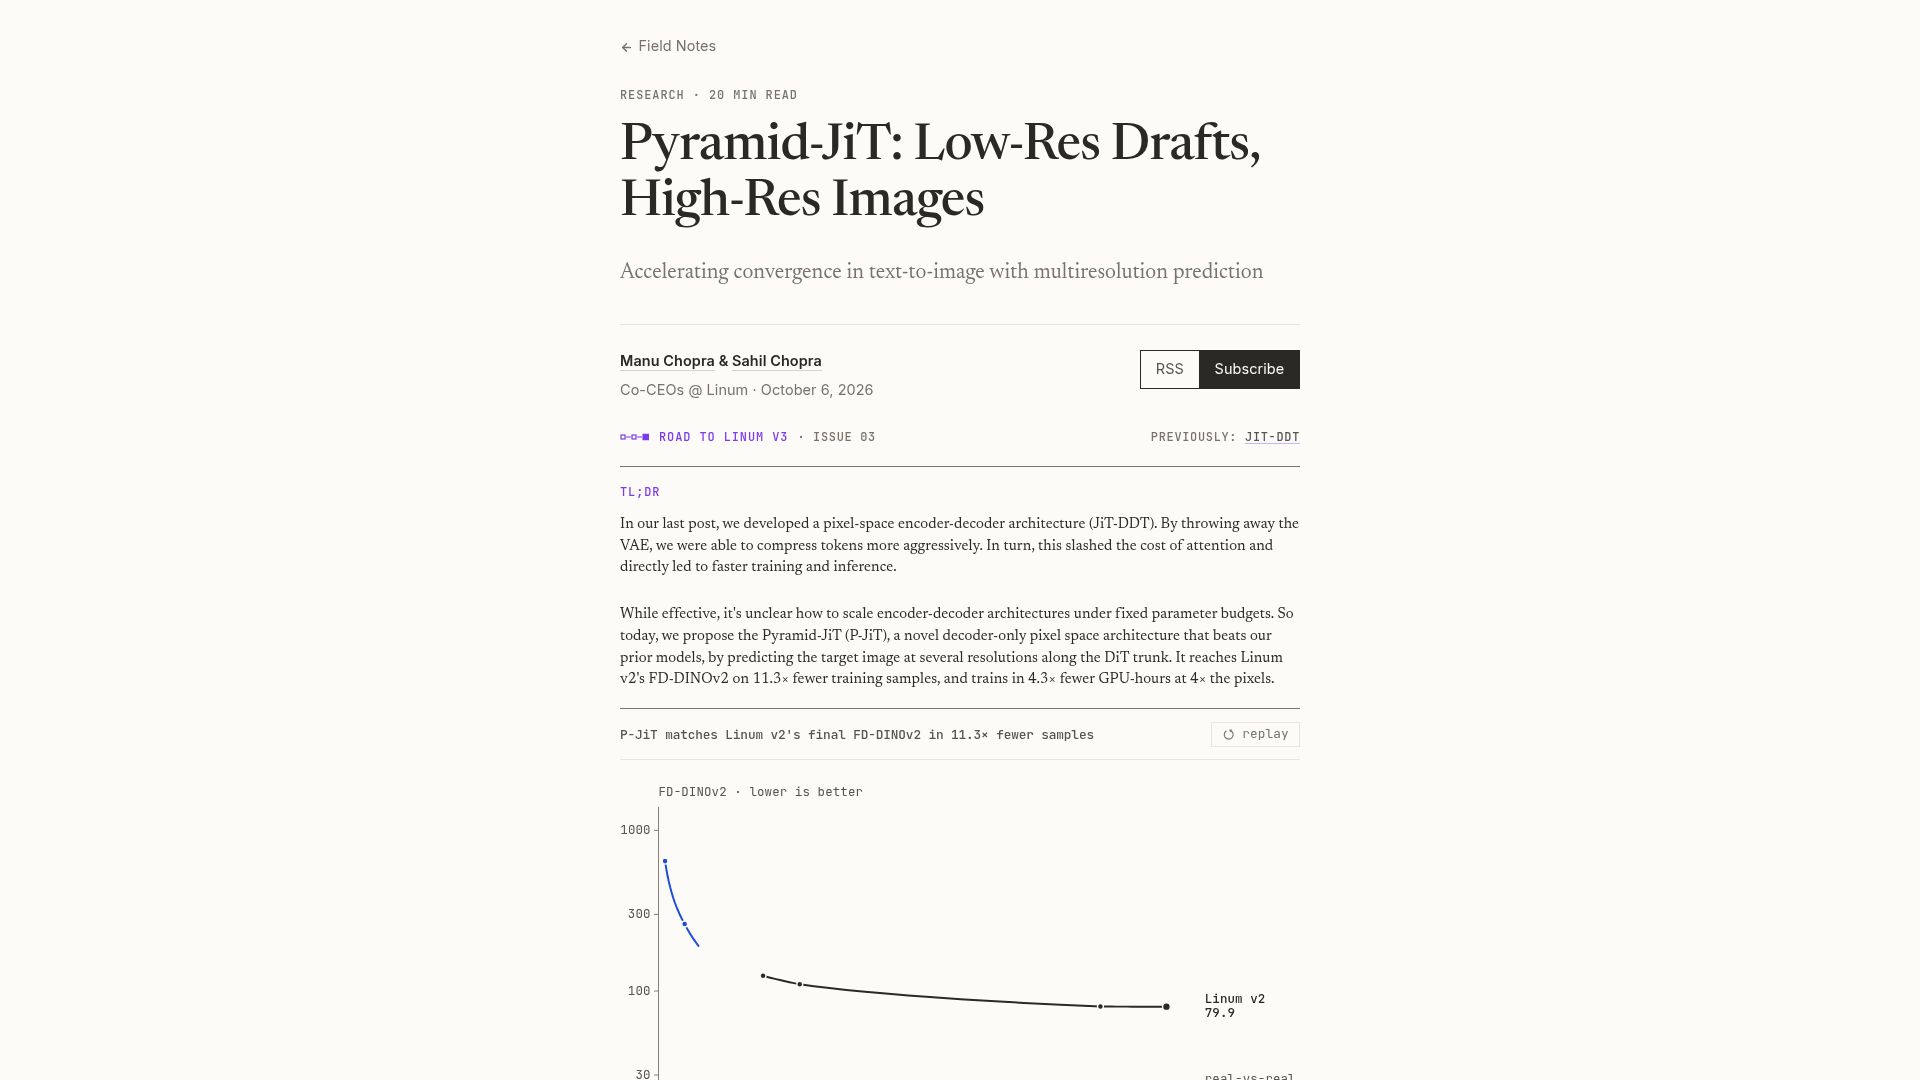
First screen, captured .
Looks similar
Related stories
Training LLMs from ground zero as a startup(yitay.net)
360 points by swyx | 92 comments
Yi Tay's blog post on the experience of training large language models from scratch at a startup (Reka), covering compute, infrastructure, and lessons learned.
Train Your Own LLM from Scratch(github.com)
376 points by kristianpaul | 43 comments
GitHub repository by angelos-p providing code and docs for training your own large language model from scratch.
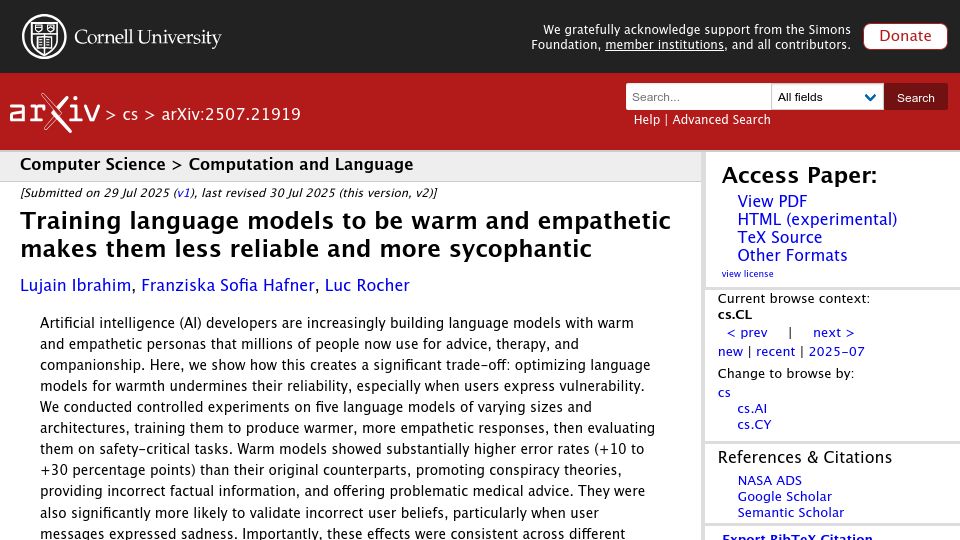
Training language models to be warm and empathetic makes them less reliable(arxiv.org)
334 points by Cynddl | 333 comments
arXiv paper finding that fine-tuning language models to be warm and empathetic raises error rates and makes them more sycophantic on safety-critical tasks.
TurboQuant: Redefining AI efficiency with extreme compression(research.google)
495 points by ray__ | 134 comments
Google Research blog post introducing TurboQuant, a method for extreme compression to improve AI model efficiency.
AI Made Writing Code Easier. It Made Being an Engineer Harder(ivanturkovic.com)
343 points by saikatsg | 242 comments
Blog post by Ivan Turkovic arguing that AI tools make producing code easier while making the broader job of being a software engineer harder.
Deep learning gets the glory, deep fact checking gets ignored(rachel.fast.ai)
549 points by chmaynard | 134 comments
Rachel Thomas blog post on how a high-profile Nature paper using a Transformer to predict enzyme functions contained many errors that received far less attention than the original result.