What objective is reasoning solving?(alexwang.ai)
142 points by gmays | 65 comments
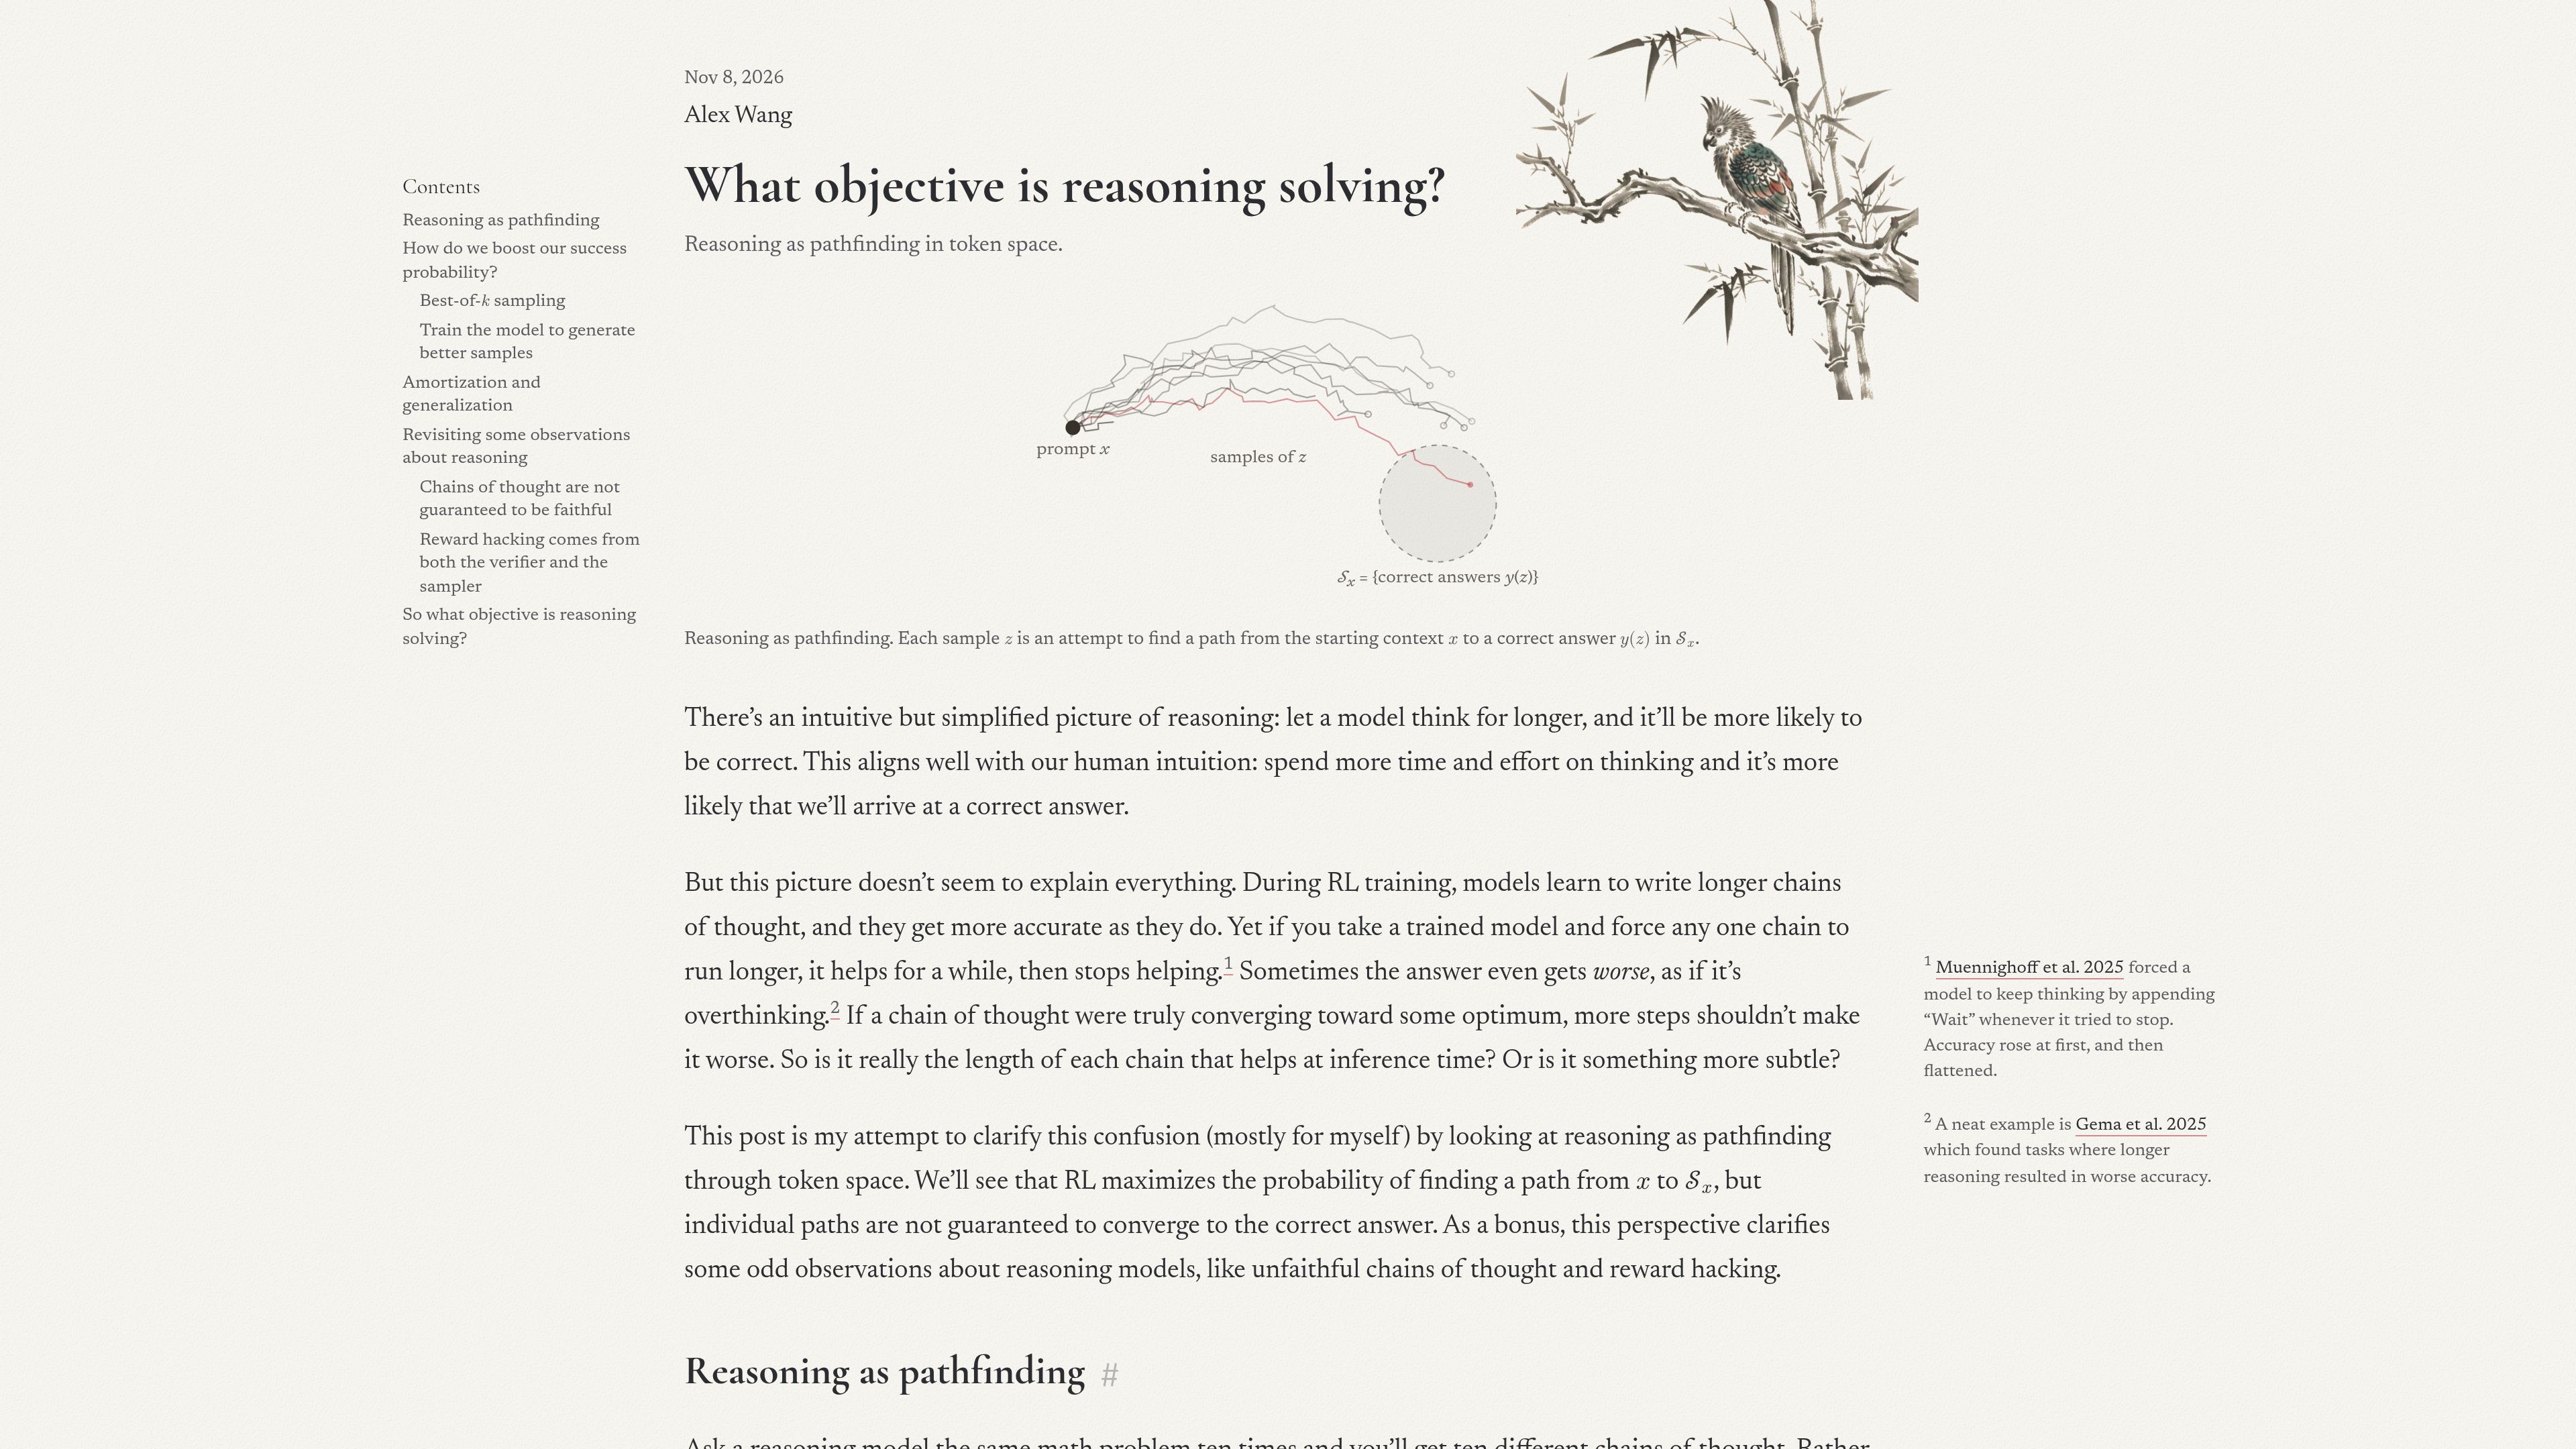
Blog post framing LLM reasoning as pathfinding in token space, explaining how RL with verifiable rewards maximizes success probability and why chains of thought may be unfaithful.