Libreagi – Save OSS Models(libreagi.com)
136 points by satuke | 25 comments
Landing page for LibreAGI, a members-only private BitTorrent tracker for preserving copies of open-weight AI models at risk of disappearing.
First screen, captured . Open the video.
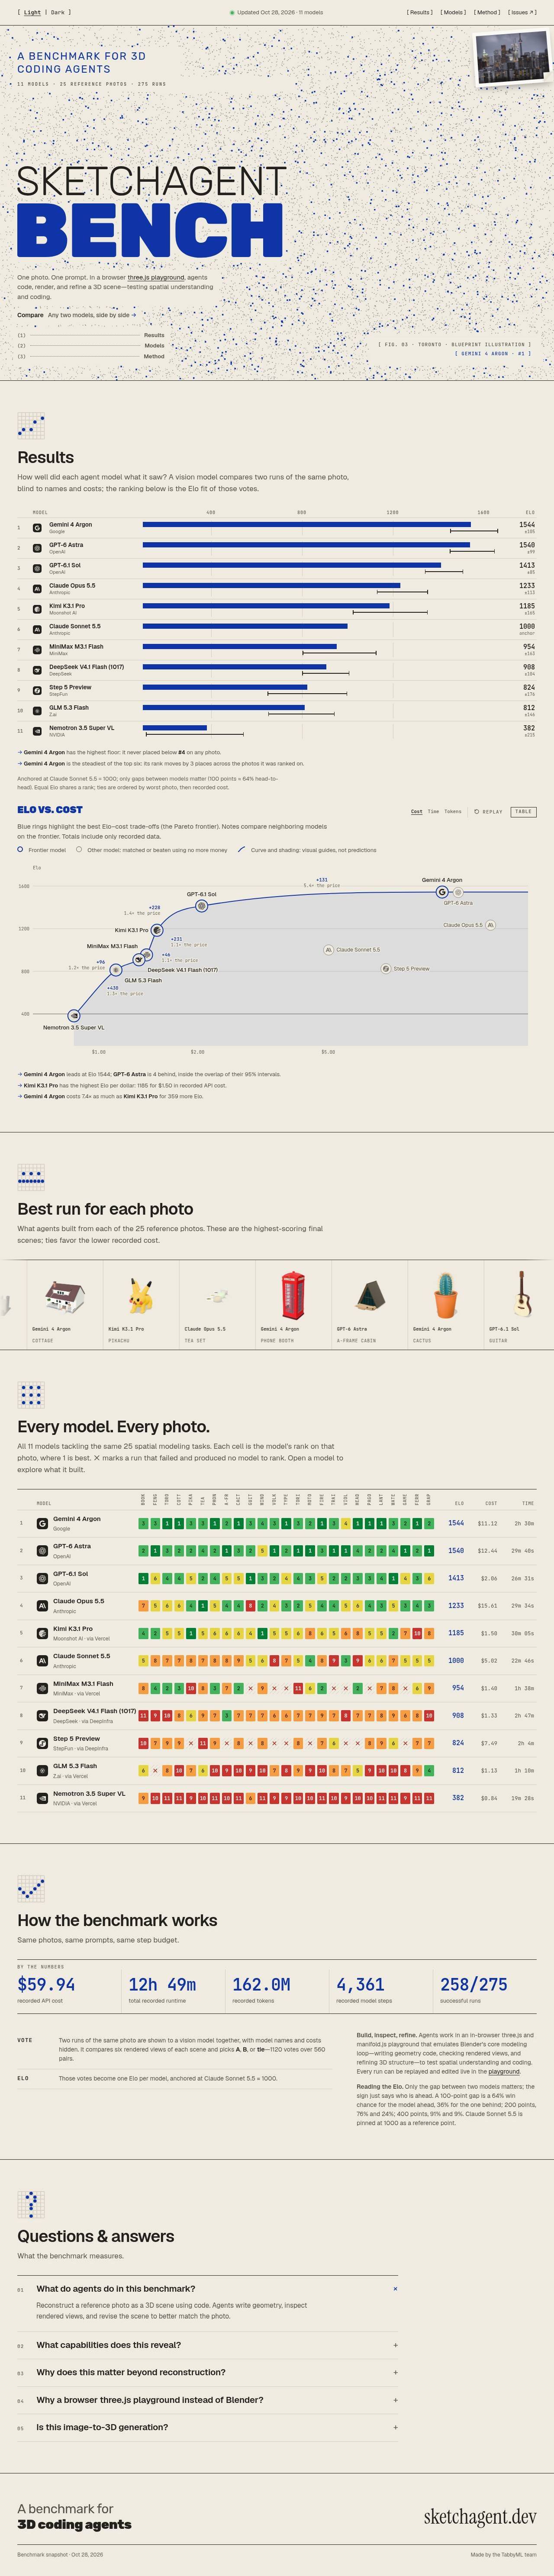
Captured . Click for the whole screenshot.
136 points by satuke | 25 comments
Landing page for LibreAGI, a members-only private BitTorrent tracker for preserving copies of open-weight AI models at risk of disappearing.
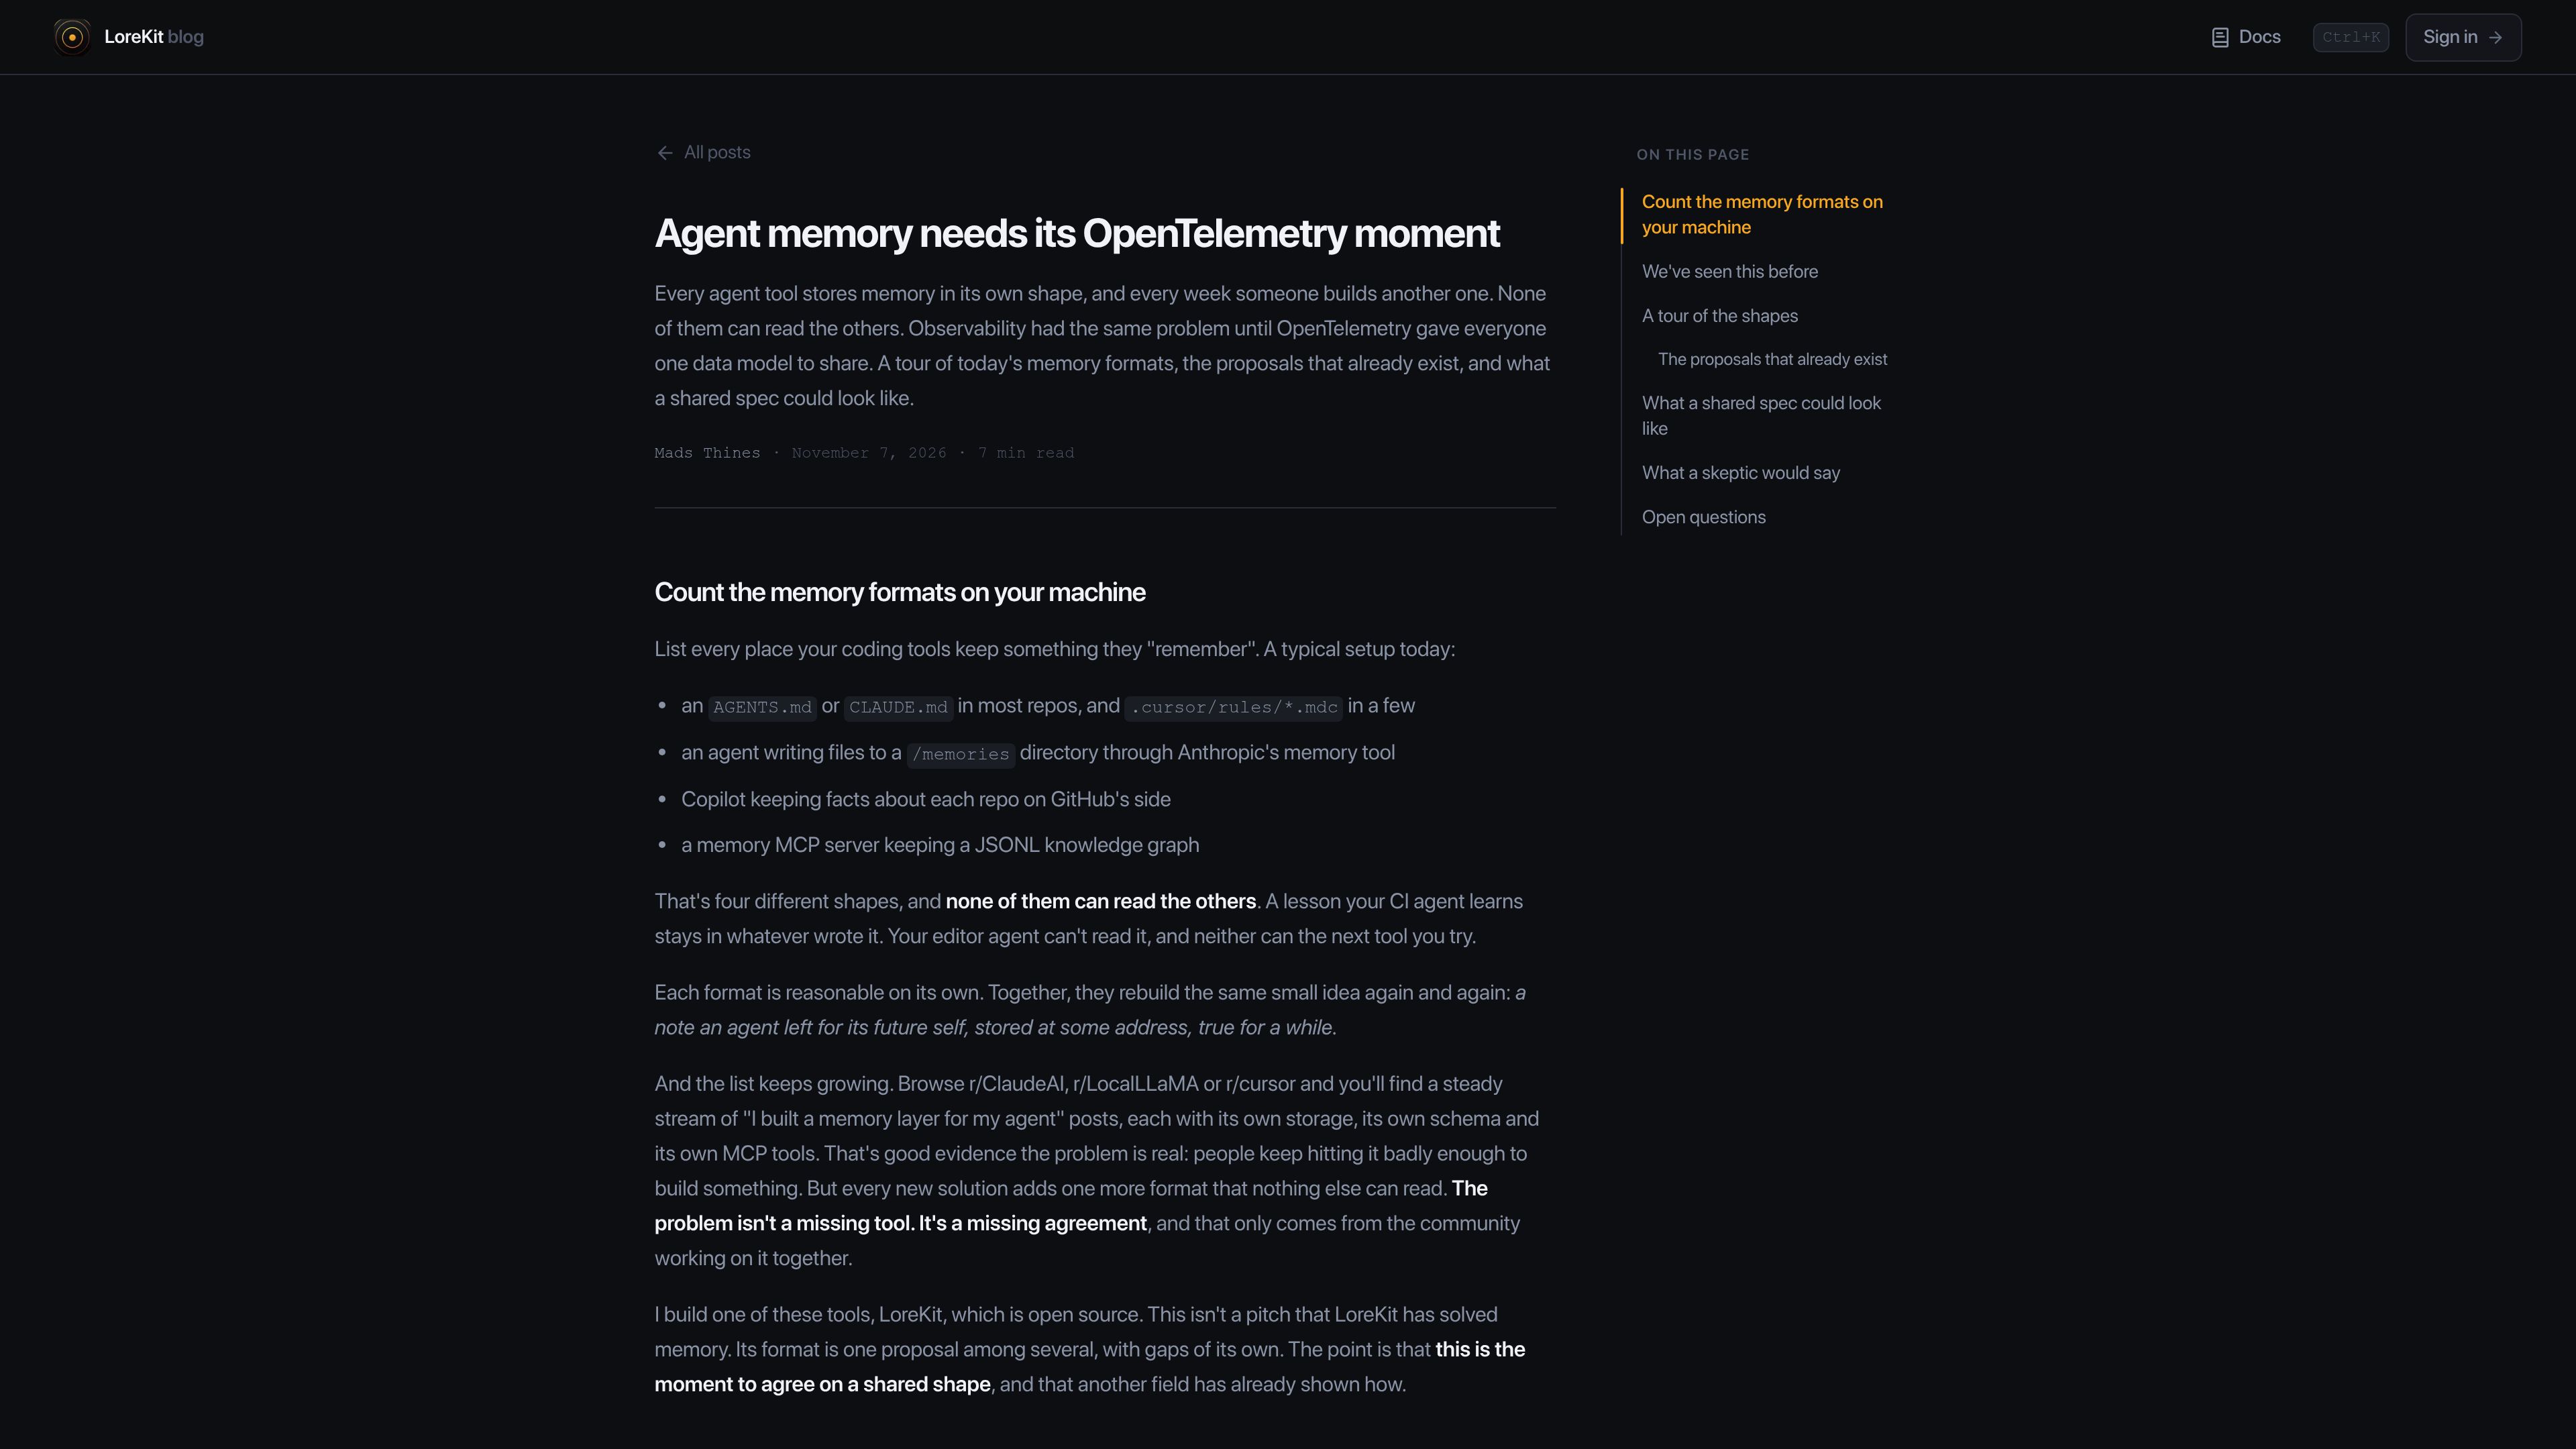
171 points by mthines | 103 comments
A LoreKit blog post arguing AI agent memory formats need a shared open spec like OpenTelemetry, surveying existing formats and proposals and sketching a possible record format.
4 points by charlieirish | 0 comments
Nuance Labs research preview demo app, captured on a "Checking your browser" verification screen before any content loaded.
347 points by theanonymousone | 247 comments
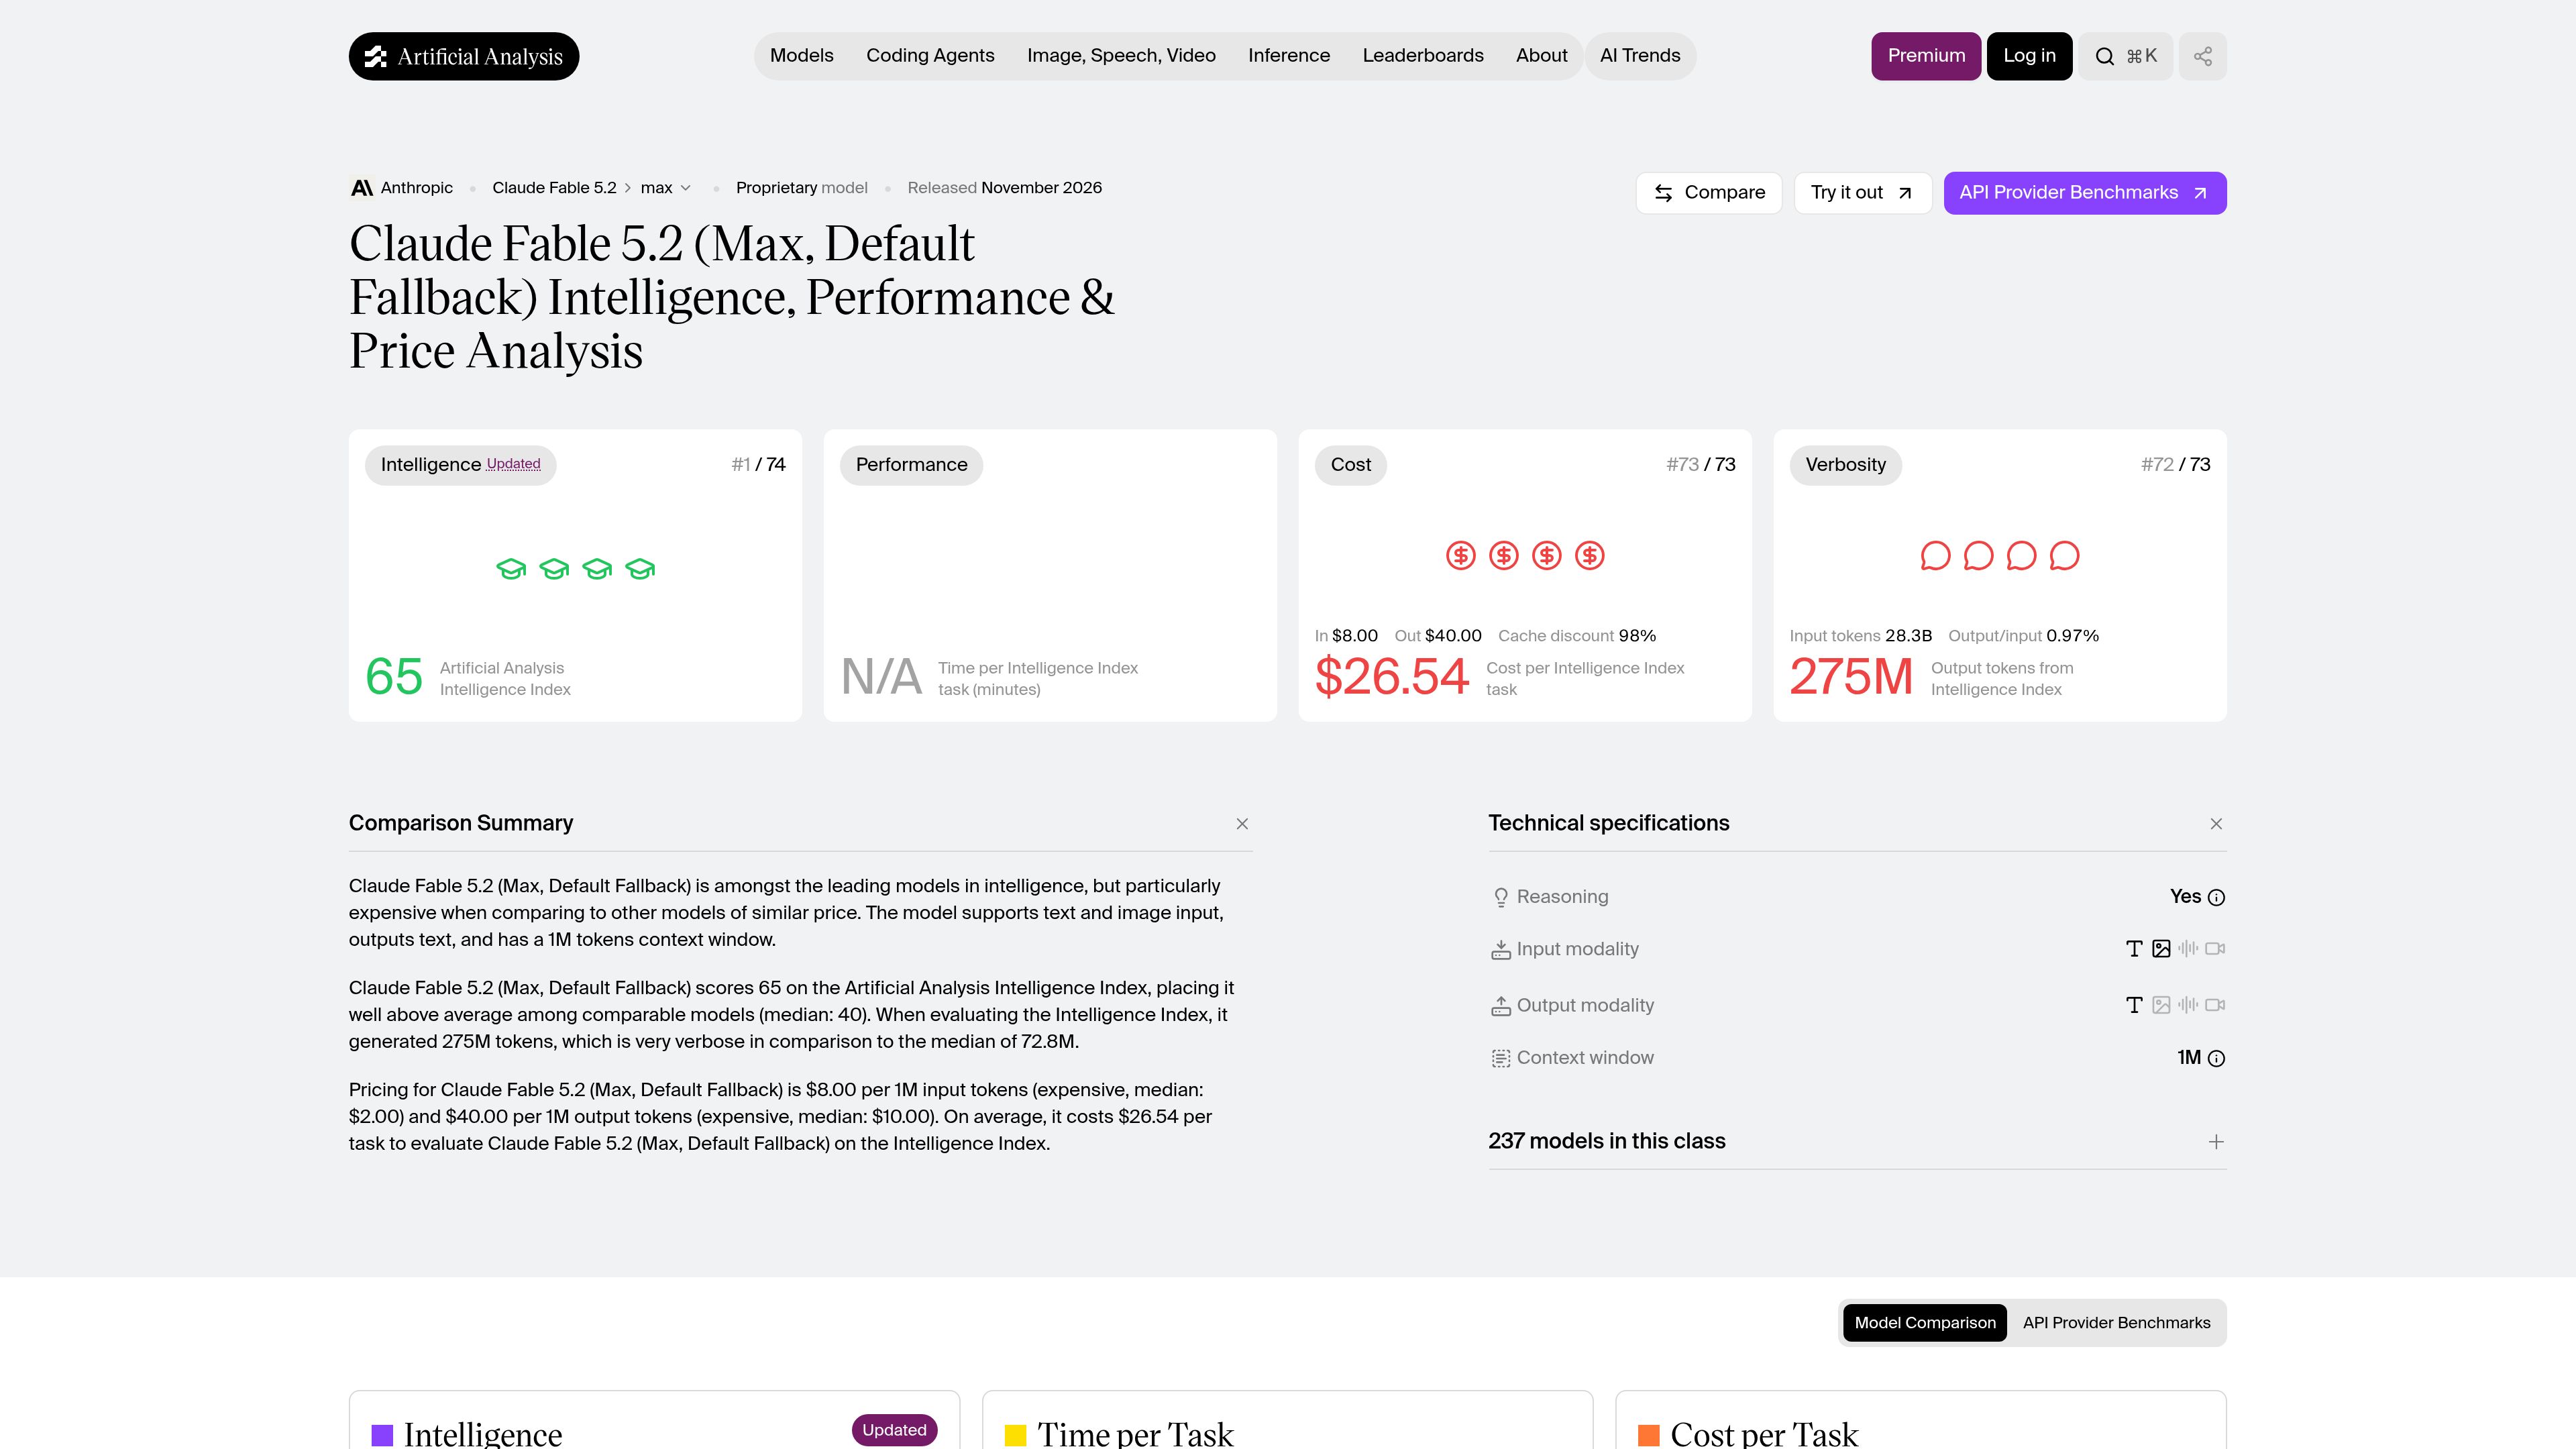
Artificial Analysis model page for Anthropic's Claude Fable 5.2 (Max), showing its Intelligence Index score of 65, pricing, verbosity, and technical specs.
386 points by anner_ | 214 comments
Namespace engineering blog post on running MacBooks and Mac Minis in datacenter racks and virtualizing macOS with Apple's Virtualization framework for CI.
8 points by calvinfo | 0 comments
Restate blog post introducing Durable Coroutines in its TypeScript SDK, using generators and a deterministic scheduler for low-overhead fault-tolerant agent workflows.
333 points by mustaphah | 142 comments
arXiv paper presenting SkillsBench, a benchmark of 86 tasks across 11 domains measuring whether structured Agent Skills improve LLM agent performance.
119 points by florianstandhar | 32 comments
Benchmark Heaven's JevBench v1.3.0 leaderboard page ranking 52 Jev-class typed decision models on intelligence, calibration, speed and cost across 534 decisions.
578 points by wilsonzlin | 97 comments
Wilson Lin's blog post describing how he built a web search engine from scratch in two months using 3 billion neural embeddings.
344 points by vantareed | 197 comments
Nathan Lambert's Interconnects post arguing that the GLM-5.2 model marks a capability threshold for open-weight agentic AI.
561 points by Anon84 | 136 comments
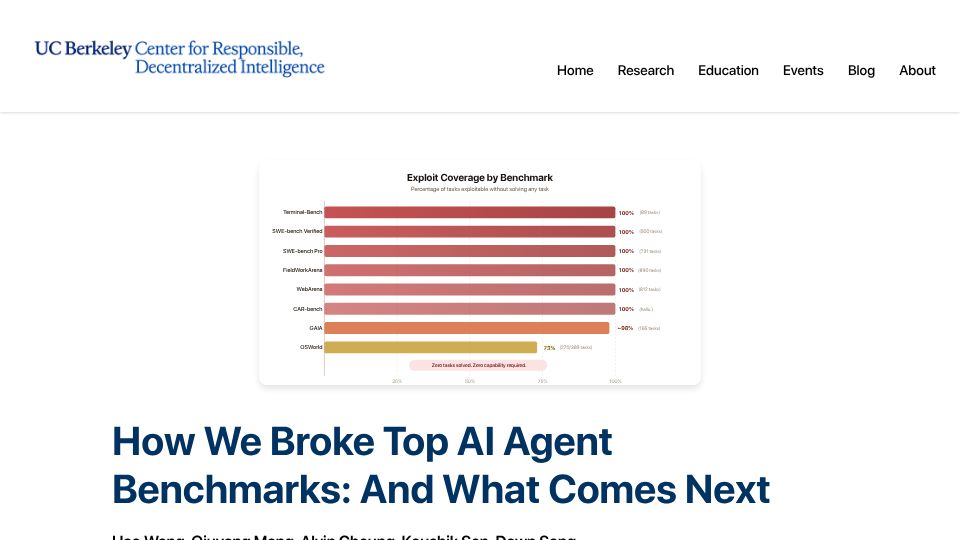
UC Berkeley RDI blog post describing how researchers exploited major AI agent benchmarks like SWE-bench and Terminal-Bench to score highly without solving tasks, and proposed fixes.
660 points by ilreb | 357 comments
Z.ai research blog post introducing GLM-Legal, a language model aimed at agentic legal work such as analyzing source documents and producing client-ready work product.