First screen, captured .
Looks similar
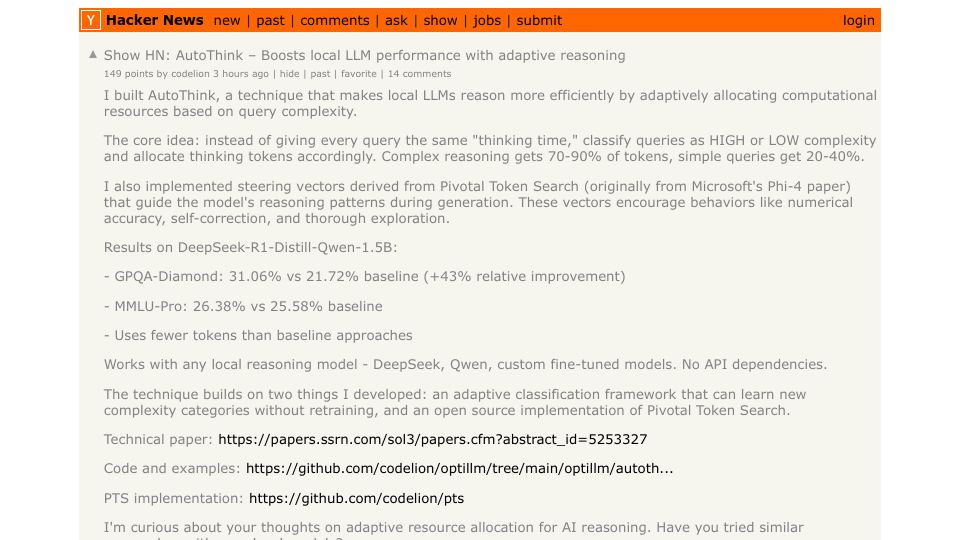
Show HN: AutoThink – Boosts local LLM performance with adaptive reasoning
386 points by codelion | 62 comments
Show HN post introducing AutoThink, a technique that adaptively allocates thinking tokens by query complexity and uses steering vectors to improve local LLM reasoning.
Related stories
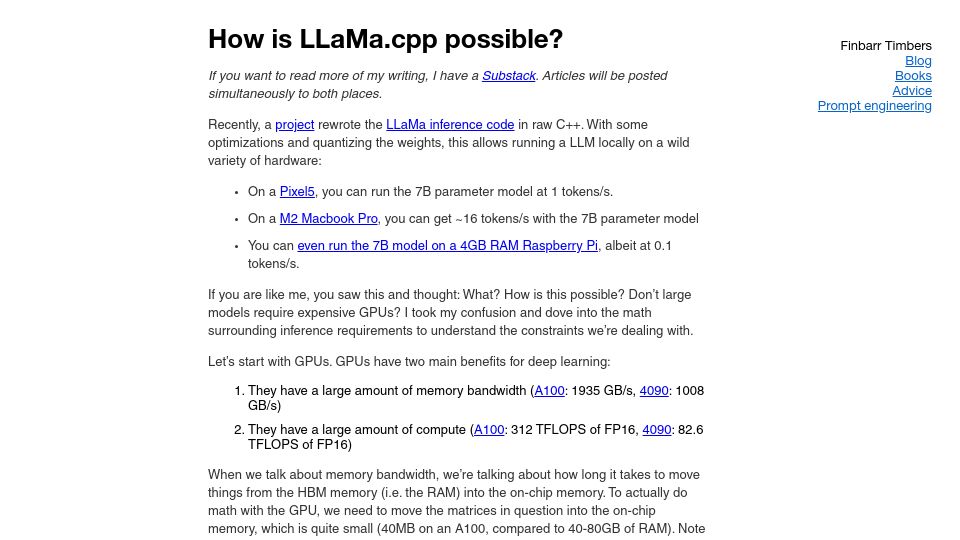
How Is LLaMa.cpp Possible?(finbarr.ca)
648 points by birriel | 210 comments
Blog post by Finbarr Timbers explaining the math of why llama.cpp can run LLaMA models locally on consumer hardware, focusing on memory bandwidth and compute limits.
Llama2.c: Inference llama 2 in one file of pure C(github.com)
659 points by anjneymidha | 158 comments
GitHub repository by Andrej Karpathy for llama2.c, a minimal implementation for running Llama 2 model inference in a single file of pure C.
My finetuned models beat OpenAI's GPT-4(mlops.systems)
376 points by majc2 | 86 comments
Blog post evaluating finetuned Mistral, Llama3 and Solar LLMs against OpenAI's GPT-4 on accuracy for structured data extraction from press releases.
Llamafile lets you distribute and run LLMs with a single file(github.com)
972 points by tfinch | 253 comments
GitHub repository for Mozilla-Ocho's llamafile, a tool to distribute and run large language models as a single executable file.
OpenLLaMA: An Open Reproduction of LLaMA(github.com)
414 points by sadiq | 144 comments
GitHub repository for OpenLLaMA, an Apache-2.0 licensed open reproduction of Meta's LLaMA language model, with a 200B-token preview release.
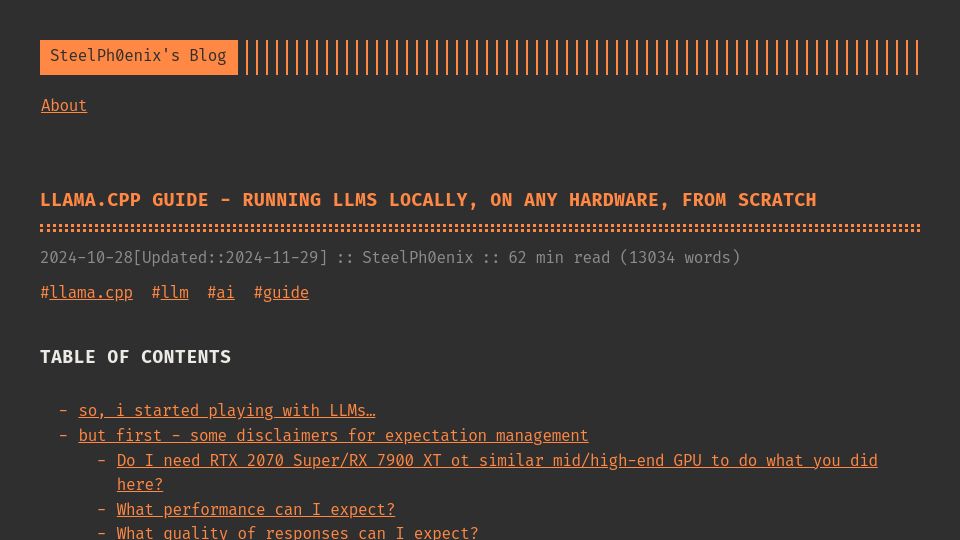
Llama.cpp guide – Running LLMs locally on any hardware, from scratch(steelph0enix.github.io)
318 points by zarekr | 60 comments
A long blog guide on building and running llama.cpp to run large language models locally on various hardware, from scratch.