Guide to running Llama 2 locally(replicate.com)
573 points by bfirsh | 153 comments
Replicate blog post explaining how to run Meta's Llama 2 model locally on M1/M2 Macs, Windows, Linux, and phones without an internet connection.
First screen, captured .
573 points by bfirsh | 153 comments
Replicate blog post explaining how to run Meta's Llama 2 model locally on M1/M2 Macs, Windows, Linux, and phones without an internet connection.
308 points by kristianpaul | 136 comments
648 points by birriel | 210 comments
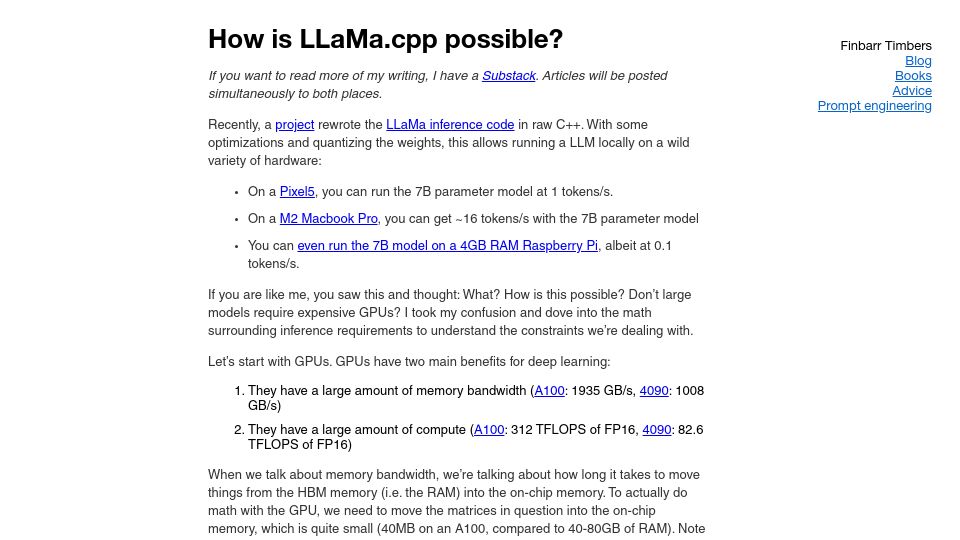
Blog post by Finbarr Timbers explaining the math of why llama.cpp can run LLaMA models locally on consumer hardware, focusing on memory bandwidth and compute limits.
573 points by bfirsh | 153 comments
Replicate blog post explaining how to run Meta's Llama 2 model locally on M1/M2 Macs, Windows, Linux, and phones without an internet connection.
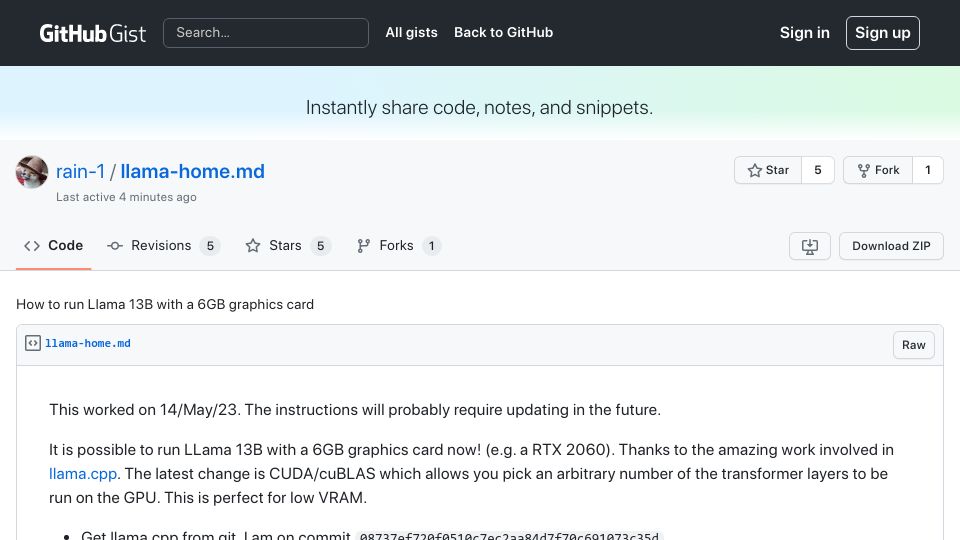
564 points by rain1 | 233 comments
A GitHub Gist with instructions for running Meta's Llama 13B model on a 6GB GPU using llama.cpp's CUDA/cuBLAS layer offloading.
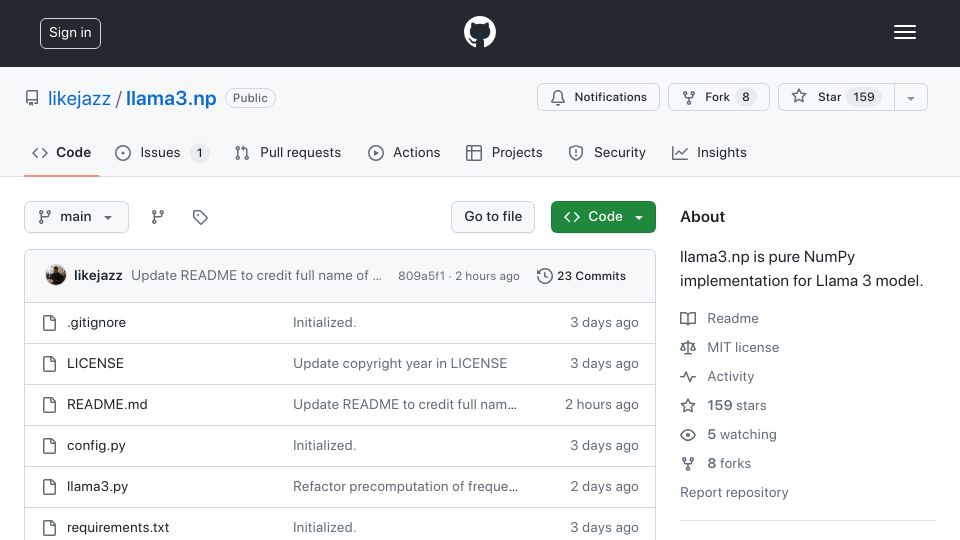
404 points by orixilus | 48 comments
GitHub repository llama3.np, a pure NumPy implementation of the Llama 3 language model for inference.
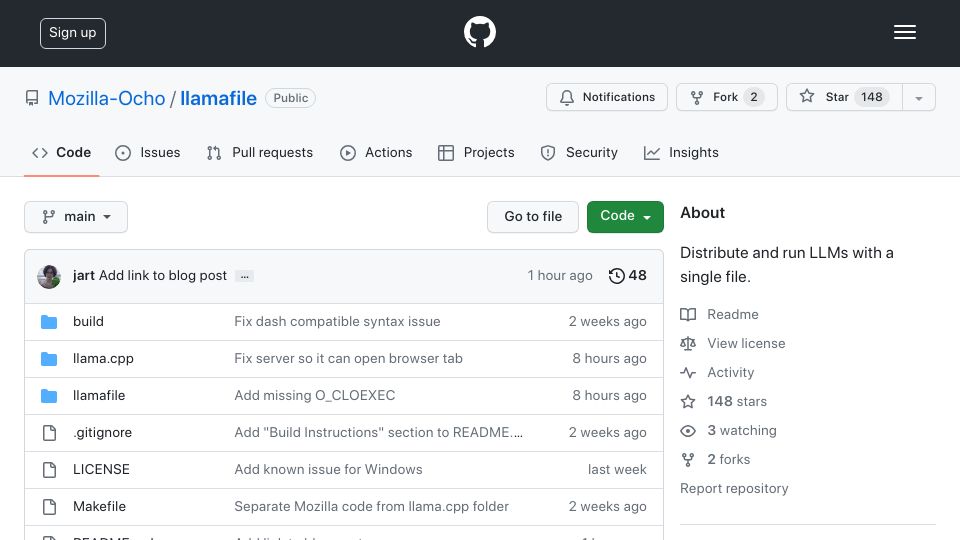
972 points by tfinch | 253 comments
GitHub repository for Mozilla-Ocho's llamafile, a tool to distribute and run large language models as a single executable file.
318 points by zarekr | 60 comments
A long blog guide on building and running llama.cpp to run large language models locally on various hardware, from scratch.