
First screen, captured .
Looks similar
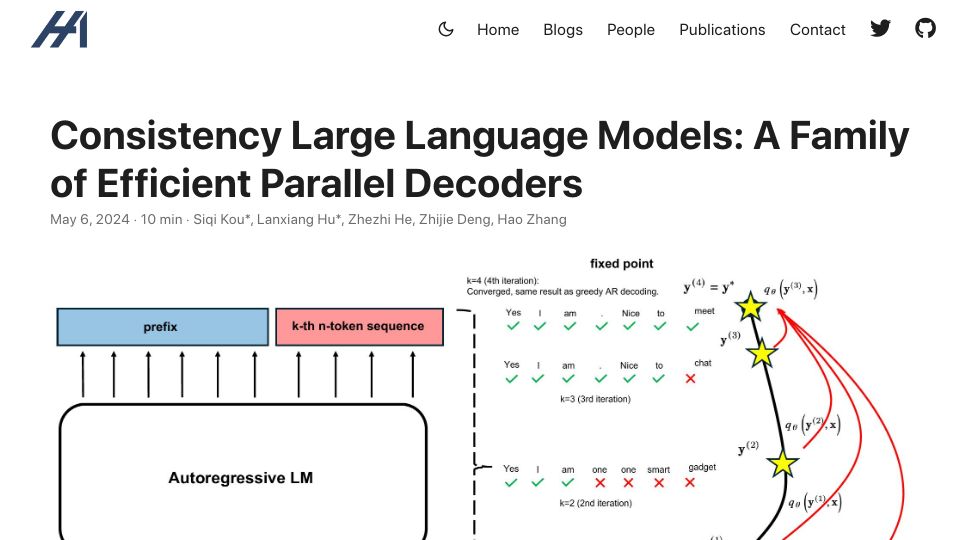
Consistency LLM: converting LLMs to parallel decoders accelerates inference 3.5x(hao-ai-lab.github.io)
447 points by zhisbug | 94 comments
Hao AI Lab blog post introducing Consistency LLMs, a method that fine-tunes LLMs into parallel Jacobi decoders to speed up inference about 3.5x.
Beyond self-attention: How a small language model predicts the next token(shyam.blog)
411 points by tplrbv | 72 comments
A long blog post analyzing how a small ~10M parameter transformer trained from Karpathy's tutorial turns attention outputs into next-token predictions.
Why language models hallucinate(openai.com)
224 points by simianwords | 188 comments